Category Focus/categories/research
Research AI Tools
Discover and compare the best research AI tools and software. Browse 51+ curated tools with reviews and rankings.
Projects tracked
51
Sort mode
RECENT
Page
2
Discover and compare the best research AI tools and software. Browse 51+ curated tools with reviews and rankings.
Projects tracked
51
Sort mode
RECENT
Page
2
Would you pay? is a web product where indie makers show their startup to real people who swipe right if they would pay for it and left if they would not. Makers use it to see real demand instead of likes, and to find out who would pay before they build more. The deck currently holds 102 indie startups and the site reports 6,499 swipes so far. Anyone can start swiping without an account, and makers can add their own startup for free so their card goes into the deck right away. The result makers get is a percentage — the share of people who would pay — plus a view of who those people are and how many of them clicked through to the startup's site. The problem it addresses is that most side projects fail quietly: months of building, then nobody pays. A like, a supportive comment or a spike of attention does not tell a maker whether anyone will actually open their wallet, and those signals often arrive after the work is already done. Would you pay? moves that question to the front of the process. It shows a startup to people browsing a deck of indie projects and asks them one blunt question through a single swipe: would you pay for this? Because the left swipe is as easy to give as the right one, the answer the maker receives is described as real demand rather than applause. Swiping is deliberately simple. Each card in the deck presents an indie startup, and a swiper drags right if they would pay for it and left if they would not. The site describes a right swipe as meaning that the person would pay for the product based on their first impression. It is explicitly not a purchase and nothing is charged — the swipe only tells the maker whether their pitch works. Makers see who would actually pay, which turns the deck into a lightweight demand test rather than a popularity contest. There is no signup required to swipe: the site promises that opening the deck brings up the first card in about a second. For makers, the results view is the core of the product. It reports the share of people who would pay, whether those swipers are developers, founders or marketers, and how many of them clicked through to the startup's site. The percentage only appears after 10 swipes, a rule the site explains as protection against one or two early votes skewing the number. The full breakdown is private to the maker who owns the card, but a public share page for each startup shows the headline percentage once the card passes 10 swipes, so the result is ready to be posted on X. That split matters: the maker keeps the detailed audience and click-through data, while the headline number can be shared publicly as social proof. Makers log in with a one-time email link and no password, which keeps the results view lightweight. Adding a startup costs nothing, and the site states that the card goes into the deck right away. A startup that has been added is then swiped by people who are already browsing, so the maker does not have to recruit an audience of their own to get an answer. Because the same deck mixes indie projects, every swiper sees a stream of products and makes a series of quick willingness-to-pay judgements on the cards that come up. Boost is the optional paid layer. For $19, a card is placed at the front of the deck for 24 hours so that nearly every new swiper sees it first. Up to five cards can be boosted at the same time, and they share the front of the deck in random order rather than a fixed sequence. Boost also carries a guarantee: if the card does not reach 100 swipes within 24 hours, the site keeps boosting it for free until it does. The site is explicit that swipes stay honest under Boost — people still swipe right only if they would pay — so the paid option is positioned as a way to get answers faster rather than a way to buy yes votes. The product's approach rests on a specific claim about what a swipe is worth. The site describes "I'd pay" as intent, not a sale, but argues it is a harder yes than a like, because first impressions decide whether someone clicks through at all. That framing shapes everything else: the swipe is a single, cheap judgement made on a first impression, the percentage is withheld until enough swipes accumulate to be meaningful, and the click-through count adds a second tier of signal for makers who want to know whether the card did more than earn a nod. The outcome for makers is a faster read on whether their pitch lands and who it lands with. Instead of guessing after months of building, a maker gets a percentage of people who would pay, a breakdown of the kinds of people those are, and a count of how many went as far as clicking through to the site. The public share page turns that number into something the maker can post, and the private breakdown shows whether the audience leaning in is made up of developers, founders or marketers. For swipers, the experience is a browsing activity — looking through indie startups and, in one gesture, telling the maker whether the product is worth paying for. Typical use cases follow directly from the deck. A maker with a finished or half-finished side project can add it free and let the deck tell them whether anyone would pay before committing more build time. A maker who needs an answer quickly can pay for Boost, which puts the card at the front for 24 hours and guarantees it reaches 100 swipes or keeps boosting for free. A founder preparing a launch can use the public share page, which reveals the headline percentage after 10 swipes, as material to post on X. And a maker comparing pitches can look at what share of developers, founders or marketers would pay and how many clicked through to the site, using those details to judge which audience the product speaks to. The primary audience is indie makers and founders of side projects — people who build small products and need to know whether there is paying demand before they invest more. The swiping side of the deck is open to anyone with a browser, since no account is needed to start. The product runs on the web, positioning itself around marketing and startup validation rather than around analytics dashboards. Pricing is straightforward: swiping is free, adding a startup and seeing your results is free, and the only paid option is the $19 Boost. Would you pay? reduces a hard question — will anyone pay for this? — to a single swipe and a percentage. By collecting right swipes only when a person would genuinely pay, by hiding the number until 10 swipes are in, and by keeping the detailed audience and click-through breakdown private while publishing a headline figure for sharing, it gives indie makers a real demand signal, not a pile of likes.
ShipWithMuse is a curated directory of what people are building with Meta Muse. The site describes itself as "a catalog of what people build with Muse," and its Product Hunt tagline is "Discover what people are building with Muse." Rather than publishing its own tutorials or demos, it collects real builds from around the web — agents, connectors, apps, games, skills, resources and local Glimmer runs — and presents them in one searchable catalog. Every entry is linked back to its original public source, whether that is an X post, a Reddit thread, a GitHub repository, a YouTube video, a blog resource or a website. It is built for developers, builders and curious observers who want to see the concrete things people have made with Muse rather than read abstract descriptions of the platform. The problem ShipWithMuse addresses is dispersion. Builds made with Meta Muse appear in many different places: developers post screenshots and results on X, hobbyists share custom connectors on the r/MuseAgent subreddit, engineers publish repositories on GitHub, video creators walk through results on YouTube, and writers publish guides and benchmark analyses on their own blogs. Following all of those channels individually is impractical, and much of the work is easy to miss. ShipWithMuse aggregates that material into a single catalog of more than 1,000 builds — the homepage header reads "1079 usecases built now with Muse" — so that anyone evaluating the platform can see what is actually being shipped in practice rather than relying on marketing claims. Because the entries link to their sources, the directory doubles as an index of evidence: benchmarks, demos, repositories and how-to guides that can be checked firsthand. Browsing is organised around build type and page. The catalog lists all 1,079 builds, then offers type filters with their own counts: X posts (462), Reddit posts (124), GitHub (143), Videos (61), Sites (33), Skills (110), Resources (137) and Guides (9). A separate "Star picks" toggle lets visitors show only the curated highlights. Results are paginated — the full catalog spans 27 pages — and each item is presented as a card carrying the creator's handle and avatar, a category label, a like count where one exists, and a direct link out to the original post, repository, video or site. Newly submitted builds are surfaced at the top of the homepage, alongside a prompt inviting visitors to submit their own work. Entries span a wide range of categories, which is itself a picture of what Muse is being used for. Coding & dev tools covers items such as the Browserbase plugin for Muse Code, a guide to Muse Code CLI commands, and the Muse Code Uninstaller utility. Connectors & MCP includes a Linear connector built by Muse in under a minute, the muse-fileapi local file connector, and a developer's guide to building Muse connectors. Games & 3D features five self-playing games written one-shot with Muse Glimmer, a Three.js browser driving demo and a Mini Golf game ported to VR. Benchmarks & research collects tests such as 105 planted bugs pitting Muse Spark 1.3 against frontier models, Spark 1.3's first place on Website Arena, and a privacy teardown of the Muse apps. Other categories reflect the personal-agent side of Muse. Errands & personal agent gathers stories such as a $1,750 unclaimed property find, a $603-a-year car insurance saving, an Alaska flight claim filed from email receipts, and a portfolio-aware Muse feed. Business & commerce covers items like a Squarespace-to-Shopify migration and Shopify Catalog checkout inside Muse. Local & open models collects work on Muse Glimmer, including a free fine-tuning notebook that reports training it faster with less VRAM, and Apps & websites includes builds such as a Tinder-style interface for unfollowing people on Instagram. There is also an Agents & automation category, where projects like TerMuse — a tool that shows a Muse agent's live terminal and an interactive browser side by side — are listed. The site's approach is deliberately indirect: it does not host the builds, run them, or re-publish their instructions. Instead it curates and links. Each listing is a pointer — the description summarises what the build does in a sentence or two, credits the creator by name and handle, and provides an outbound link to the original X post, Reddit thread, GitHub repository, YouTube video, blog resource or website. Visitors can therefore start from the catalog and end up at the primary source, whether that is a repository they can clone, a video they can watch, or a post they can read in full. Submissions are accepted through a dedicated submission page, and the homepage explicitly features newly submitted builds so recently published work gets visibility alongside the wider archive. For anyone assessing Muse, the benefit is a shortcut to evidence. Instead of reading feature lists, visitors can see what has been built, what it cost, what the results looked like, and who did it — for example, a benchmark that measured Muse Spark 1.3 against frontier models on planted bugs, or a report that Muse Glimmer delivered five runnable games at roughly one-fifth of Muse Spark's cost. For builders, the directory is a source of inspiration and prior art: seeing that someone connected Linear in under a minute, taught Muse a custom connector, or drove the Unity CLI to port a game to VR makes it clearer what a next project could look like. And because every card links out, the catalog also acts as a discovery layer for the creators themselves, sending traffic and credit back to their posts, repositories and channels. Concrete uses of ShipWithMuse follow from that structure. A developer new to Muse Code can browse the Coding & dev tools and Connectors & MCP categories to find setup guides, CLI walkthroughs and working connector examples before writing their own. Someone evaluating model performance can go straight to Benchmarks & research and read the collected tests and analyses in one place. A builder looking for project ideas can scan Games & 3D or Apps & websites for examples of what Muse produces in a single file or a short session. Teams curious about the personal-agent capabilities can read the Errands & personal agent entries — flight claims, insurance comparisons, unclaimed property searches — to understand what such workflows look like in practice. And creators can submit their own builds for listing in the catalog. ShipWithMuse is maintained by @mohithkumar808, credited on the site as the curator. It is a web-based catalog. The site also sells sponsorship placements: a sponsored slot the same size as a post, shown every 12 builds on every catalog page, priced at $100 per week, and the site's sponsor strip includes ChatForm and Tgmlabs. The directory draws on a range of build types — X posts, Reddit posts, GitHub repositories, videos, sites, skills, resources and guides — and its Product Hunt listing classifies it under Productivity, Developer Tools and Artificial Intelligence. The through-line is simple: ShipWithMuse turns scattered Muse activity into a single, link-backed catalog. By indexing more than a thousand real builds, letting visitors filter by type and highlight star picks, and pointing every entry at its original public source, it gives developers and observers a practical way to discover what Muse can do — and, if they have built something themselves, a place to submit it.
Cuey is a Chrome extension that lets you compare any AI answer against 30+ models without leaving the AI tool you already use. It sends your prompt to ChatGPT, Claude, Gemini, Grok, DeepSeek and other leading models, then displays their responses side by side in a clean sidebar so you can see what they agree on, what they disagree on, and what your original model missed. It is built for anyone who relies on AI for everyday work and wants a second opinion before acting on a single model's confident-sounding answer. It is free to install, and no account is required to start. AI models deliver wrong answers in exactly the same confident tone as correct ones, which makes it hard to tell when you should trust a response and when you should look closer. Different models also have different strengths: one may reason through a problem better, another may write stronger ad copy, and another may have real-time internet access. Because each tool lives in its own tab, checking a second or third model normally means copy-pasting the same prompt, repeating your context, and juggling multiple subscriptions. Cuey removes that friction by putting the comparison directly where the question was asked, so a second opinion is available at the moment you need it rather than after a manual round trip between browser tabs. The core capability is multi-model comparison. Cuey works directly inside your AI tool, so there is no separate app to learn and no new interface to adopt. You send one prompt to multiple models at once, and Cuey runs it across your selected models before laying the responses out side by side in its sidebar. The free plan includes full side-by-side model comparison and works inside all seven major AI model providers covered by the extension, while cross-checking answers against more than 30 models is available with a daily free limit. Seeing the responses next to each other makes it possible to judge differences in reasoning, tone, and completeness at a glance instead of relying on memory of what another tab produced earlier. Cuey does more than display answers in parallel; it highlights the relationships between them. It shows where models agree, where they diverge, and why the difference matters, plus what your original model missed. Agreement is a signal that you can move forward with more confidence, while disagreement is a signal that the question deserves a closer look before you act. This is the mechanism that turns a wall of competing text into a usable judgment: instead of reading three or four answers and guessing which one to trust, you see the points of consensus and the points of conflict isolated in the sidebar. Memory portability is the second pillar of the product. Cuey lets your context follow you when you move between models, so you never start from zero again. You can import your chat history and memories from ChatGPT, Claude, and Gemini, then carry that context, along with your preferences and history, across supported models. Switching to a different model no longer means re-explaining your project, your tone requirements, or the background of the conversation, because the history you have already built up in one tool stops being trapped there and becomes portable. Cuey is not a replacement for the AI you already pay for. It runs alongside the assistant you use and supplies a second opinion from other models, so people who already have ChatGPT Plus can keep their existing subscription and still see how other models respond. There is nothing to configure: no API keys are required and no account is required to start, and side-by-side comparison, cross-checking, and multi-language support are free, with a daily free limit on the 30+ model cross-check. Cuey accesses the page content needed to provide model comparison and context features, and the developer states that your data is not sold to third parties and is not used for purposes unrelated to the extension's core functionality. The practical outcome is fewer bad decisions made on the back of a single confident-sounding answer. Because the comparison happens in place, there is no copy-pasting, no tab-switching, and no guessing, and users do not need to take on extra subscriptions to hear from more than one model. The extension also saves the time that would otherwise go into re-establishing context each time you try a new model, and it gives you a repeatable check before you commit to an answer in writing, analysis, or research. When the models agree, you can move on with more confidence; when they do not, you know to investigate further. Concrete workflows in the content include checking an AI-generated answer before acting on it, which is the scenario the extension is built around: catching a confident-sounding wrong answer before it burns you. Writers can compare how different models handle the same brief, such as ad copy, where models are described as having different strengths. Questions that depend on current information benefit from including models with real-time internet access in the comparison alongside models without it. People who move between AI tools can carry their imported history and preferences so each new model starts with context rather than a blank slate. And because comparison, cross-checking, and multi-language support are free, the workflow can be tried without a subscription commitment. Cuey is delivered as a Chrome extension published by Llama Valley Inc and distributed through the Chrome Web Store, where the listing shows version 0.1.20.9, an install size of 8.9MiB, and support for 8 languages: Deutsch, English, español, français, italiano, português (Brasil), 中文(中国), and 日本語. The listing notes that the extension offers in-app purchases and places it under Productivity / Tools within the Extensions category. The free tier covers side-by-side comparison, cross-checking with a daily free limit, and multi-language support, all with no account required, while the publisher's stated mission is to make AI easier to use and more useful for everyday work. Cuey's value proposition is straightforward: the AI answer you already have is only one opinion, and a confident tone is not evidence of correctness. By comparing that answer against 30+ models inside the tool where the question was asked, surfacing where models agree and disagree, and carrying your context between models, Cuey makes a second opinion a normal step rather than a chore. It is free to install, requires no account to start, and adds no extra subscription if you already pay for an AI assistant.
Inqueria is an AI-moderated qualitative research platform. According to its website, it deploys qualitative research studies and interviews customers along adaptive conversational paths, then extracts cross-session themes in seconds. It runs interviews the way a trained researcher would: adapting to every answer, probing deeper when responses are thin, and following threads the study designer did not anticipate. It is built for product teams, researchers, and consultants who need qualitative depth at scale — the site notes it is used by top product teams at fast-growing startups. The stated promise is to run 50 deep interviews overnight, letting teams set up a research guide in under five minutes and host audio conversations with participants anywhere in the world. The problem Inqueria addresses is the bottleneck at the heart of qualitative research. A human researcher runs one interview at a time, meaning a study of 50 conversations can take a month just to schedule, let alone conduct and analyse. Once interviews are recorded, someone still has to manually code transcripts to find themes, and that coding is slow and hard to trace back to the raw evidence. Survey tools, meanwhile, cannot follow up on an interesting answer or explore a thread that emerges mid-conversation, so they reach breadth but not depth. Inqueria's positioning is direct: stop manual transcript coding, and skip the month it takes to schedule five interviews. Instead of a scheduling queue, the platform conducts conversations concurrently and turns them into evidence-linked themes. The first stage is research design. A researcher describes their research objective in plain English — for example, understanding why new users churn within their first week and what would have made them stay — along with the audience and the desired tone. Inqueria then generates a complete question plan with a system prompt, follow-up probes, and an ideal conversational flow, ready to share in under five minutes, with no scripting or guesswork required. The platform also applies methodological rigor: rather than defaulting to one interview style, it recommends the best-fit method from a rigorous toolkit and tells the researcher why, and the recommendation can be overridden at any time. The stated toolkit includes Jobs-to-be-Done, Laddering, Critical Incident, Journey, Evaluative, Phenomenological, and Semi-structured methods. The site gives the example of a Jobs-to-be-Done approach being auto-selected for discovery and switching decisions, identifying the progress people seek, the struggle that triggered it, and the forces pulling them toward or away from a switch. The second stage is adaptive interviewing. Participants join through a secure link and speak directly with Inqueria, answering questions such as 'Can you walk me through the specific moment you realised the onboarding wasn't working for your team?' The AI listens, probes deeper when answers are thin, and follows threads the researcher did not anticipate — all without a human moderator. Sessions can be anonymous and show progress such as 'Question 3 of 8', and participants can either speak their answer or type a response. Concurrency is a core design principle: a human researcher runs one interview at a time, while Inqueria runs as many as the plan allows at once, with no calendar to fill. The website describes this as unlimited parallel capacity in its summary, with response limits applied by plan. The third stage is synthesis and a compounding research library. One click surfaces cross-session themes, sentiment, and verbatim quotes that back up each theme. Inqueria goes further than a single study: it surfaces cross-study patterns, theme saturation, and response-level engagement signals, and every study adds to the research library so patterns surface across all of a team's work. The site's illustrated synthesis example shows 148 sessions, top themes such as 'Invite links expire too quickly' at 83% and 'Feature discovery is accidental' at 67%, a sentiment score of Net +41, an engagement signal noting that 23 respondents described setup as 'fine' but hesitated and backtracked, a compounding marker indicating a theme also appeared in three past studies, and saturation reached at 142 interviews. The Product Hunt listing adds that each theme is checked against every transcript and the platform shows the participants who disagree. Privacy is built into the workflow rather than added on top. Inqueria performs automated PII redaction in-house: it detects and strips names, emails, phone numbers, IDs, and addresses before any data leaves Inqueria, and the company states that redaction happens before any model sees a transcript. Configurable data-retention policies are also provided. The site illustrates this with raw input such as 'My name is John and I work at Apple…' becoming 'My name is [REDACTED] and I work at [REDACTED]…'. Taken together, the overall approach is a three-step loop: design the interview from a plain-English objective, let Inqueria conduct adaptive conversations concurrently, and then read evidence-linked themes from a library that compounds with each new study. The stated average setup time is five minutes, with instant AI generation. The stated benefits follow from that approach. Teams get interviews that hold up methodologically while removing the scheduling queue, because Inqueria interviews concurrently instead of one at a time. Setup takes about five minutes rather than requiring a hand-scripted guide, and the question plan is generated instantly. Analysis is compressed into one-click thematic synthesis, so researchers see themes, sentiment, and the exact quotes behind them without manual transcript coding. Because themes are linked to quotes and checked against every transcript, findings are traceable rather than impressionistic, and reviewers can see the participants who disagree. And because every study contributes to a shared research library, patterns compound across projects, with cross-study recurrence and theme saturation visible as evidence that a finding is well supported. Strategic use cases on the site cover every kind of qualitative discovery. Customer Discovery is framed around uncovering the jobs, triggers, and switches behind why people choose a product or don't — with an example question such as 'When did you first realise the alternatives weren't solving your problem?' Other listed use cases include Churn & Retention, Market Validation, Concept & Packaging, Brand Perception, Employee Experience, Academic Research, Community & Policy, and 'something else entirely.' A churn study, for instance, would use the design flow described on the homepage: an objective about why new users churn in their first week, an audience of recently churned users, a warm and professional tone, and an AI-generated eight-question plan. The Product Hunt description frames the overnight scenario: run 50 interviews overnight instead of spending a month scheduling five. Inqueria's plans indicate who it is for. The free Explore tier runs 3 free qualitative interviews with no card required and includes 1 active study, the qualitative AI agent, and 10 insight refreshes per month. Research, at $55 USD per month, is described as designed for freelance researchers and UX teams and includes 30 interviews per month with unused interviews rolling into the next month (capped at one month's allowance), 5 active studies, thematic synthesis and sentiment, 15 insight refreshes per month, Excel spreadsheet data export, and a custom AI interview persona. Consultant, at $109 USD per month, is best for consulting teams sharing findings with clients and adds 75 interviews per month, 10 active studies, 30 insight refreshes per month, a client read-only insights share link, and removal of Inqueria branding from the participant page. Scale, at $169 USD per month, is for larger corporate teams conducting research and includes 5 team seats, 150 interviews per month, unlimited active studies, 50 insight refreshes per month, and personalised email distributions. Enterprise offers unlimited interviews, studies, and seats, SSO and security review, and dedicated support on custom pricing. A one-off study pack with 20 interviews that never expires costs $35 USD. The site notes GST is added at checkout for Australian customers, with AUD billing. In short, Inqueria is a qualitative research platform whose value proposition is evidence-linked speed: AI-moderated interviews that adapt like a trained researcher, in-house PII redaction before any transcript reaches a model, and one-click synthesis into themes with the exact quotes behind them. It replaces the scheduling queue and manual transcript coding with concurrent interviews and a research library that compounds across every study.
Anthropologic is a zero distance consumer research platform that reads the whole internet through its Human Context Protocol to uncover consumer, category and cultural truths. It is built for people who need consumer understanding that is both fast and deep: research, innovation, marketing and foresight teams who cannot wait weeks for fieldwork but also cannot act on shallow social listening. The platform covers 239 markets and more than 100 languages, and it organises its capabilities into nine workflows, each aimed at a different type of question — what is moving in a category, what people think and feel, how segments behave online, what futures are probable, how creative performs, how a brand is read across social, search and LLMs, and where a brand can stand within a market's cultural codes. The promise is straightforward: research, innovation and foresight answers in minutes. Traditional research is deep but slow. Social listening is fast but shallow. LLMs are fluent but culturally blind. That is how Anthropologic frames the state of consumer insight, and it is the gap the platform exists to close. Deep research — surveys, ethnographic work, segmentation studies — produces trustworthy understanding, but it arrives on a timeline that rarely matches the pace at which categories move. Social listening moves at the speed of the feed but tends to capture volume and sentiment rather than meaning, leaving researchers to guess at the cultural logic underneath. Large language models can generate convincing text about consumers, yet by the platform's own description they lack cultural grounding, so their fluency masks a blindness to the codes that actually govern a market. Anthropologic positions itself between these three approaches: fast like listening, interpretive like research, and grounded in cultural context rather than surface fluency. For teams making decisions about products, positioning and communication, that combination matters because the cost of being slow is measured in missed trends, and the cost of being shallow is measured in misread consumers. The first group of workflows answers the question of what is happening. Trends shows what is moving in a category, pairing social proof with search patterns so that a signal is visible both in conversation and in demand. The live trend examples shown on the site make the shape of the output concrete: a search volume for alcohol-free club nights in the UK, a multiple showing how many scents now sit in a wardrobe where a single signature perfume once did, the number of US stores stocking overnight oats, or a search rate for Filipiniana bridal looks. Discourse goes a layer deeper and covers what people think, say and feel, mapping the positions, tensions and narratives inside a conversation rather than stopping at sentiment. Digital Segmentation takes the behavioural record and turns it into psychographic segments based on online behaviours, so teams can see not only that a category is moving but which kinds of people are moving it and with what mindset. Once a team knows what is happening, the next group of workflows helps it look forward and test. Foresight Simulator uncovers probable future scenarios reshaping a category, giving innovation and strategy teams a structured way to consider what comes next instead of relying on a single forecast. Synthetic Survey simulates consumer responses at scale using cultural ontologies, which allows researchers to explore how different audiences would respond without running a full field study for every hypothesis. Creative Evaluation scores a video ad for cultural strength across grounded signals, endorser and pillars, turning creative judgement into something that can be assessed against cultural evidence rather than taste alone. Together these workflows cover the middle of the research process: the stage where teams need to stress-test ideas, creative and scenarios before committing budget to production or media. Interpretation comes next. Ask an Anthropologist interprets an insight using cultural codes, giving teams a way to ask what a signal actually means rather than only what it says. Brand Performance shows how a brand performs across Social, Search and LLM, extending brand tracking into the place where many consumers now form impressions — the answers language models give. Cultural Semiotics reads a space in a market: the codes that govern it, the tensions between them, and where a brand can stand, which is directly useful for positioning work. The site also lists Innovation as coming soon, described as identifying opportunity spaces through convergence modelling and developing novel concepts, alongside a Research Thinking section where longer-form perspectives are published, with example essays such as 'Death of the Sugar High', 'Future of Fashion is Value', 'Medicalized Mouth', 'Beyond Classrooms' Four Walls' and 'Redesigned: Future of Aging'. The overall approach is what Anthropologic calls the Human Context Protocol: the platform reads the whole internet, rather than a single social network or a survey panel, and interprets what it finds through cultural context instead of raw keyword matching. Nine workflows sit on top of that reading, each packaged as a launchable tool with a defined question and a defined output, so a researcher does not have to assemble a methodology from scratch. Coverage is broad by design — 239 markets and 100+ languages — which means the same method can be applied across geographies and language communities rather than only in the markets where a team happens to have local researchers. The workflows range from descriptive (Trends, Discourse, Digital Segmentation) through projective (Foresight Simulator, Synthetic Survey, Creative Evaluation) to interpretive (Ask an Anthropologist, Cultural Semiotics) and diagnostic (Brand Performance). The through-line is that every output is meant to be grounded in something observable — social proof, search patterns, online behaviours, cultural codes or ontologies — rather than in a model's unaided opinion. The stated benefit is speed without sacrificing depth: research, innovation and foresight answers in minutes. For a category team, that means trend questions can be answered while a campaign or product decision is still open, rather than in a retrospective deck delivered after the moment has passed. For innovation teams, probable future scenarios and simulated consumer responses reduce the cost of exploring many hypotheses before narrowing to the few worth real investment. For brand and marketing teams, scoring creative for cultural strength and tracking performance across social, search and LLM gives a more complete picture of how a brand is actually being read. And because the platform works across 239 markets and 100+ languages, the same questions can be asked consistently in many places at once, which is difficult to do with traditional fieldwork and easy to get wrong with a culturally ungrounded model. The result is fewer decisions made on instinct alone and fewer insights that arrive too late to use. Concrete scenarios follow from the workflow list. A beauty or fashion brand tracking a new behaviour — the site's own examples include Gen Z fragrance, secondhand shopping, slow fashion and beauty after GLP-1 — would use Trends to see whether the movement shows up in both conversation and search, then Discourse to understand the narratives around it, and Digital Segmentation to identify which psychographic groups are driving it. A creative team preparing a video ad would run it through Creative Evaluation to score its cultural strength against grounded signals, endorser and pillars before committing media spend. A strategy team planning ahead would use Foresight Simulator to unpack probable future scenarios in a category and Synthetic Survey to test how consumers might respond. A brand lead would use Brand Performance to compare how the brand reads across Social, Search and LLM, and Cultural Semiotics to understand the codes and tensions in a market and where the brand can credibly stand. A researcher holding an ambiguous insight would use Ask an Anthropologist to interpret it through cultural codes. The Research Thinking section shows how those outputs are turned into published perspective pieces across topics such as fashion, education, wellness, entertainment and sportswear. Anthropologic is aimed at research, innovation and foresight functions — the product description names research, innovation and foresight answers explicitly — as well as the marketing and brand teams that consume that work. The scope is global by default: 239 markets and 100+ languages, covering categories visible in the platform's own examples, such as beauty, fashion, travel, fitness, food and drink, entertainment, education, wellness, pets and motherhood. No pricing or plan details appear on the page, and no specific third-party integrations are listed; the data domains the product describes are Social, Search and LLM, plus the platform's own cultural ontologies and semiotic codes. The product is delivered on the web at anthropologic.quilt.ai, and its Product Hunt listing categorises it under Marketing, Artificial Intelligence, and Data & Analytics. Anthropologic's core proposition is zero distance: closing the gap between a consumer signal and the decision it should inform. By combining a Human Context Protocol that reads the whole internet with nine purpose-built workflows spanning 239 markets and 100+ languages, it offers research depth at listening speed — trends with social proof and search patterns, discourse with tensions and narratives, psychographic segmentation, foresight scenarios, creative scoring, synthetic surveys, cultural interpretation, brand performance across social, search and LLM, and semiotic reading of a market. The takeaway is that cultural context, not fluency alone, is what makes consumer insight usable.
Web Search Agents by Nimble are self-learning agents that become experts at your specific research task. They are web crawling and research agents built for a specific domain — company enrichment, regulations research, and other focused use cases — and they crawl the web with surgical accuracy. Instead of returning generic results, the agents self-learn your use case to go deeper into the sources that matter most to you, giving your AI deeper and more relevant web context. The product is aimed at agent builders and teams that need expert-level web search for their AI agents, delivering higher accuracy at a fraction of the token cost. You can start by giving your AI the Nimble agent onboarding link, start building for free, or book a demo with the team. Web search is usually judged on generic benchmarks that do not resemble the queries a real agent builder faces. Nimble evaluates web search by domain instead, because that lets agent builders judge solutions against queries that resemble their own rather than generic benchmarks. Nimble argues that specialized intelligence needs a specialized web search, and invites teams whose domain is not listed to contact the company to see how Web Search Agents adapt to their use case. A second problem is cost: retrieving web context typically means redundant searches and parsing raw pages with an LLM, which consumes tokens. Nimble positions Web Search Agents as a way to retrieve exactly what is needed — with no redundant searches and no parsing of raw pages with an LLM — so teams get expert-level web search for their AI agents with higher accuracy at a fraction of the token cost. Web Search Agents are built to execute hyper-specific research workflows, crawling the web with surgical accuracy for the task at hand. They can also build and enrich web datasets: you define your schema and the agents return consistent results on every run, which makes it practical to assemble structured web data without manual cleanup. A monitoring capability, currently in beta, lets you continuously track any data point on any webpage in real time, so changes on the web surface as they happen. Together these three capabilities — hyper-specific research, schema-driven dataset building, and continuous monitoring — cover the common shapes of web data work an agent needs to perform, from answering a single research question to maintaining a dataset that stays current. Three capabilities underpin how the agents adapt to your use case and self-improve. First, compounding domain knowledge: the agents accumulate web context over time to master your domain, so their understanding of relevant sources grows with use. Second, deep web access for your sources: the agents combine web search with domain crawling to reach subpages that other tools cannot access, which matters when the useful information sits deeper than a top-level page. Third, full control over search methodology: the agents retrieve data within the scope and guardrails defined by your search plan, so you decide what is in bounds. Nimble summarizes this as agents that adapt to your use case and self-improve, rather than behaving the same way for every customer and every query. Governance is part of the design. Web Search Agents operate with full governance and control through auditable Search Plans that show exactly what was searched, where, and why — so you can inspect the path the agent took rather than trusting an opaque set of results. Accuracy compounds over time through a Proprietary Index and Memory that gets smarter with every query, meaning the agents retain and reuse what they have learned. The same retrieval discipline addresses cost: by retrieving exactly what is needed, the system avoids redundant searches and avoids the expense of parsing raw pages with an LLM. These three elements — auditable Search Plans, compounding memory, and precise retrieval — are the core promises Nimble makes for expert-level web search delivered to AI agents. The overall approach is that the agents self-learn your use case. Rather than being configured once and left static, Web Search Agents learn from the searches they run, building a memory and a Proprietary Index that improve the relevance of later results. They combine two access paths — web search and domain crawling — to reach both broad results and the deeper subpages that other tools cannot access. Each retrieval stays inside the scope and guardrails you define for the search plan, and every search is recorded so you can audit what was searched, where, and why. Nimble describes this as specialized intelligence for a specialized web search, and documents an onboarding path so your AI agent can be pointed at the product and begin building. The stated benefits concentrate on accuracy and cost. Nimble says Web Search Agents deliver expert-level web search for your AI agents with higher accuracy at a fraction of the token cost. Because retrieval returns exactly what is needed, there are no redundant searches and no need to parse raw pages with an LLM — two of the main sources of token spend in agentic web research. Accuracy compounds over time as the Proprietary Index and Memory get smarter with every query, so results improve rather than plateau. Control and trust are the other stated outcomes: auditable Search Plans show exactly what was searched, where, and why, and the agents work within the scope and guardrails you set, which makes it easier for teams to explain how a result was produced. Nimble publishes cookbook examples of what teams can build. Company research and due diligence can be run from a single prompt at audit grade. Teams can research case laws and regulations, enrich dependencies with health indicators, and find assortment gaps on the digital shelf. Retail and brand teams can find where products are sold to enforce MAP compliance, and go-to-market teams can discover businesses that match an ideal customer profile. Finance workflows include tracking analyst earnings predictions against actuals, and recruiting workflows include building a dataset of job candidates. Nimble also names the domains it evaluates and adapts to: market analysis, real estate, social media monitoring, travel and hospitality, company research, finance, product intelligence, and GTM. In those benchmarks, contestants independently completed 96 tasks per domain — covering reports, enrichment, and discovery — with each result graded fact-by-fact by an independent AI judge against a gold standard built without any contestant's input. Web Search Agents are aimed at agent builders and teams that need their AI agents to research the web reliably. Nimble says it is trusted by organizations including Databricks, Qudo and Uber under a "Trusted By" heading, and its site also displays a broader logo wall featuring brands such as Microsoft, Coca-Cola, L'Oréal, LG, TripAdvisor, Semrush and Browserbase. Native integrations are offered including Anthropic, GPT, LangChain and Vercel, and the product is documented as a Nimble SDK with an agent onboarding page you can give to your AI to get started. Security and compliance features include zero data retention, flexible PII masking, audit logs, data encryption in transit, and no training, alongside CCPA, GDPR and SOC 2 badges. Nimble invites teams to start building for free, try the product now, or book a demo to discuss use cases and see how Nimble delivers higher accuracy at a fraction of the token cost. For teams building AI agents that need reliable web context, Web Search Agents by Nimble offer a self-learning approach: agents that adapt to your domain, crawl the web with surgical accuracy, build and enrich datasets against your schema, and monitor pages for change. Auditable Search Plans provide governance, while a Proprietary Index and Memory compound accuracy over time and precise retrieval reduces token cost. The result is deeper, more relevant web context for your AI, evaluated by domain against queries that resemble your own rather than generic benchmarks.
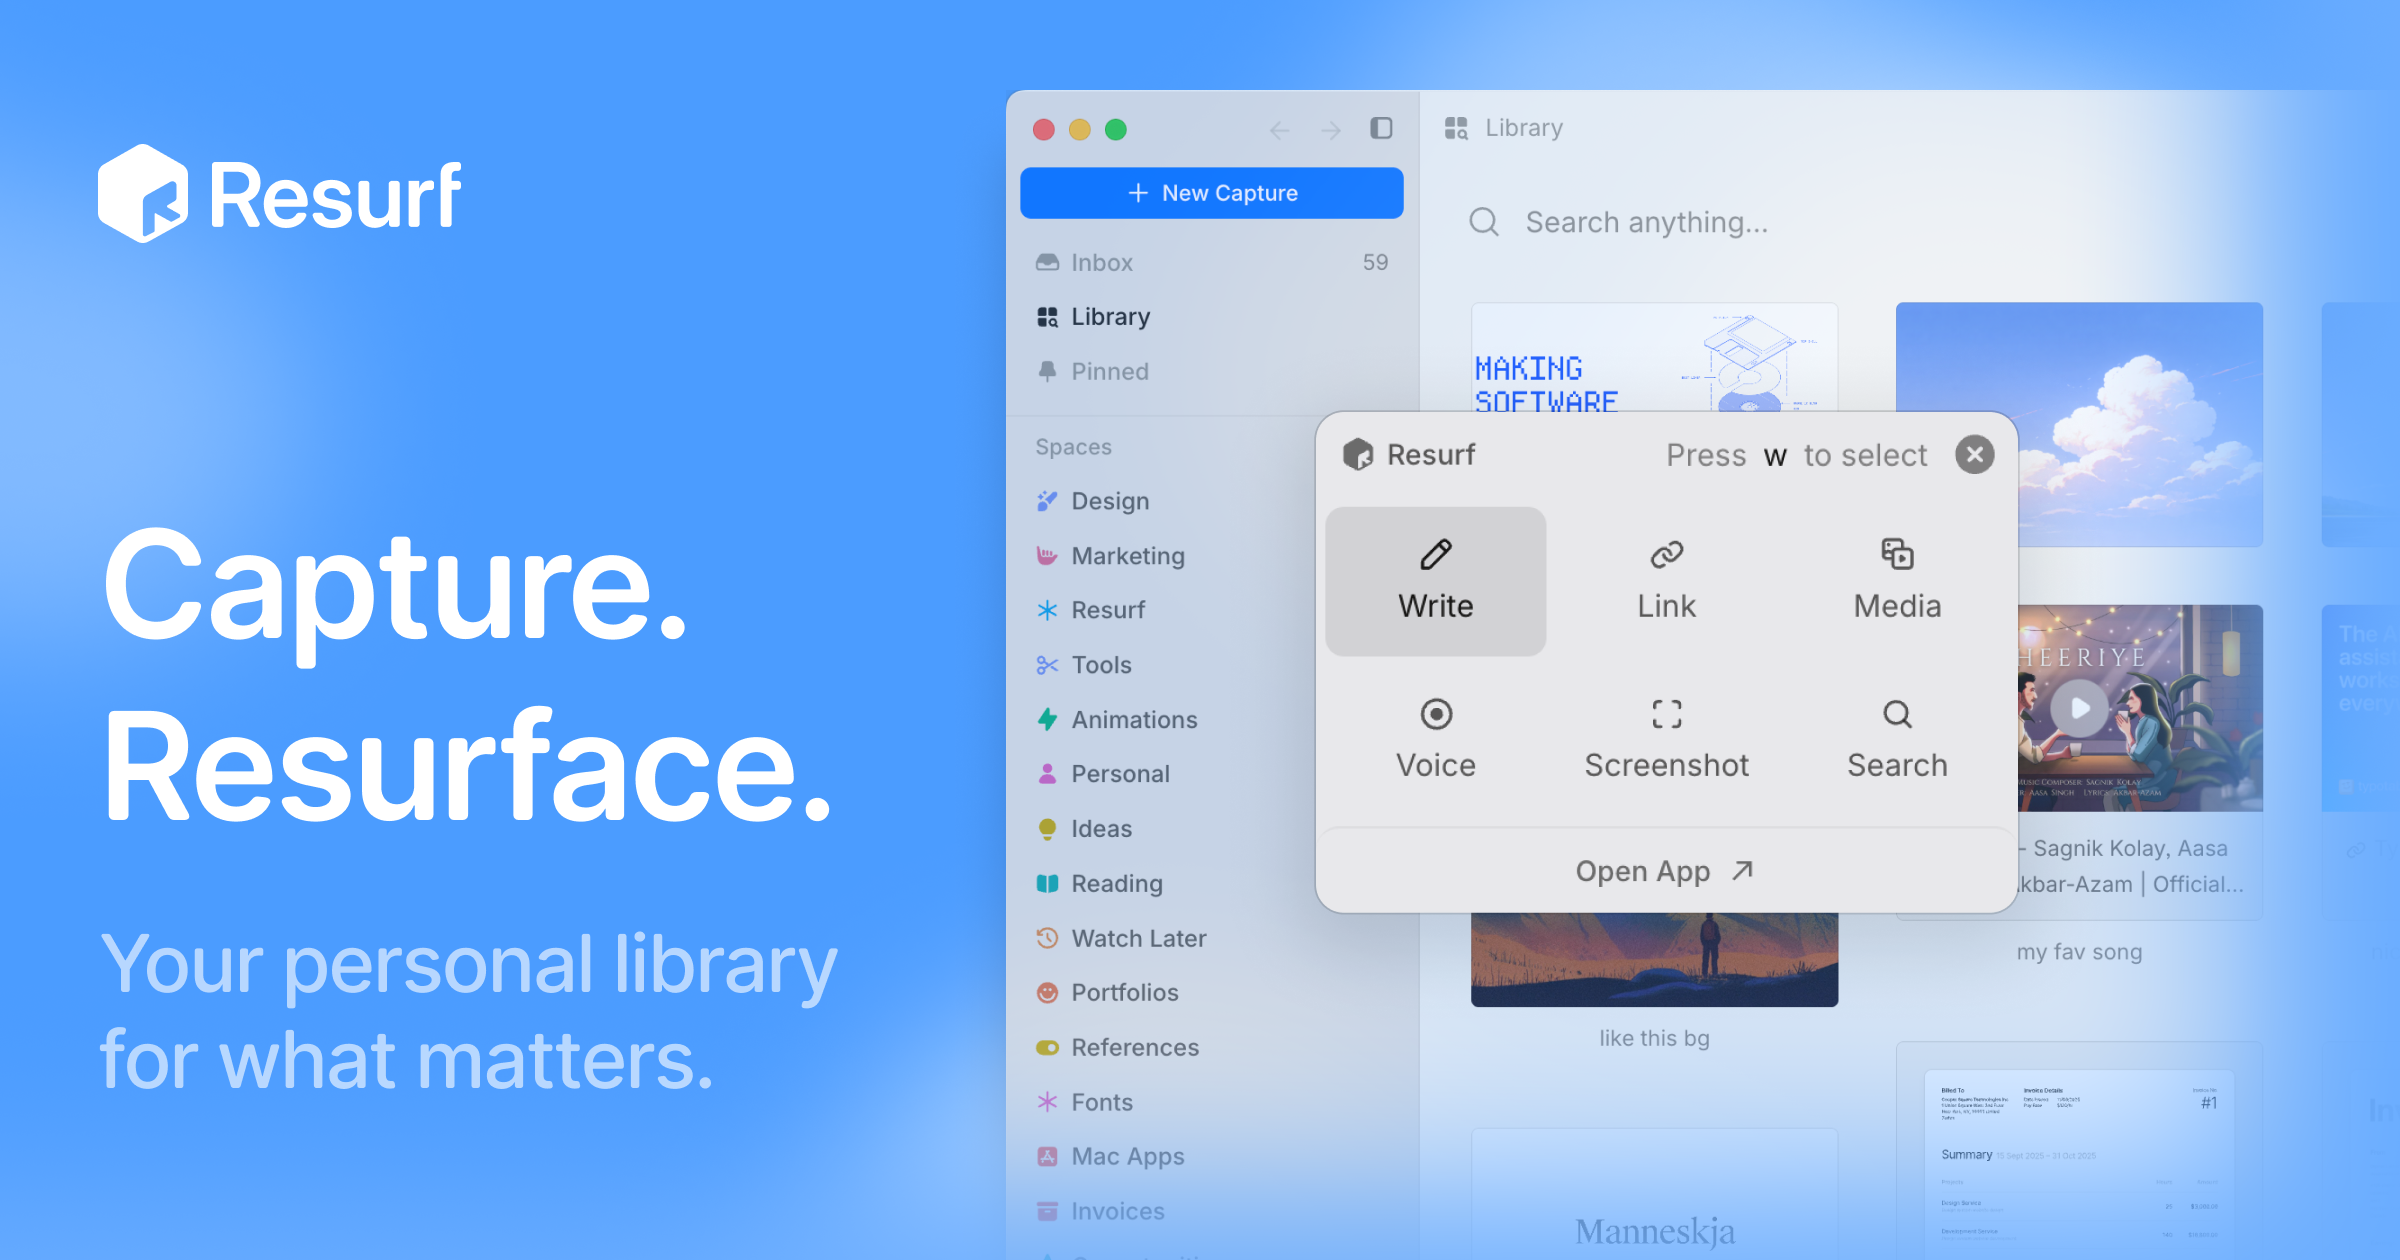
Resurf is a personal context library — one place to keep the things you like, care about, and work on. It saves notes, links, images, PDFs, and documents into a fully local library, so the material you collect stays in one searchable spot instead of being scattered across browsers, folders, and apps. The app is built for Mac, iPhone, and iPad, and it is written entirely in native Swift. Its stated purpose is twofold: capture what you find, and then find it again — or hand that accumulated context to AI when you need a model to work with your own material. There is no Resurf account required, the app works offline, and sync through your own private iCloud is optional. The problem Resurf addresses is fragmentation. The things a person wants to remember arrive in wildly different formats and from wildly different places: an article on Substack, a PDF of a paper, a screenshot, a tweet, a GitHub repository, a YouTube video, a code snippet, a voice note recorded in the middle of a walk. Each of those lands wherever the app that produced it decides to put it. Later, when the thought returns — 'I read something about typography,' 'there was a paper worth revisiting' — there is no single place to look. Resurf's answer is the inbox model: save now, organize later. The library is meant to get more useful every time you save, because a growing personal collection becomes more valuable as long as it remains findable. A second, newer problem motivates the AI side of the product: AI tools are only as good as the context you give them, and most people have no structured way to hand over what they have saved. Capture is designed to stay out of the way. Quick Capture, bound to ⌘⇧C, lets you save something without switching context — the point being that a capture tool fails if it interrupts whatever you were doing. Content can come from any app: Resurf captures from Mac, Chrome, and iPhone into the same library, and a Chrome extension is available from the Chrome Web Store for browser-based saving. The library accepts a wide range of formats — articles, PDFs, images, audio, video, code, tweets, GitHub, YouTube, and notes — and every format renders natively, meaning you view the saved item as it was rather than as a degraded copy. Once something is saved, Resurf leans on an inbox-first approach: you do not have to decide where a capture belongs at the moment you make it. Organization happens later, through Spaces and Tags that let you group material around projects, research, and ideas — the page shows examples such as Research and Writing spaces and tags like #ml, #philosophy, and #ideas. A Visual Library complements that structure by letting you browse what you saved the way you remember it, which suits image-heavy or reference-heavy collections where a thumbnail is easier to recognize than a filename. Instant Search, triggered with ⌘K, finds notes, links, PDFs, images, and files quickly across the library — the page illustrates it with an example of searching typography notes across 24 captures from the last six months. Resurf also covers the moment after capture, when you have something to say about what you saved. Highlight & Annotate keeps your thoughts beside the source, so commentary lives with the material rather than in a separate document — useful when a highlighted passage only makes sense in relation to your note about it. Voice Memos capture thoughts before they disappear, which matters for ideas that arrive away from a keyboard. The Notes surface provides a rich-text editor with a formatting toolbar and highlights, and the product describes five surfaces — Library, Inbox, View, Notes, and Assistant — as the five places you will actually spend your time in the app. AI in Resurf is opt-in across the board, and the product is explicit about that. AI Summaries help you revisit articles, links, and PDFs faster by producing a short summary of the saved item. Bring Your Own AI lets you supply your own AI key rather than relying on a bundled service, and on Mac you can hand off saved context to AI agents through MCP or the CLI — a documented connection path in the guides. Ask Your Library lets you ask questions across the context you have saved; the page illustrates this with a query such as 'What did I save about typography?' answered against a reading list. Because the library lives locally, the material used for these questions is your own collection rather than a shared index. How the product works is defined by its architecture. Resurf is written entirely in native Swift for Mac, iPhone, and iPad, so the same library runs natively across all three rather than being wrapped in a cross-platform shell. Your library lives on-device — the page names the location ~/Library/Resurf — which is what makes the 'fully local' and 'private by default' claims concrete: data stays on your Mac, the app works offline, and no account is required. Sync is optional and runs through your own private iCloud rather than a Resurf-operated service. The Chrome extension and the MCP/CLI connection on Mac are the two extensions beyond the core Apple-platform apps: the first brings browser captures into the library, the second takes the library out to AI agents. The benefits follow from those choices. Because everything lands in one library with instant search, the answer to 'where did I put that?' is a single search rather than a tour of multiple apps. Because capture is bound to a keyboard shortcut and does not require switching context, saving feels lightweight enough to actually do. Because storage is local and sync is optional and private, the library can hold personal reading, screenshots, and voice memos without being uploaded to a third-party service. And because the library is exposed to AI through your own key, MCP, or the CLI, the collection becomes an input rather than a dead archive. The app is also free to try and, per the page, free on iPhone and iPad, with a separate license purchase for Mac. Concrete uses appear throughout the product's own examples. A reader saves a Substack article tagged #reading so it can be found later, and highlights passages while annotating them. A designer or writer keeps typography references and design notes in a space, browsing them visually — the page shows a query about typography answered from saved captures. A researcher stores papers such as a PDF of 'Attention is all you need,' marking it as worth revisiting. Someone away from a desk records a voice memo about a headline's typography. A developer saves GitHub repositories, code, and YouTube videos alongside everything else. Once the library has grown, the same collection can be queried directly — 'What did I save about typography?' — or handed off to an AI agent on Mac through MCP or the CLI. Resurf is aimed at people who collect: designers gathering visual references, writers and researchers assembling sources, developers saving code and repositories, and anyone who already runs a personal knowledge practice or wants to. Availability reflects that audience. The app runs on Mac (Apple Silicon and Intel) with macOS 14.3 or later, and is free on iPhone and iPad; the Mac app can be downloaded free to try or licensed through a purchase. A Chrome extension is available for browser capture, and a guide covers connecting agents over MCP or the CLI on Mac. The library itself is stored locally at ~/Library/Resurf, with optional private iCloud sync and no Resurf account required. The takeaway is that Resurf treats your saved material as an asset with two uses: a private library you actually revisit, and a context source you can hand to AI. It is fully local by default, native across Mac, iPhone, and iPad, built around quick capture and instant search, and organized through inboxes, spaces, tags, and a visual library. Its AI capabilities — summaries, asking your library, and agent handoff through MCP or the CLI — are opt-in and can run on your own key. For anyone whose best ideas and references are currently spread across browsers, folders, and screenshots, Resurf's proposition is a single, private, searchable place to put them.
AlphaGenome Atlas is a database introduced by Google DeepMind that predicts the effects of every possible single nucleotide variant in the human genome. It was created by using the AlphaGenome AI model to pre-calculate the regulatory impact of all nine billion single-letter genetic changes, producing a massive, one-petabyte dataset. The Atlas is intended for researchers, clinical researchers, and biologists, who can explore it through an intuitive website portal that requires zero coding skills, with API and Antigravity access available for deeper research. Its stated purpose is to provide grounded genomic insights that will accelerate the pace of biological discovery. The human genome is made of about three billion base pairs of DNA, but much of it remains a mystery. Scientists understand the roughly two percent of the genome that codes for proteins relatively well, yet they have only limited knowledge of the remaining ninety-eight percent. Google DeepMind's AlphaGenome model had already shown how single changes in these non-coding DNA regions can disrupt molecular processes such as protein production, but the bigger picture across the genome remained unclear. At the same time, identifying rare, non-coding variants linked to complex traits is difficult because of statistical noise in the data. AlphaGenome Atlas was created to address this gap by turning an enormous space of possible mutations into a searchable, precomputed resource that researchers can rapidly query instead of evaluating variants one at a time. A central feature of the Atlas is the AlphaGenome Variant Impact (AVI) score. This single, easy-to-use score combines predictions for both coding and non-coding regions of the genome, giving researchers one measure to work with instead of a large collection of separate outputs. Because the score condenses coding and non-coding predictions into a single number, it allows researchers to quickly prioritize the most promising avenues for research without sifting through thousands of data points. The AVI score is described as the mechanism that helps scientists rapidly navigate the vast information held in the Atlas, making it possible to rank variants by predicted impact and focus attention where it is most likely to matter. In practice, this scoring approach is what turns a one-petabyte dataset into something a research team can act on. The Atlas covers every possible single nucleotide variant in the human genome. Google DeepMind used the AlphaGenome AI model to pre-calculate the regulatory impact of all nine billion single-letter genetic changes, resulting in a one-petabyte dataset. Crucially, these predictions span both coding and non-coding regions, rather than focusing only on the small fraction of the genome that codes for proteins. This matters because the non-coding portion of the genome is where much of the remaining biological mystery lies, and where single-letter changes can disrupt molecular processes like protein production. By precomputing predictions across the full set of possible variants, the Atlas removes the need for researchers to run predictions on demand for each variant they want to investigate, and instead gives them a comprehensive catalogue of how genetic mutations affect molecular biology. Access to the Atlas is designed to be broad. It is available through an intuitive website portal that requires zero coding skills, which the announcement frames as democratizing access for clinical researchers and biologists worldwide. For researchers who need to work at greater depth, the Atlas also offers API access, along with access through Antigravity. AlphaGenome Atlas is free to explore through the visual web interface. This combination of a no-code portal and programmatic access means the same underlying predictions can serve a biologist inspecting a single variant in a browser and a research group building variant-prioritization workflows into its own pipelines. The Atlas works by precomputation rather than on-demand prediction. Rather than running the AlphaGenome model each time a researcher wants to understand a variant, Google DeepMind used the model to pre-calculate the regulatory impact of every possible single-letter genetic change in the human genome — all nine billion of them — and stored the results as a one-petabyte dataset. The Atlas then helps scientists rapidly query this vast information, and it introduces the AVI score as a way to summarize the underlying predictions into a single usable ranking. This approach shifts the heavy computational work to a one-time, genome-wide precomputation and turns the result into something that can be explored interactively or accessed programmatically, which is what makes rapid navigation of the full variant space feasible. The stated benefit of AlphaGenome Atlas is that it provides grounded genomic insights that will accelerate the pace of biological discovery. By combining coding and non-coding predictions into a single AVI score, it lets researchers prioritize the most promising avenues for research without sifting through thousands of data points, saving effort that would otherwise be spent on manual triage. The no-code web portal broadens who can use these predictions, democratizing access for clinical researchers and biologists worldwide rather than limiting it to those who can write code or run models themselves. The announcement also describes the Atlas as acting as a powerful augmentation partner for the scientific community, accelerating research — a claim illustrated by the rare disease and complex trait examples it cites. Overall, the Atlas is positioned as a resource that makes a previously unclear genome-wide picture accessible and actionable. AlphaGenome Atlas is already being applied in real research settings. At the Broad Institute, Laura Covill and her team used the AVI score to prioritize variants for unsolved rare disease research; the tool highlighted a critical variant in the DNM1 gene, predicting that it created an incorrect splice site, which provided crucial supporting evidence that helped successfully solve the case. In a second example, Dr. Gareth Hawkes applied AlphaGenome Atlas to data from more than 54,000 UK Biobank participants to study complex traits. By grouping variants based on predicted molecular effects, he uncovered 22% more non-coding genetic associations, and by focusing on the top 1% of impactful variants he identified 19 genetic regions linked to body mass index (BMI), directing the next stage of targeted research. These examples show the Atlas being used both to prioritize individual candidate variants in rare disease and to group and rank variants across large population cohorts. AlphaGenome Atlas is aimed at the scientific community — researchers, clinical researchers, and biologists — including teams working on rare genomic variation and on complex traits. It is described as available today through an intuitive website portal that requires zero coding skills, with API and Antigravity access for deeper research, and it is free to explore. The Atlas is presented as part of Google DeepMind's ongoing commitment to accelerate genomic discovery and science, for everyone, and it builds on the earlier AlphaGenome model. For those who want more detail, the announcement points readers to the Google DeepMind blog. AlphaGenome Atlas is Google DeepMind's high-resolution, precomputed map of how single-letter changes in human DNA affect molecular biology. By calculating predictions for all nine billion possible single nucleotide variants and condensing them into the AlphaGenome Variant Impact score, it gives researchers a practical way to explore both coding and non-coding regions of the genome and prioritize the variants most worth pursuing. Free, accessible through a no-code portal, and supported by API and Antigravity access, it aims to serve as an augmentation partner for the scientific community and to accelerate the pace of biological discovery.
AI Wins is a fully automated AI good news aggregator that discovers and summarizes positive AI stories daily. It filters out fear and hype to deliver only breakthroughs and wins across categories like healthcare, education, and business.
Heywa is an AI-powered curiosity companion that creates tappable visual stories instead of ChatGPT text walls. It dynamically builds visual experiences around your questions for easy browsing and comparison.