Category Focus/categories/automation
Automation AI Tools
Discover and compare the best automation AI tools and software. Browse 684+ curated tools with reviews and rankings.
Projects tracked
684
Sort mode
RECENT
Page
1
Discover and compare the best automation AI tools and software. Browse 684+ curated tools with reviews and rankings.
Projects tracked
684
Sort mode
RECENT
Page
1
TraceX is an AI engineer for production issues, built to take a customer-reported problem from the first support message all the way to a proven root cause and a fix. When a support email, a Slack message, a Jira ticket or a question in the dashboard arrives, TraceX reads it, plans what to check, and then investigates the systems behind the issue: it queries the database read-only, reads the code and recent changes, and checks error and log tools such as Sentry, Datadog and CloudWatch. It then returns the root cause with a confidence level, what should have happened versus what actually happened, and the evidence behind every claim. From there it writes the fix as a pull request and drafts a reply for the customer. It is aimed at engineering and support teams running production software, and it is free while in private beta. The hard part of a production issue is usually not the fix but finding the cause. A customer writes that a refund has not arrived, and the explanation can be buried across a database state, a migration that renamed something weeks earlier, a code path that still filters on the old value, and a background worker that now finds nothing to process. In the example shown on the TraceX site, 34 refunds sit in a pending state created after October 21, migration 0142 renamed pending to awaiting_payout, and the refund worker still filters on pending, so it silently finds nothing to process. Sentry reports no errors at all, because nothing crashes; the worker simply has nothing to do. Tracing that by hand means jumping between a database console, a repository, a commit history and log tools, and then explaining the conclusion to a support team and to a customer. TraceX is built to do that work in one place, the way your best engineer would, and to show its work at every step so the answer can be trusted rather than guessed at. Every investigation moves through six visible steps: intake, triage, evidence, root cause, action and resolve. Intake accepts an issue from a support email, a Slack message, a Jira ticket or a question in the dashboard. TraceX then plans its checks and follows the data and the code until the cause is clear, querying PostgreSQL, MySQL or MongoDB through read-only credentials, reading the code and recent commits through the GitHub App, and checking Sentry, Datadog and CloudWatch. The result is a root cause presented with its confidence level, an expected-versus-actual comparison, and a citation for every finding pointing to the record, code or log line behind it. A second model checks the answer against that evidence, which is how TraceX keeps answers grounded in what it actually looked up rather than in plausible-sounding assumptions. From the root cause, TraceX moves to action. It writes the smallest change that fixes the cause and opens it as a pull request, with the diff reviewed and its risk level shown, along with validation steps written into the description. In the refund example, the fix changes a single filter from state="pending" to state="awaiting_payout" and is presented as low risk, with the validation step of running the refund worker against staging so that 34 refunds move to payout. TraceX also reviews your team's pull requests, giving reviews on every PR with one-click suggestions. Alongside the code fix, it drafts a reply for the customer, so the support conversation can close with an accurate answer instead of an apology and a promise to look into it. TraceX also answers questions about your systems in plain English: how many refunds are stuck, which customers were charged twice, or what changed in checkout since Monday. Answers come from your databases, code and logs rather than guesswork, each step is shown as it happens, and each claim is cited. When a longer answer is needed, TraceX produces spreadsheets, CSV and PDF exports. In the example conversation on the site, asking how many refunds are stuck returns 34 rows in the pending state, all created after migration 0142 shipped, with the query, the commits read and the verification against the evidence all displayed. This turns ad hoc production questions into documented, checkable answers that a support lead or engineer can act on immediately. For developers who prefer the terminal, the TraceX CLI brings the same capability into your repo. You sign in through your browser, link a repository with one command, and ask TraceX from your terminal with tracex -c for answers carrying the same evidence as the dashboard. It installs with one line on macOS and Linux. In a linked repository it also works in a coding mode that reads, edits and runs tests, asking for your approval before every change and command. The site shows the flow in practice: it edits app/workers/refunds.py, shows the removed and added filter lines, asks whether to apply the change, then asks whether to run pytest, and reports 12 tests passed. In a repository that is not linked, TraceX works as a coding agent that asks before every change. The design of the product is centred on trust. TraceX connects to your databases with read-only access and runs only read-only queries, so nothing in production is changed, and the site lists production writes at zero. Access is read-only and can be revoked at any time. Your records are not kept: there is no index of your code or data, answers retain what was looked up and where rather than the rows themselves, and exported files are deleted after 24 hours. You approve every change, because fixes arrive as pull requests for your review and the CLI asks before every edit and command. Enterprise sign-in covers SSO, two-factor sign-in, roles for admins, investigators and viewers, revocable sessions and a full audit log. You can also run TraceX on your own Anthropic or Gemini account, so AI usage is billed to you and never through TraceX. The outcome is that every customer issue can be traced to its root cause with evidence attached. Instead of an engineer spending time reproducing a report and correlating tools, TraceX returns a root cause, a confidence level and an expected-versus-actual comparison that a team can check line by line. Support gets a drafted reply built from the actual finding, engineering gets a reviewed pull request with validation steps, and the answer can be verified against the cited records, code and log lines. Because every finding cites its source and a second model checks the answer, the conclusion stands on evidence rather than on a model's best guess, which matters when the output is going to a customer and into production code. The product fits concrete day-to-day workflows. A support email saying a refund has not arrived starts an investigation that ends with a root cause and a reply ready to send. A teammate mentions TraceX in a Slack support thread asking why an order was charged twice, and gets the answer, with its evidence, right there in the thread. A Jira ticket about checkout timing out on Safari comes back with a comment explaining the root cause and a linked pull request. A support lead asks in plain English how many refunds are stuck and since when, and receives the rows, the commits read and the verification behind the number. A developer uses the CLI to fix the refund worker filter and run the tests. Teams also use TraceX to review the pull requests they open themselves. TraceX is in private beta with early engineering teams and is free while in beta, with 50 investigations a month during the private beta. It connects to 10 integrations — PostgreSQL, MySQL, MongoDB, GitHub, Sentry, Datadog, CloudWatch, Gmail, Slack and Jira — covering databases, code, logs and inboxes, all connected read-only. Setup is described as connecting a database and a repository and asking your first question in minutes, with an early access request and a sandbox available to try. The combination of read-only access, cited evidence, human-approved changes and the option to bring your own model keys makes it usable for teams that need to see exactly what the system looked at before they act on its conclusions. In short, TraceX's value proposition is simple: every customer issue, traced to the root cause. It reads the support email, investigates the database, logs and code read-only, proves the cause with cited evidence and confidence, writes the fix as a pull request and drafts the customer reply, while keeping production untouched and every change under your approval.
Okapi is a free GitHub App that watches the third-party APIs your app and AI agents call and opens a pull request with the fix before a breaking change hits. It is built for developers whose applications and agents depend on external APIs, where a single changed field, renamed parameter, or retired endpoint can take a production app down. Okapi describes itself as Dependabot for APIs: instead of waiting for a deprecation email or manually reading changelogs, you connect a GitHub repository and Okapi keeps your code up to date with every API it calls. The goal is simple — your app keeps working and your team stops chasing changelogs. APIs change all the time, and keeping up with every API's changelog is a hassle. Deprecation emails get lost, nobody has time set aside for the work, and no one owns it. Still, a small field change in an API response can take your whole app down — as Okapi puts it, a tiny update can bring down a big app. The problem is not that providers fail to announce changes; it is that the announcements arrive in many different places and formats, and the people responsible for a repository are busy building. Okapi exists to close that gap by watching for changes continuously so developers can focus on building rather than on maintaining connectors and reading release notes. Getting started takes one click. You connect your GitHub repository through the Okapi GitHub App, and Okapi then finds the APIs your app depends on by reading your code. It looks for the API calls the repository makes, from the big names to the niche ones that break more often, and keeps track of their changes. Installation is described as "1 click, then forget it," and the product is 100% free. Because discovery is based on the code you already have, there is no configuration list to maintain by hand and no inventory of providers to assemble: Okapi finds them in your repo for you and begins watching them. Okapi monitors each API call individually and suggests a fix before it breaks. Today it reads 1,173 API providers' own pages and tracks 841 upcoming breaking changes, according to the website. That coverage matters because deprecations and breaking changes are usually published by each provider on its own pages, in its own format, on its own schedule. By reading those pages directly, Okapi can surface an upcoming change — such as a field that will handle null values differently from a given date — and connect it back to the specific places in your code that use the affected call. The result is a continuous watch over the APIs your app depends on rather than a one-time audit. When an API call is deprecated or about to break, Okapi opens a pull request with the fix before it fails. The pull request is not a generic warning: it contains the actual change your code needs. In the Stripe example shown on the site, okapi[bot] opens a pull request titled "Update Stripe API for upcoming customer.address change", wants to merge one commit from a branch named okapi/stripe-customer-address into main, and explains in a comment that Stripe is changing how customer.address handles null values on October 15. The comment lists the effective date, the API, and the number of affected files (two), and the diff updates both files to handle the new response format. The pull request also carries release notes and a "what changed" section plus api-changes and stripe labels, so a reviewer can understand the change without hunting for context. Okapi works with any API, not only a fixed set of well-known providers. The site's examples span many languages and services: an OpenAI call updated from max_tokens to max_completion_tokens; a PubMed query changed from sort "date" to "pub_date"; a verification request that gains a verify_profile_id field; a notification URL moved to a new push endpoint; an ip-api lookup switched from HTTPS to HTTP; a Figshare download moved to the v2 API; a Mojang profile path corrected; and a Gemini configuration changed from a thinking budget to a thinking level. Each diff is small — often one or two lines — which is exactly the point: the changes that break production are frequently tiny, and they are easy to miss when nobody is watching every provider's changelog. Okapi's approach mirrors dependency automation, which is why it calls itself Dependabot for APIs. Rather than pushing commits directly, it opens a pull request for every change so a human reviews and merges it. The site states that Okapi never commits to your branches: every change comes as a pull request you review. If you do not merge the pull request, nothing changes in your code; the pull request stays open until you merge or close it. That design keeps developers in control while still removing the detective work of finding the change and the mechanical work of applying it. The stated benefits are straightforward: no more time spent maintaining connectors, and improved reliability over time. Instead of learning about a breaking change from a production incident, teams see a pull request with a fix and an explanation before the effective date. Deprecation emails that get lost no longer matter as much, because the watch is continuous and attached to the code that makes the call. Because the fix arrives as a reviewable pull request, teams can adopt it on their own schedule, inspect the reasoning, and keep their normal code review process intact. Concrete scenarios follow directly from the site's examples. A billing service that reads customer.address from Stripe can receive a pull request ahead of the October 15 null-handling change. An application calling OpenAI can be moved from max_tokens to max_completion_tokens. A literature search tool using PubMed can have its sort parameter corrected. A service calling a geolocation or media API can have a changed URL or protocol updated. Teams running AI agents that call external services can keep those agents working as providers evolve. And teams depending on niche APIs that break more often get the same monitoring as those using the largest providers. Okapi is aimed at developers whose apps and AI agents depend on third-party APIs, and at teams that do not have anyone specifically assigned to tracking provider changelogs. The access required is limited: Okapi reads your code to find the API calls it should watch, and it never commits to your branches. Removal is equally simple — uninstall the Okapi app from your GitHub settings and it stops right away. The product is 100% free, installs in one click, and works with any API, so there is no pricing tier or provider list to evaluate before trying it. In short, Okapi brings dependency-style automation to the APIs your code calls. It discovers the APIs in your repository, watches their providers for deprecations and breaking changes, and opens a pull request with the fix before the change can break your app — free, with one-click install, and with every change left for you to review.
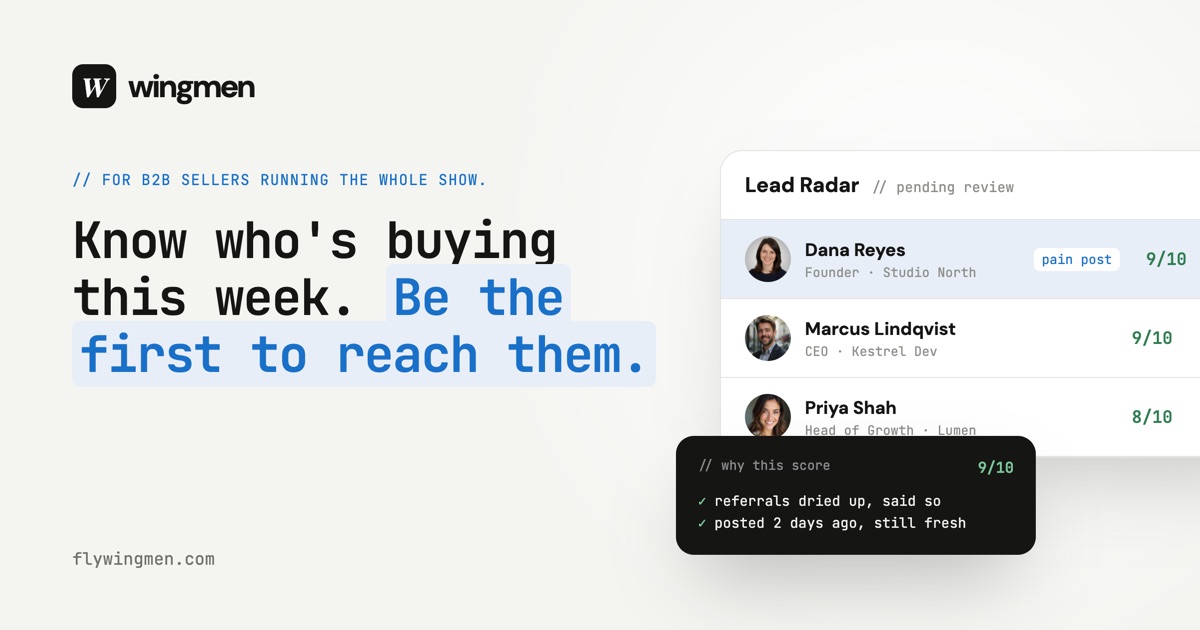
Wingmen is an agentic outreach product that reads buying signals every day, starts the conversation and follows up until there is a call on your calendar. It runs in a web app or straight from Claude with the Wingmen MCP, and it is built for founders, B2B teams and agencies. Instead of working from a list of job titles, Wingmen surfaces the moment someone needs what you sell, attaches the reason why, writes the opener from what that person actually said, and keeps following up across LinkedIn, email and voice notes on autopilot until a meeting is booked. The product is positioned explicitly against the "list of job titles" approach to prospecting. Wingmen's Lead Radar shows a daily set of signals — 24 signals, read for you every day — and each one carries a score and a one-sentence reason. In the illustrated feed, a founder who wrote "Three months of referrals, then nothing" appears as a pain-language post at 9/10; a founder coach who commented on a competitor's launch appears as a competitor engager at 7/10; a founder who posted about onboarding for fintech appears as a post author at 8/10; a new Head of Growth three weeks into the seat appears as a job change at 8/10; and a CEO hiring a first sales rep appears as a hiring post at 9/10. The point is timing: the moment someone needs what you sell, with the reason why. The largest group of signals Wingmen reads is posts and engagement. Pain-language posts catch people who wrote about the problem in their own words. Niche post engagers engage with posts about the space you work in, while topic post engagers engage with posts on the topics your buyer cares about. Competitor post engagers engage with a competitor's posts, and engagers on your posts liked or commented on what you posted. Wingmen also reads post authors — the person who wrote the post, not only the people reacting — and handles the company page to person case, where a company page posts the signal and Wingmen finds the person to write to. Event attendees cover who is going to the events your buyer goes to, and the follower pool covers people who follow you, or the voices your buyers listen to. A second group covers hiring and workforce movement. Hiring posts and job listings flag companies hiring for the problem you solve; job changes catch someone new in the seat, still making their first calls; companies hiring fast have many open roles at once, meaning the team is scaling; and growing teams show headcount climbing month over month. Company and market signals sit alongside these: website changes such as new pages, new pricing or a new product on their site; podcast mentions where they talked about the problem on a podcast; and news mentions of a launch, a press mention or a move that opens a need. Wingmen also reads advertising, technology, financial and regulatory signals. Companies running Google ads are spending on growth right now. Tech stack changes show a company that added or dropped a tool your product sits next to, and GitHub activity shows their engineers building in your space. On the financial side, funding posts indicate a company that just raised and has budget to spend, while Form D filings surface a fresh raise straight from SEC filings. When the day is quiet, cold search tops up the pipeline: cold search matches title and industry to your buyer, lookalike search finds people who look like your best-fit leads, and target accounts track movement at the accounts you name. Once a signal is caught, Wingmen runs a four-step sequence the site describes as "four wingmen, one booked call." Step one, the scout, spots the signal — a post about the problem, a new hire, a job change — the day it happens. Step two, the scorer, gives every lead a score and a reason in one sentence, and the opener is written from that reason, in your voice. Step three, the messenger, reaches out on LinkedIn first; if there is no reply, email or a voice note picks it up in the same sequence, on autopilot. Step four, the closer, brings replies into one inbox with an answer already drafted, and the meeting goes on your calendar. Wingmen can also be run from Claude. Connecting Wingmen to Claude as a custom connector lets you run outbound in plain words from the chat you already have open — asking for founders hiring their first sales rep returns leads the radar found that week, and a follow-up "yes, go" starts the agent on all of them. Two further capabilities extend outreach: voice notes are an add-on that lets you clone your voice once, after which Wingmen records a short note for each person based on their signal; and comment automations turn comments on your posts into conversations — someone comments the keyword, the DM goes out, and the thread joins your inbox. The stated outcome is a booked call rather than a list. Buyers are found daily, each with a written reason; outreach runs across LinkedIn, email and voice notes; every reply is read and sorted, ready to book; and every feature is included with no tiers, up to 600 leads a month per seat. Because the opener is written from the reason attached to the signal, the first message carries the context of what the person actually said or did instead of a generic pitch, and because the follow-up continues on autopilot across channels, a lead that does not answer on LinkedIn is still picked up by email or a voice note in the same sequence. Concrete scenarios follow directly from the signals the product reads. A seller watching for hiring signals can ask Wingmen for founders hiring their first sales rep and start the agent on everyone it found that week. A team can reach out to people who wrote about the problem in their own words, or to people engaging with a competitor's posts. A quiet day can be topped up with cold search, lookalike search or movement at named target accounts. Anyone who comments a keyword on your own posts can be turned into a DM conversation through comment automations, and voice notes let you add a personal spoken touch to each lead at volume. Wingmen is built for founders, B2B teams and agencies. The maker, Nemanja Milic, describes it as the agent he built because he sells without a sales team. Pricing is a single seat plan at $69 per month, discounted to $48.30 per month per seat with the PH30 code during the Product Hunt launch, at 30% off for life and valid until Dec 31. A 7-day free trial is available, and if you would rather have Wingmen run it for you, Concierge Outbound starts from $999/month. In short, Wingmen's value proposition is timing plus follow-through: it reads buying signals every day, explains why each lead matters, writes the opener from the signal itself, and keeps working the sequence across channels until a call appears on your calendar.
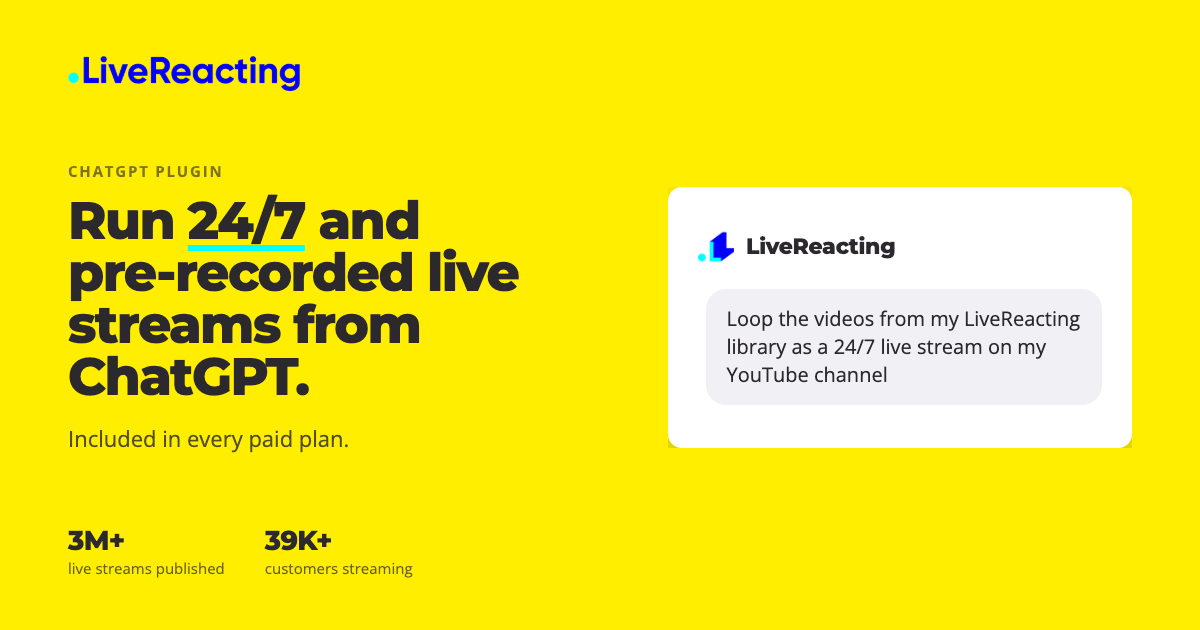
LiveReacting for ChatGPT is a ChatGPT plugin that lets people create and manage live streams by typing a request into a ChatGPT chat. After installing the plugin and signing in with a LiveReacting account, a user types @LiveReacting and describes the stream they want: a 24/7 loop of videos on their YouTube channel, or a recorded video that should go live at a time they choose. ChatGPT then works with what already exists in the LiveReacting account — the videos in the library and the channels that have been connected — and builds the stream there. LiveReacting's servers send that stream to YouTube, Facebook, Twitch, LinkedIn, X or any other platform the user has connected, all at the same time, so the user's computer can be off while the broadcast runs. Running a continuous or scheduled live stream normally means opening a streaming tool, preparing the video files, building a playlist, picking destinations and starting the broadcast — a sequence of steps that has to be repeated for every new stream. LiveReacting for ChatGPT moves that work into a conversation. The product page frames the experience as asking for a stream "in your own words": type @LiveReacting, then say which videos, which channel and what time, and ChatGPT works out the steps and reports back when they are done. This matters for creators, pages and teams that publish recurring or scheduled streams and would rather describe the outcome they want than operate a streaming interface each time. Two of the plugin's core capabilities are looping videos as a 24/7 live stream and scheduling a recorded video. For a 24/7 stream, the user names the videos and the channel; ChatGPT puts them in a playlist in the order the user wants, and that playlist plays on a loop until the stream is stopped. For a scheduled stream, the user gives ChatGPT the date and time the broadcast should start, up to 28 days ahead; LiveReacting starts the stream at that time and ends it when the video ends. The scheduled mode plays the video once, which contrasts with the loop that runs continuously. Both modes are created from the same chat, so a user can move between a permanent channel and a one-off broadcast without leaving the conversation. The plugin works with videos that are already in the user's LiveReacting library, and it can add new ones from a link. A user can give ChatGPT a Google Drive link, a Dropbox link, a public link to a video file, or a video from their own YouTube channel, and ChatGPT adds that video to the library. When building a 24/7 stream from library videos, ChatGPT finds the videos in the library and checks that each one can be streamed before building the looping playlist. Videos stored on the user's own computer are handled differently: they are added to the library in the LiveReacting Studio first, after which the user can ask ChatGPT to use them. In the chat itself, ChatGPT takes a new video from a Google Drive, Dropbox or public link rather than from a file the user attaches. Multistreaming is built into the same request. A user can pick several channels for one stream, and LiveReacting sends it to YouTube, Facebook, Twitch, LinkedIn, X or any other platform connected to the account at the same time. This means a single chat request can reach several audiences at once instead of requiring a separate setup for each destination. The product page also notes a practical limit on Facebook: Facebook ends a live stream after 8 hours, so a 24/7 stream cannot run on Facebook alone. Adding YouTube or another platform to the same stream keeps it running there, which is why multistreaming matters for continuous channels. Streams are not frozen once they start. From the chat, a user can add a video to the playlist or switch to another scene while the stream is live; viewers see the change and the stream keeps running. The plugin also reports on performance. A user can ask whether a stream is live and how it is doing on each channel, and for past broadcasts ChatGPT tells them how long each one ran and its peak viewers. Together these two capabilities turn the chat into a lightweight control and monitoring surface for streams that are already broadcasting. Under the hood, the plugin connects to the LiveReacting MCP server, the same server that Claude, Claude Code, Cursor and other AI agents use. Setup is short: choose Open in ChatGPT, click Install plugin, and sign in with a LiveReacting account when ChatGPT asks; then, in any chat, type @LiveReacting and ask for the stream. ChatGPT receives access to the LiveReacting account but never sees the user's platform logins — YouTube, Facebook, Twitch and other channels are connected inside the LiveReacting account, and ChatGPT picks from the ones that were connected. The actual broadcast is produced by LiveReacting's servers and sent to the chosen platforms, which is what allows the user's computer to be switched off. The main benefit is that a stream can be requested in natural language and then runs without the user's machine being involved. Because LiveReacting's servers send the stream, the user is not tied to a computer during the broadcast. Because the plugin works with the videos and connected channels already in the account, users do not need to rebuild assets for each stream. Because the playlist can be changed and the status checked from the same chat, routine maintenance — swapping a video, checking which channels are live, reviewing how long a past broadcast ran and its peak viewers — happens in the conversation where the stream was created. The product page illustrates the workflow with example prompts. One asks to loop the videos from the LiveReacting library as a 24/7 live stream on a YouTube channel, which suits a channel that should always be broadcasting. Another asks to live stream a recorded video from Google Drive on a Facebook page today at 8 PM: ChatGPT imports the video from the link, builds a stream that plays it once, then schedules it for 8 PM on the Facebook page. A third asks to show the status of running live streams, and ChatGPT lists which streams are live and how each one is doing on every channel. The same capabilities cover multistreaming one stream to several destinations and adding a new video to a playlist mid-broadcast. The plugin is included in every paid LiveReacting plan. On the Free plan, ChatGPT can connect, but each request stops with a message that the account needs a paid plan. The page is explicit about what the plugin cannot do: it cannot build overlays, polls or trivia, which are created in the LiveReacting Studio, the browser-based stream editor — although ChatGPT can still start, schedule, stop and check a stream that has them. It cannot import a YouTube playlist or channel; users give one video link at a time in the chat, or import the whole playlist or channel in the Studio. And it cannot run a 24/7 stream on Facebook alone, because Facebook ends a live stream after 8 hours; adding YouTube or another platform to the same stream keeps it running there. In short, LiveReacting for ChatGPT turns a chat message into a running broadcast. It combines 24/7 looping playlists, scheduled pre-recorded streams up to 28 days ahead, multistreaming to the platforms a user has connected, live playlist and scene changes, and status and viewer reporting, all handled on LiveReacting's servers so the user's computer can stay off.
OpusClip 4.0 is an AI video editing tool that takes a raw take and returns a finished video. According to the company, it was built for talking videos: users drop in raw footage or paste a link, switch on options such as speech cleanup, captions and B-roll, and receive a finished video back. The product is aimed at the kind of creator who records a two-minute product update on a phone between meetings, a dentist answering patient FAQs on camera each week, or someone teaching an audience how to make high-protein meals. Its stated purpose is to give a team of one some of the range that media companies get from a room full of editors, so individuals can post often and in many formats without hiring an editor. OpusClip originally described itself as built to "slice a clean fish." Early users brought finished videos, such as a podcast episode that was already edited or a keynote someone had cleaned up, and OpusClip found the best moments and turned them into clips. That worked, and the company notes that scrolling a feed for a few minutes gives a good chance of seeing a clip that came through OpusClip. But what people bring has changed: increasingly it is a raw take that nobody has had time to edit. The company observes that many founders and operators now have to make video content because that is where their customers are, yet almost none of them enjoy editing. They film in one take because they know they will never get around to cutting it, and they post it as is; many already have a good video sitting on their phone, filmed weeks ago and never edited. For a while OpusClip kept improving clipping and left the hardest part, the edit itself, to the user; version 4.0 takes that on. Auto-edit is the headline addition. It is built for talking videos: users drop in raw footage or paste a link, then switch on speech cleanup, captions, B-roll and more, and what comes back is a finished video. The value is that the step where most solo creators stall, actually cutting the take, is handled automatically, so a recording that would otherwise sit unedited on a phone can become something publishable. Because the controls are switches rather than a timeline, the workflow stays simple for people who do not enjoy editing and do not want to learn a professional editor. Every format means one edit can become whatever the user needs that week: 60 to 90 second highlight clips, a 3 to 5 minute extended cut, or a quick lo-fi update. This addresses the company's point that people who stay top of mind post often, in a lot of formats. Recipes address repetition: most people make the same kind of video over and over, so OpusClip lets users save their setup as a Recipe, or start from one of the built-in Recipes, and the next video gets edited the same way. Recipes turn a one-off success into a repeatable style, which is useful for a weekly series where every episode should look and feel consistent without being rebuilt from scratch. Viral Hook and Motion Graphics cover two tasks the company says editors spend hours on. Viral Hook gives the first few seconds of a video a hook style chosen from a template library, targeting the opening moments that decide whether a viewer keeps watching. Motion Graphics turns what the speaker says into animated icons, numbers and charts on screen, so spoken points become visual elements without a motion designer. Together they add polish that usually requires specialist work, applied to the talking video being edited. AI Producer lets people who already work in ChatGPT or Claude edit from there with an OpusClip plugin: the user shows it a style they like and it edits the footage to match. This meets creators inside tools they already use rather than requiring a separate editing session. Clipping has not gone away. The company says it is still what OpusClip is best known for and is still getting better, just one part of the product now, and it describes turning long videos into clips and publishing them to all social platforms in one click. The overall approach is to cover the whole path from raw take to every format a creator posts, rather than only the moment-finding step. A user brings footage or a link, selects cleanup, caption and B-roll options, optionally applies a saved Recipe or a hook template, and receives a finished video; the same edit can then be output as a short highlight, an extended cut or a quick update. For those already working in a chat assistant, the plugin moves the editing instruction into ChatGPT or Claude, where the user shows a style and the footage is edited to match. The stated benefits follow that workflow. The edit no longer stalls, so recorded footage actually gets published instead of sitting on a phone; a solo operator gets some of the range of a full editing team; Recipes keep styling consistent across repeat videos; Viral Hook templates handle the opening seconds; Motion Graphics add animated icons, numbers and charts without an editor; and one edit stretches across multiple formats. The company frames 4.0 as a starting point, with more planned around the edit in later releases. Concrete scenarios named in the content include a founder recording a two-minute product update on a phone between meetings; a dentist answering patient FAQs on camera every week; someone teaching 3,000 followers how to make high-protein meals; podcast episodes and cleaned-up keynotes being clipped into their best moments; weekly series that reuse a saved Recipe; and quick lo-fi updates versus 60 to 90 second highlights or 3 to 5 minute extended cuts from the same edit. The company stresses that a big audience or an editor is not required. Target users are founders, operators, dentists, educators and small-audience creators who make talking videos themselves. Pricing details in the content: a Free Forever Plan, described as creating and posting one short video every day for free; a Pro monthly plan; and a launch offer of 40% off the first month of Pro (monthly plan) via a coupon code. The page also shows related OpusClip tools: OpusSearch, which uses AI to surface the exact clip you need from hours of footage in seconds, and Agent Opus, which runs research, scriptwriting, storyboarding, motion, voice and edit. The company states that OpusClip is used by more than 20 million creators and brands. OpusClip 4.0's takeaway is simple: it moves beyond clipping to editing the raw take itself, so one recording can become a hook-led short, an extended cut and a quick update without a timeline, an editing skill, or a team. For anyone whose good videos are stuck unedited on a phone, that is the difference between having footage and publishing it.
Orphex MCP is a unified Model Context Protocol gateway that connects a digital marketing stack to the AI assistants teams already work in. It links supported advertising, analytics, commerce, subscription and app growth accounts, then brings that performance data into conversations with Claude, ChatGPT, Microsoft Copilot, Grok, Cursor, VS Code and Gemini CLI. Orphex describes itself as a connection layer between many platforms and one AI assistant, with tools to read performance and request supported changes. The product is built for data-oriented marketing teams that want to ask questions about their own account numbers and get answers from their connected sources, rather than opening yet another dashboard or export. Marketing analysis normally lives across a patchwork of systems. Ad platforms hold spend and conversions, analytics tools hold acquisition and on-site behavior, commerce platforms hold products and sales, and warehouses hold still other tables. The Orphex site frames the everyday problem as tab switching and repeated exports: teams move between multiple platforms to answer a single question, then rebuild context by hand. Orphex places the AI assistant at the start of that workflow instead of at the end of an export. The company states its aim is to move AI beyond QA and empower it to analyze integrated performance and take every action a human marketer can, such as reallocating budgets, pausing unprofitable creatives or adjusting products from a single prompt. The connection layer covers a broad set of sources grouped into Advertising, Analytics, Commerce, App growth, Data warehouse, Subscriptions and Creative. Advertising sources listed on the site include Meta, Google Ads, TikTok, LinkedIn, Pinterest, Snapchat, Reddit, Microsoft Ads, Criteo, DV360, Apple Search Ads, Amazon Ads, X Ads, OpenAI Ads, AppLovin Ads, Unity Ads, Yandex Direct, Taboola, RTB House and Akakçe. Analytics coverage includes GA4, Search Console, Tag Manager, CM360, YouTube, Facebook Page, Meta Pixel, TikTok Pixel, Microsoft Clarity, Similarweb, Context dev, Amplitude and HubSpot. Commerce lists Shopify, IKAS, Ticimax, T-Soft, Akinon, Merchant Center, Meta Catalog, TikTok Catalog, Klaviyo, Insider One, SAP Emarsys, Customer.io and D·engage, while app growth covers Adjust, AppsFlyer, Singular, Google Play, App Store Connect, AppLovin MAX, Appfigures, OneSignal, Unity LevelPlay and AdMob. RevenueCat and Adapty cover subscriptions, BigQuery supplies warehouse-backed context, and Creative includes Content Automation Creative, Higgsfield and Playablex. Orphex notes that coverage and available actions vary by platform and account permissions. Those connections bring in spend, conversions and campaign performance, and the site states that a user's own account data becomes the basis for each question. On top of the data, Orphex adds a Skill Catalog of prepared reviews, action procedures and report templates that give the assistant a method to follow. The example given is a weekly performance review: read the connected sources, compare complete periods, surface the main changes and prepare the next steps. The site also mentions creative fatigue and anomaly investigations with eligible skills, executive summaries and budget reallocation proposals with sources and guardrails. Curated guidance helps the assistant choose the next step, use the right metrics and check the evidence before drawing conclusions, and Orphex is careful to note that a report or proposal does not itself change an advertising account. Every requested change stays within the user's access. The assistant prepares the change and shows a preview, and nothing runs until the user confirms it; a workspace can also require a teammate's approval. The site illustrates this with a proposal that moves $500/day from Brand Search to Performance Max while keeping total daily budget at $3,200 unchanged, and it explicitly states that the proposal does not predict a performance improvement. Orphex also says every change is logged and protected by safety guardrails. On security, the site lists GDPR and KVKK compliance for EU and Turkish data protection law, ISO 27001 audited security processes, and SSL/TLS encryption for all platform traffic with enterprise-grade network protection. Overall, the product is presented as a seven-layer stack. Connected Platforms bring in advertising, analytics, commerce and app growth accounts. Performance Data adds spend, conversions and campaign performance from those accounts. Orphex MCP is the single connection layer that exposes tools to read performance and request supported changes. The Skill Catalog supplies prepared reviews, action procedures and report templates. Curated Guidance helps the assistant pick the next step and the right metrics. Access & Approval keeps each change inside the user's permissions with a review step. AI Assistants are where the user actually works: they ask a question, explore the answer and decide what happens next. Setup is described as taking a few minutes with a single sign-in. The stated benefits follow that structure. Users start with a question instead of another export, compare the same metric across two complete periods while keeping source, dates and numbers in view, drill into the campaign behind a change, and turn a finding into a focused review before acting. Because the assistant answers from connected account data, the conversation keeps the definition of each metric visible and flags missing data. Routine work gets a head start from curated skills, so teams keep the method and skip the blank page. Orphex also states that users do not need to replace their dashboards: they can investigate a question in conversation and follow the evidence back to existing tools for a deeper view. The site's documented use cases read as concrete workflows. For advertising performance and actions, teams compare campaign spend, conversions and efficiency across complete periods, drill into ad, keyword and creative reporting, and review supported budget or status changes before approval. For analytics and customer journeys, they put GA4 acquisition and Search Console organic performance in the same discussion while keeping each source's metric definitions visible. For commerce and product performance, they connect marketing questions to products and sales in Shopify, IKAS, Ticimax or T-Soft and prepare a product performance summary. For subscriptions and app growth, they read RevenueCat project overviews, Adapty subscription charts and attribution data from Adjust and AppsFlyer. For warehouse-backed context, they bring supported BigQuery datasets into the same marketing review. And with curated skills, they run weekly performance reports, executive summaries, creative fatigue checks and anomaly investigations. Orphex targets data-oriented marketing teams, including teams managing $30M+ in monthly ad spend, and lists brands such as Paşabahçe, Arby's, Vestel, Burger King, Bilyoner, Popeyes, Karaca, Sbarro, Beymen, Usta, Getir, DeFacto, Mavi, TurkNet, SneaksUp, TatilBudur, Avansas, Altınyıldız, QNB, Edenred and Analytica House as users. Pricing runs from a Free plan at $0 with 250 reads per month, 50 writes per month, one user, one workspace, three account connections and all data sources; a Read plan at $33.32/month billed yearly at $399.90 with 2,000 reads, ten users, three workspaces and 25 connections; and an Action plan at $124.99/month billed yearly at $1,499.90 with 2,000 reads, 500 writes, ten users, three workspaces and 100 connections. Enterprise offers custom limits, contract billing and onboarding support. Yearly billing includes two months free, and every plan works with Claude, ChatGPT, Microsoft Copilot, Grok and Cursor. In short, Orphex MCP consolidates a fragmented marketing stack into one connection layer so an AI assistant can answer questions from real account data and prepare controlled changes for human approval. The value proposition is continuity: the same conversation moves from signal to evidence to a reviewed next step, while permissions, approvals, logging and compliance keep the marketer in control.
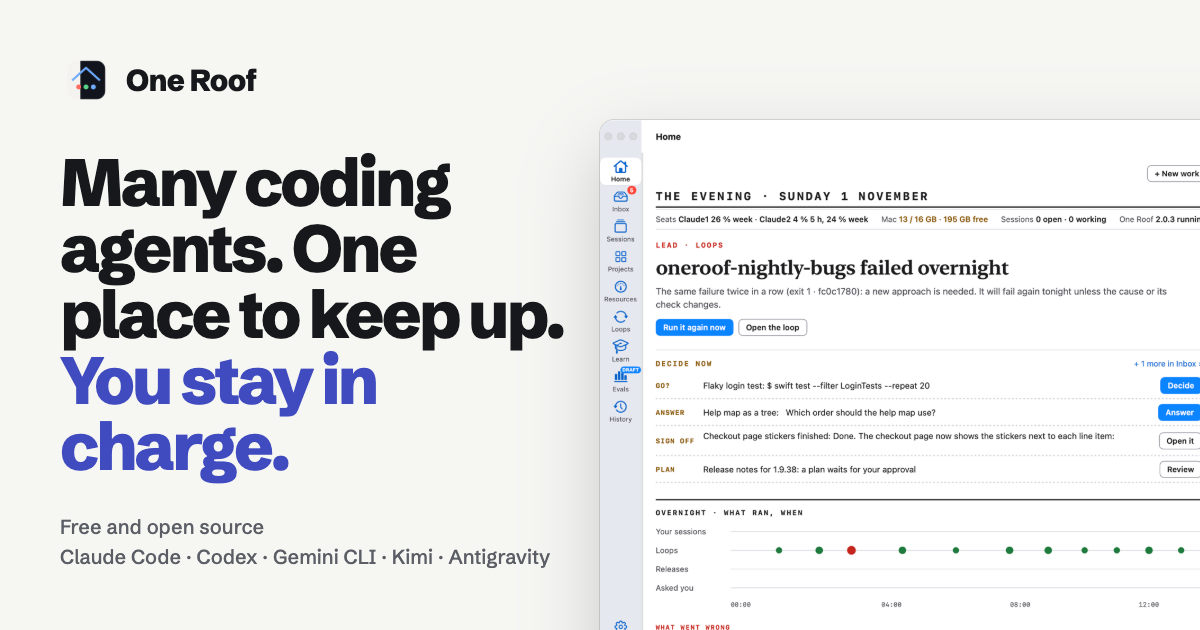
One Roof is a desktop application for macOS that gives you one place to keep up with a whole team of coding agents. It works with the agent command-line tools you already use — Claude Code, Codex, Gemini CLI, Kimi and Antigravity — plus plain shells, and it is explicitly not an IDE and not a terminal. Instead, it is the place where your agents work, with everything they ask, run, learn and cost gathered into one window. It finds the agent command-line tools on your Mac and the accounts you are signed in to, and each session runs the real tool, so you can always type straight into it. The product is free and open source under the MIT licence, and runs on Apple silicon with macOS 14 or later. The problem One Roof addresses is described by the project as chorus coding: several coding agents working on the same piece of work, each doing the part it does best, with one checking another — one plans, one builds, one reviews, and a loop re-runs the tests every night. The hard part of that way of working is keeping up. As the project puts it, the agents are not the bottleneck any more, you are. Five terminals look the same, a question waits in a tab you are not looking at, something failed at 3 AM and nobody told you, and the Mac slows down without any indication of which session is to blame. One Roof was built to keep up with that situation and to keep you the one who decides. The Inbox is the centre of day-to-day work. Every ask from every session lands in one column, one block per session that needs you, with the prompt's own options shown as buttons or selectable with keys 1 to 9. When an agent is blocked until you act, its block gets a red border and moves to the top, and a finished turn waits there too with a reply box where you can paste a screenshot for the agent to read. Nothing is approved for you, and you can always answer in the terminal instead. A Decided list keeps what you answered, newest first. Alongside it, Home is a front page for the morning, built from your own sessions and loops: a lead story about the thing that matters most, a Decide now list of what waits on you with one button each, and an overnight timeline showing every run since midnight as a dot, followed by what went wrong, what to do next and what ran fine. Sessions are real terminals that keep running. Every agent session and plain shell is grouped by state — Needs you, Active, Next, Planned and Exited — and each row shows the agent, the account, the folder and a live one-line status, so you no longer have to type prefixes in front of tab names to tell five identical terminals apart. Each session can be shown as a single terminal, a grid or a wall. Sessions run inside roofd, a small background service, so they keep going when you close the app and come back with their screens when you open it again. History is a read-only record of each session's important moments: steps, findings, errors, what the agent asked and what you answered, and hand-offs between sessions. Each session's run of moments is one card in its own colour, searchable and filterable by session, agent, kind and date, and kept for 30 days. Loops handle work that repeats until a check passes. A loop gives an agent a goal and a check, such as until the tests pass or every night at 3, and One Roof runs the check first — if it already passes, no agent is started. When the check fails the agent works one round on a separate branch, in the loop's own copy of the repo rather than yours, and then the check runs again: done, or another round, up to a limit. A loop never pushes, merges or deploys on its own, and what it produces waits in the Inbox for your approval. Resources shows memory and CPU for each session, for One Roof itself and for every app on the Mac, with 10-minute charts. A browser shows its windows and tabs and you can close a tab or a window from here, and roofd warns when a session grows past 1 GB and ends it at 2 GB, before it can freeze the Mac. Several more places sit on the rail, some of them optional. Projects shows your Linear projects and tickets — teams, projects by status and each project's roadmap — only if you connect Linear with your own API key; without it, Projects shows a single Connect Linear card. Learn is a course on agentic engineering, made of a narrated Agentic Engineering deck and a timeline of papers that shaped coding agents, listenable in the app, with narration by an AI-generated voice that says so. Evals is marked as a draft in the app: it lets you run public benchmarks or build a question set from your own repo's fixed bugs, then compare agents and models on it, with every score shown alongside its range and a plain explanation of what it means, and the cost shown before anything starts. Safety is the default throughout. Each agent has one permission mode — Manual, Plan, Auto or Full — and on a new Mac every agent starts in Manual and asks before it edits a file or runs a command; you change it per agent in Settings › Permissions. Setup asks for the folder that holds your code, or offers to create ~/Projects, and One Roof never scans your home folder, so macOS does not ask about Desktop, Documents or Downloads. The app ships no keys, no tokens and no datasets: Linear, hosted models and gated benchmarks use your own accounts, only if you add them. A crash in one session ends only that session. Underneath sits the roof kit, which makes every agent read the same rules; roof install puts it in place and roof doctor checks every layer, covering a shell default that moves a new terminal opening in ~ to your workspace, agent wrappers, PATH stand-ins, a Claude hook that blocks every prompt while a Claude session is outside the workspace, home notes in ~/CLAUDE.md and ~/AGENTS.md, and a single Claude memory pin whichever folder you launch from. The practical benefit is that you keep the deciding role while the agents do the work. Questions stop getting lost in tabs you are not watching, overnight runs stop being a mystery, and you no longer need to read every agent's full output stream to know what happened. Sessions are labelled with their state, agent, account and folder so the one you need is findable, and Resources makes it clear which session is slowing the Mac. The app is neutral by design: Claude Code, Codex, Gemini CLI, Kimi and Antigravity run side by side rather than inside one vendor's app, and the bar at the foot of the window shows how much of each subscription is used so you can pick the agent with room left. Typical use follows the chorus coding idea the project describes: several coding agents on the same piece of work, each doing the part it does best and one checking another — one plans, one builds, one reviews — while a loop re-runs the tests every night. You might press ⌘N, say what should happen, pick the agent and the repo, and launch; when the agent asks something it shows up in the Inbox. Overnight, loops run and the morning Home page tells you which ones failed and what to do next. When a session's memory grows, Resources flags it and can stop a runaway session. When you want to know how a model handles your own code, you build a question set from your repo's fixed bugs in Evals. One Roof is built for people who already pay for several coding agents and want to use them together: developers running Claude Code, Codex, Gemini CLI, Kimi or Antigravity who need to keep track of what each one is doing, what it costs and what it is waiting on. It requires Apple silicon, macOS 14 or later, git and at least one agent command-line tool that is signed in. Setup finds the agents you are signed in to, and optional extras include hosted models such as OpenCode and Goose with your own API key and a spending cap, and Linear for Projects. One Roof is free and open source under the MIT licence, signed with an Apple Developer ID and notarized by Apple, and can also be built from source with Swift 6 and Xcode 26. In short, One Roof is a place to keep up with a team of coding agents and stay the one who decides: the agents do the work, and you keep up and decide.
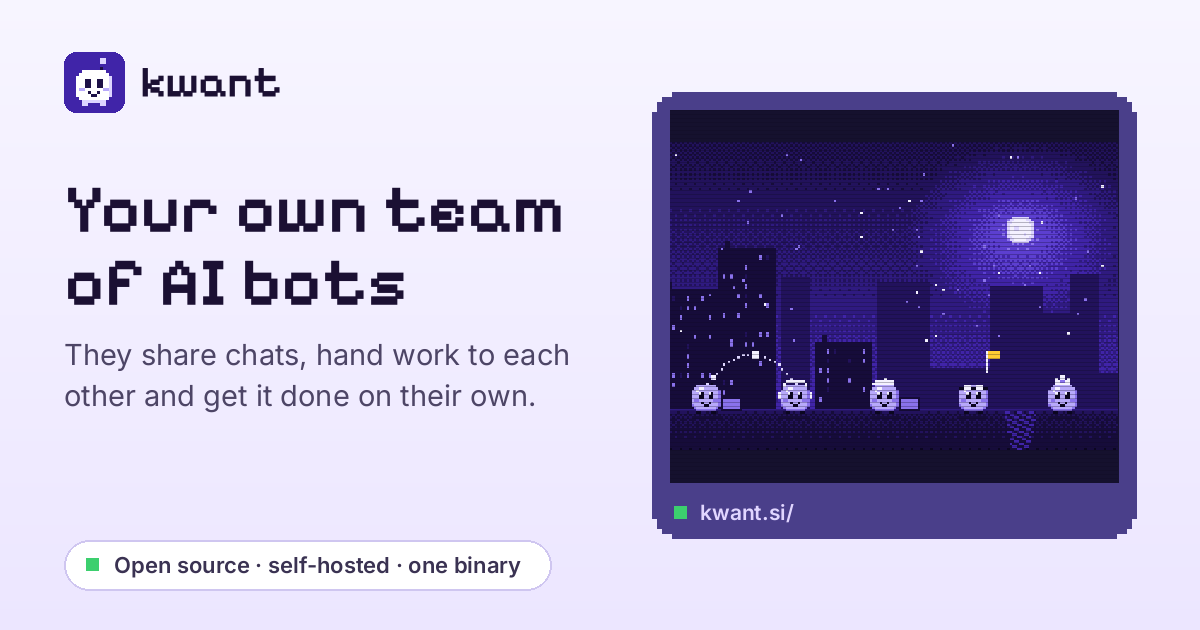
kwant is an open-source, self-hosted team of AI agents that you run on your own machine. The whole product ships as a single binary, called kwnt, which you can install on a laptop or a VPS and which brings the app and the database with it. Instead of a single chat tab, you get a group of bots, each with its own role, voice and model, that share chats, pass work to each other with @mentions and keep going on a schedule even after you close the tab. It is built for people who want an AI team that proves its work rather than simply announcing that a job is done. Most AI tools answer a question and then declare the job finished, leaving you to take the model's word for it. kwant takes a different position: chat apps and agent frameworks can do the work, but they rarely prove it. In a typical chat assistant there is one assistant per chat, one answer is picked for you, and when facts conflict you only ever see the version that was chosen. Agent frameworks can be wired up to do better, but you have to build the routing, the evaluations and the approvals yourself. kwant is built around the idea that a result should be checked, that a fact should open at the exact quote it came from, and that nothing should be paid without you. Each bot has its own role, voice and model, and knows who else is in the room. You hire bots from 27 roles, and each message goes to the bot that fits, with kwant picking the bot, the model and the effort and showing you why. When one bot finishes its part it hands the work on with an @mention: in the product's own example, TechLead takes a request to ship a pricing page and passes the layout to Designer, who then asks QA to check the layouts on a phone. Team discussions work the same way, with the lead running a short discussion and posting a single summary, while the full fold of every turn stays available to read. New teammates are added from presets such as Security, Research or Chef, and the name, role, avatar and voice fill in automatically. Verified results are the core of the product. Bots split work into cards, and a card turns Verified only when kwant runs the check itself, so "done" means it was actually checked. Web facts come with links that open at the exact quote, and no quote on the page means no claim. When two facts conflict, they wait for you: the Truth Ledger shows both and you keep one. Goals let you state what should stay true, kwant checks it, and when a goal breaks a bot offers one fix for you to approve. Smart Results turns a table or list in a reply into a comparison you can sort, a chart or a checklist, copied word for word. Risky steps are handled deliberately. Ordinary work just runs, but something risky, like a push, a network call or a change outside the bot's folder, shows you exactly what will happen first, with the full arguments in front of you and Allow once, Always allow or Deny as the options. That prompt can be switched off too. Payments always ask, even when they sit behind a plain "Continue". Autonomy is earned rather than assumed: in Flight School bots earn tiers per kind of work, only you grant them, and new bots start at Act. AutoFix, audits, Flight School and the Truth Ledger all run without setup. kwant is designed to keep going when you are not watching. Say "every morning" and the bot sets up the routine itself, with Undo, Edit and Pause on the card, or you can create one for daily, weekly, every few minutes or a cron rule. The Inbox page collects what happened while you were away on one screen: what is waiting on you, what finished, and what got stuck. Loose ends finds the reply you owe across chats, email and GitHub and drafts it, though it never sends. Letters lets you photograph a bill or notice so kwant can pull out the deadline and amounts and remind you. Accounts and spaces keep everything separated. You can use Claude, Codex or Grok logins you already pay for, API keys or your own server, and when one account runs out of usage the turn moves to the next in your order across Claude, Codex, Grok and Custom API, with the chat saying so. Spaces give work, side projects and home their own bots, chats, routines and accounts so nothing leaks between them; each space gets a name, an icon and a colour, switches with Command or Ctrl plus 1 to 9, and opens where you left it. Getting started requires Rust and Node.js to build it plus one AI account. You run make run, the web app opens on your machine, and on a server you open the link it prints once. Accounts are added by using a CLI you are already signed in to or by pasting a key, and you can add as many as you like. There are downloads for Mac, as a universal build for Apple silicon and Intel that is not yet notarized by Apple, and for Linux as a .deb for Ubuntu and Debian on x86_64 or an AppImage, plus a Docker option. kwant is AGPL-3.0 open source, at version 0.6.8 with 19 releases since October 25. Typical scenarios follow the shape of a working day. A research bot runs every weekday at 07:00, sums up three new app reviews, spots a price change on a rival's site and puts a draft reply in Loose ends for you to review the next morning. A team ships a pricing page by handing the layout to a designer and the phone check to QA. Parallel Universe load-tests up to three ways to deploy on your own server before you pick one. You approve an action from your phone away from your desk, or photograph a notice to have the November 5 deadline pulled out and tracked. kwant is aimed at people who want an AI team on their own hardware without writing code. It works with Claude Code, Codex, Grok, API keys, any MCP server, Ollama and any OpenAI-compatible server, and runs on Mac, Linux and Docker. It is free and open source, and you bring the model accounts you already have. The takeaway is straightforward: kwant gives you your own self-hosted team of AI bots that share chats, hand off work, check each other, quote their sources and ask before they spend, all from one binary on your laptop or server.
MachineMail is an email API built for AI agents. It gives each agent a real inbox that it can sign up with, wait on, and reply from, so an agent can send and receive actual email instead of being confined to a chat window. Agents connect over MCP from any client — the site lists Claude Code, Codex, OpenCode and Copilot — or through an API. Every inbound message arrives as agent-safe text with a trust level attached, and the agent reads it over MCP wherever it runs. MachineMail is aimed at developers and teams building autonomous agents that need a working email address to complete real tasks, and it presents itself as email for both humans and bots, with no per-inbox fee. Agents increasingly need an email address to do real work: to sign up for a service, receive a one-time code, wait for a reply, or take in an invoice. Handing an agent a mailbox is risky, because everything that lands in an inbox is untrusted input written by someone else. MachineMail frames this as the core problem — the site promises that nothing in the inbox can hijack your agent and describes mail your agent can safely read. Instead of passing raw mail through, it converts each inbound message into agent-safe text, removes hidden instructions before the agent reads a word, and attaches a trust report and a trust level. A message from a lookalike domain such as paypa1-payouts.ru, for example, is presented with a failed DMARC check, a link display mismatch, hidden text that was removed, and a quarantined level. Connecting an agent takes one command. MachineMail exposes a single Streamable HTTP MCP server, and developers either sign in with OAuth from the MCP client or pass an API key when running in CI. The documented setup command adds the server to Claude Code, and the site says the same prompt works with Cursor, Codex, OpenCode and Copilot, plus any other MCP client. For agents that cannot be configured by hand, the site offers a copyable agent prompt: paste it into Claude Code, Cursor or another MCP client and the agent registers itself through auth.md, receives a sandbox inbox and one ephemeral inbox, and shows a six-digit code that the user enters at /claim to bind the agent to their organization. Addresses are created either with a single API call or automatically through a catch-all domain. Once a domain is pointed at MachineMail, any address on that domain works and the inbox appears on first delivery, which means an agent can be handed an address in advance without provisioning anything first. The site shows a mix of ephemeral inboxes with expiry timers — signup-7f3k@acme.dev expiring in 24 hours, otp-runner@acme.dev in 23 hours, invoice-intake@acme.dev in six days — alongside permanent addresses such as qa-bot-12@acme.dev and support@acme.dev. There is no per-inbox fee: the site states $0 per inbox and per trust report on every plan. The trust layer sits at the centre of the product. Every inbound message receives a trust report and is sorted into one of five levels, and the agent is instructed to act on the level rather than on anything the sender says. Verified messages can be acted on; known messages are summarised; unknown messages are read only; suspicious messages are reduced to reasons only; quarantined messages are withheld entirely. The report itself lists the evidence behind the level — the example on the site includes a failed DMARC result, a link whose display does not match its target, and hidden text removed from the message before the agent saw it. Because the level is attached before the agent reads the text, the agent never has to make its own judgement call about whether a sender is genuine. Delivery can be pull or push. Webhooks push mail into the developer's own stack: they are signed, retried for five days and replayable from the dashboard, with event types such as inbox.created, message.received, message.received.quarantined and message.bounced. Replayability lets a team re-run a delivery after fixing a handler without losing the messages that arrived during the outage. For agents that prefer to fetch, the MCP server provides wait_for_message, which holds the call open until mail actually lands, for up to a minute, so the agent does not have to poll in a loop. In the site's illustration the waiting call returns a message from no-reply@acme.dev with a verified trust level and agent-safe text containing a one-time code. MachineMail's overall approach is to handle the email plumbing and the security judgement in one place, then expose only the safe result to the agent. A trust level is not a single check but a combination of SPF, DKIM and DMARC alignment, the account's own allow and block lists, prior correspondence with the sender, link and attachment checks, and a classifier. The report lists every reason it used, so a developer can see exactly why a message was verified or quarantined and can adjust their allow and block lists accordingly. Because the same report is produced on every message, on every plan, at no extra cost, the trust decision stays consistent whether an agent is reading a one-time code, an invoice or a support request. The practical benefit is that an agent can be given a genuine email identity without also being given an attack surface. The agent gets an address it can sign up with and reply from, mail it can read as clean text rather than raw HTML, and an explicit instruction about how much to trust each message. Developers get a managed inbox they do not have to provision one by one, webhook delivery they can replay, and a return call that blocks until mail lands instead of burning cycles on polling. Ephemeral inboxes add a disposable option: addresses that expire on their own and are cleaned up by a reaper, so short-lived agents do not leave mailboxes behind. The example addresses on the site map onto concrete workflows. A signup inbox such as signup-7f3k@acme.dev lets an agent register for a service and receive the confirmation, then disappear after 24 hours. An address like otp-runner@acme.dev is built for receiving one-time codes, which is exactly what wait_for_message is shown returning. invoice-intake@acme.dev covers a longer six-day window for documents that arrive asynchronously, while permanent addresses such as qa-bot-12@acme.dev and support@acme.dev suit bots that need a stable, long-running mailbox for testing flows or handling support correspondence. In each case the agent reads agent-safe text with a trust level rather than the raw message. MachineMail is built for developers and teams running autonomous agents — particularly those working in Claude Code, Cursor, Codex, OpenCode or Copilot — who need their agents to hold a real address. Pricing starts free: the Free plan costs $0 and covers 3,000 messages a month, with paid plans starting at $9 a month and no per-inbox charge. A message counts as each inbound delivery and each outbound send, while spam, quarantined and rejected mail do not count, and neither do drafts until they send. Ephemeral inboxes are cleaned up by a reaper that deletes the inbox with its messages, raw MIME and attachments, then emits inbox.expired, and new mail before expiry pushes the deadline out. The API is described as AgentMail-compatible. In short, MachineMail gives AI agents what they have been missing — a real, low-cost email address — and pairs it with the thing an inbox full of untrusted mail actually requires: a per-message trust report, a defined level of action, and agent-safe text that has already had hidden instructions stripped out before the agent reads a single word.
CutCat is a free Chrome extension that mutes or skips mature content, nudity and gore while you watch Netflix. It works from scenes that other viewers have already marked, so the film keeps playing and you simply do not sit through that part. The extension runs inside the Netflix player you already use in Chrome on a computer, and it is not affiliated with Netflix. Its promise is deliberately narrow: keep watching, skip the scene. CutCat is built for people who want to stay with a series or a film but would rather not sit through nudity, gore, strong language, kissing or credits, and who want to decide for themselves which of those categories count. The problem it addresses is a familiar one for anyone watching a title that mixes a story they want with material they do not. A marked scene arrives, and the viewer is left to either sit through it or reach for the remote and guess where it ends. CutCat removes that guesswork by relying on viewers who got there first: the exact stretch of a film or episode has already been identified by someone else, and that mark is what the extension acts on. Because the marks are shared across everyone using CutCat, the effort of finding and timing a scene only has to be made once. The catalogue is presented openly on the site, so a viewer can see what is covered before starting a title, and it grows as viewers mark more. Skipping is the first of the two core behaviours. When playback reaches a marked stretch, CutCat jumps the whole stretch rather than blurring, dimming or fast-forwarding it. The story continues either side of the gap, and the part in between is never shown. This is the behaviour used for the categories the site lists as skipped: mature content, nudity, violence and gore, kissing and credits. Because the jump covers the entire marked stretch rather than a guessed interval, the viewer does not have to scrub back to check whether the scene is really over. Muting is the second behaviour, and it is handled differently on purpose. When a word or a line is marked, only that line is silenced, and the sound comes straight back afterwards. The site describes the mute as measured to the frame, so the scene around the line is not lost. That distinction matters for strong language: a viewer who does not mind the scene itself but would rather not hear the profanity can keep the picture, the performances and the surrounding dialogue intact instead of losing whole minutes of a conversation. Skipping and muting therefore serve two different viewing preferences within the same extension. Control over categories is the third piece. Every category can be switched off, and the settings stay in your browser. The site lists the categories as mature content, nudity, violence and gore, strong language and kissing, each with its own switch, and describes the outcome in plain terms: switch whole categories on or off, and mute strong language and skip nothing else if that is what you want. This means the extension does not impose a single definition of acceptable content. A viewer can mute profanity only, skip nudity and mature content, or leave gore in place, without having to configure anything complicated or explain their choice to anyone. Overall, the approach is shared marking plus local playback control. CutCat does not analyse the video itself, and the site is explicit that nothing is downloaded or altered. When playback reaches a marked stretch it jumps past it, or the sound drops for a marked line and comes straight back. On a film or episode that nobody has marked, it plays as normal, because CutCat only acts on scenes viewers have marked. The coverage list on the site is the practical companion to that rule: it currently reports roughly 1,500 scenes marked across roughly 150 titles, on 2,500 films and episodes, and the list grows as viewers mark more. The outcomes for a viewer follow directly from those mechanics. A title that would otherwise be abandoned can be watched through, because the parts a viewer objects to are removed without touching the rest of the film. Nothing is re-encoded and nothing is edited permanently, so the viewing experience either side of a mark stays as it was. Privacy is stated just as plainly: CutCat never records what you watch, and your category settings stay in your browser, with the privacy policy listing exactly what is and is not collected. It is free and has no ads, so there is no subscription to manage and no advertising layer inside the player. Concrete use cases come straight from the coverage the site publishes. Someone working through Breaking Bad, with 115 scenes marked, or Dark, with 107, can watch with marked stretches removed. A viewer who wants Bridgerton (58 scenes marked) or Outlander (74) without the mature content can skip those stretches while keeping the drama. A viewer who cares about language but not about violence can leave the skip categories off and mute strong language only. Anyone unsure about a title can hover or drag through the coverage list first, then put the extension on and forget it is there. Because credits are one of the listed categories, it also covers viewers who simply want the credits skipped. The target user is someone who watches Netflix in Chrome on a computer and wants a filter they control, rather than a rating or a general-purpose parental control. Product Hunt lists the product under Chrome Extensions, Parenting and Streaming Services, which reflects that mix of everyday viewers and parents choosing what plays in front of others. The restrictions are stated without hedging: CutCat is a Chrome extension, so it runs in Chrome on a computer and cannot be installed on a phone, a tablet or a smart TV, and it works on Netflix only, not on Prime Video, Hotstar or other services. Pricing is free with no ads, and any category can be switched off at any time. The published catalogue shows where the coverage is deepest. Breaking Bad leads with 115 scenes marked, followed by Dark on 107, Outlander on 74, Bridgerton on 58, Vikings on 54, Spartacus on 52, Shameless on 45, Castlevania on 44, You on 42, Squid Game on 37 and 13 Reasons Why on 34. Further down the list are Cyberpunk: Edgerunners on 27, The Platform and Bodies on 26 each, UNABOMBER on 25, Troy: Fall of a City and The Witcher on 24, Apex on 22, Captain Fall on 20, Ozark on 19, Colors of Evil: Red and Unfamiliar on 18, The Tudors on 17, Something Very Bad Is Going to Happen and Stranger Things on 16, and American Psycho, Unlocked, The Beast in Me, Black Mirror and Peaky Blinders on 15 each. The list is a snapshot rather than a fixed set. CutCat is best understood as a small, single-purpose tool that does one job in the Netflix player and then stays out of the way. It skips or mutes marked scenes, lets the viewer choose which categories apply, keeps settings in the browser, records nothing about what is watched, and costs nothing. The value proposition is the sentence the site opens with: keep watching, skip the scene. Put it on, then forget it is there.