Category Focus/categories/developer-tools
Developer Tools AI Tools
Discover and compare the best developer tools AI tools and software. Browse 571+ curated tools with reviews and rankings.
Projects tracked
571
Sort mode
RECENT
Page
3
Discover and compare the best developer tools AI tools and software. Browse 571+ curated tools with reviews and rankings.
Projects tracked
571
Sort mode
RECENT
Page
3
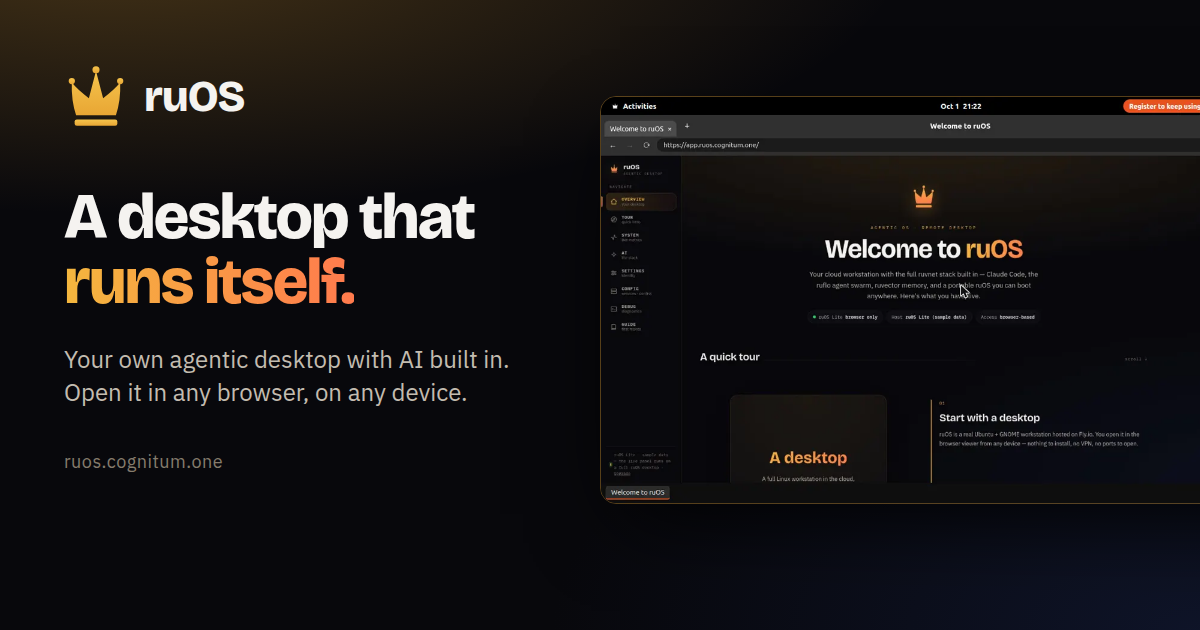
ruOS is a private cloud desktop with an AI team built in. Instead of installing software or waiting for a machine, you sign up and get your own agentic desktop, bound to your account, that starts in seconds with the whole AI stack preinstalled and signed in — Claude Code, a team of AI helpers, and self-learning memory, all ready to go. You ask for research, writing or code and the helpers do it side by side, either while you watch or after you step away. The whole desktop opens in any web browser and reshapes to fit any screen, so the same session works on a Mac, an iPad, a Chromebook or a Linux laptop. Most people who want AI to do real work end up assembling it themselves: installing editors, wiring up agents, keeping contexts straight across tools, and repeating the same explanations to a model that has already forgotten the project. ruOS starts from the opposite position. There is no machine to wait for and nothing to configure — the desktop turns on with its AI helpers already installed and signed in, and everything the AI learns is saved automatically so you never explain twice. Files and AI memory persist across devices, so the desktop is not tied to the laptop you happened to start on. The point is to remove the setup and the syncing, not to add another tool you have to manage. At the center of ruOS is a set of AI helpers that ship ready on the desktop. Claude Code writes and runs code for you. ruflo acts as a team of AI helpers, splitting a big job across several agents that work side by side. ruvector remembers your work, so projects carry their context forward. ruview understands what is on your screen. Codex provides extra coding help, and VS Code, the code editor, is part of the dock. Together they turn a request into finished work: tell it what you want changed and it edits the files, runs the tests, and tells you when it is done. Ask a question and it browses the web, reads the sources, and brings back the answer. ruOS runs as a desktop that streams to any web browser and reshapes to the screen it lands on — the same session on your Mac, iPad, or laptop, with nothing to install and nothing to sync. It fits any window the moment you open it: sharp on a big monitor and comfortable on a tablet, with no fiddling with zoom. Because the desktop is not tied to one machine, you can start work on your laptop and keep going on your iPad. ruOS Lite takes the same idea and removes the wait entirely: it is a real Chrome browser drawn as your ruOS desktop, right inside your web page, opening in about a second with tabs and windows, a dock of apps, and the ruOS app first. It is free and needs no sign-up. ruOS picks up where you left off. Files and everything the AI has learned are saved automatically, so you can come back tomorrow and continue — even from a different device. In ruOS Lite, sign-ins, site data and open tabs are saved and encrypted. VS Code runs from the dock as vscode.dev, with extensions such as 1Password, Bitwarden, Claude and uBlock Origin Lite available when you turn them on. Your AI can drive the desktop too: ChatGPT and Claude see and click it through the ruOS connector, but never your extensions, and payments wait for you. Each desktop is your own — your files, your work, your AI — kept separate and private from everyone else's. The setup is four steps. First, you sign up: enter your email and ruOS sets up a private agentic desktop bound to your account, with no setup and nothing to configure, ready in minutes. Second, your desktop turns on in seconds with the AI stack preinstalled and signed in. Third, the AI gets to work: ask for something and a team of helpers researches, writes, and codes while you watch, or step away and come back to finished work. Fourth, you open it anywhere — the desktop streams to any browser and reshapes to the screen. Under the hood, for developers and power users, it is a real Linux box with the full ruvnet stack and programmatic control already installed. The payoff is that work happens without you operating every step. Hand ruOS a job and it picks the right tool and gets to work; the helpers write and run code, research on the web, remember your projects, and understand what is on your screen, all from one agentic desktop. Big jobs get split across several AI helpers instead of queuing behind one. Because memory persists, you avoid re-explaining the project each time. Because the desktop lives in a browser, your environment follows you rather than being locked to one machine. And because your desktop is private and separate, your files, your work and your AI stay your own. Concrete uses map directly to what you can ask for. Code: tell ruOS what you want changed, and it edits the files, runs the tests, and reports when it is done. Research: ask a question and it browses the web, reads the sources, and brings back the answer. Parallel work: split a big job across several AI helpers that work side by side. Cross-device continuity: start on your laptop and keep going on your iPad. Browser-first sessions: ruOS Lite gives you a Chrome-based desktop with VS Code, Wikipedia and ChatGPT in windows and a taskbar in about a second, useful for trying the environment or working on a Chromebook, iPad or locked-down machine. Developer automation: point an MCP client such as Claude at your desktop and let it drive the machine. ruOS ships an MCP server, ruos-computeruse-mcp, that lets an AI client drive the desktop for real: see the screen, move the mouse and type, run shell commands, trigger system actions, and change the resolution on the fly, using tools such as screenshot, mouse_move, left_click, type_text and key via xdotool, run_shell, system_action and desktop_resolution. You can point a client at the desktop with stdio over SSH, or connect through the hosted address at the quick start page — ChatGPT under Settings, Apps & Connectors, Create; Claude under Settings, Connectors, Add custom connector; and Claude Code with a single command. Resolution presets include 720p, 1080p, 1440p, qxga or a custom width by height, applied server-side via xrandr, with a hosted MCP endpoint on the roadmap. The preinstalled ruvnet stack is one command away too: npx ruflo@latest init wizard for agent-swarm orchestration, npx ruflo@latest swarm init --topology hierarchical to spin up a team of AI agents, npx ruvector for long-term self-learning memory, and npx ruflo to run the ruflo agent runtime. ruOS is built for people who want AI to carry work through to completion without a local setup project — developers and power users who want a real Linux box with programmatic control, and anyone who wants research, writing and code handled from a browser on whatever device is in front of them. It is free to try, since ruOS Lite opens in seconds with no sign-up, while early access to your own private agentic desktop requires a sign-up and the desktop is ready a few minutes later. In ChatGPT, ruOS uses only the desktops and metered entitlements already assigned to your account, and the ChatGPT app and its linked review surfaces do not present pricing, checkout, subscriptions, upgrades or credit purchases. The takeaway is simple: sign up once, and your desktop does the rest. ruOS puts a private agentic desktop in any browser, with an AI team that researches, writes and codes for you while you watch or step away, and keeps your files and memory waiting when you return.
Coddy is an interactive platform for learning to code through short, gamified lessons. It covers more than 20 languages and technologies, including Python, JavaScript, TypeScript, React, Next.js, HTML, CSS, Java, C++, SQL, C, C#, PHP, Dart, Go, R, Rust, Lua, Luau, Ruby, Swift, SwiftUI, Verilog, Solidity, Kotlin and Assembly, plus adjacent skills such as AI Prompts, Terminal, Excel, Git, Docker and Kubernetes. Learners write and run real code in the browser, from their first line to a finished project, with no setup required. The product is available on web, iOS and Android, describes itself as free to start, and states that more than 5,540,471 codders have joined. Its stated goal is to make learning to code feel like a game you want to return to every day. The problem Coddy addresses is explained directly by its founders, Barak, Nati and Kevin: 'We built Coddy because learning to code should feel like a game you want to come back to every day, not a textbook you dread.' The Product Hunt description frames the same issue differently, saying Coddy teaches you to code with short, interactive lessons you actually finish. Many beginners abandon traditional courses because the material is long, passive and disconnected from practice. Coddy's response is to break learning into short, interactive lessons built around real coding, and to wrap that learning in game mechanics such as streaks, leagues and rewards that give learners a reason to return each day. It also removes common practical barriers by running everything in the browser and on mobile, so no downloads or environment setup are needed before a lesson can begin. Coddy's core feature is learning by doing. Every lesson is built around a real code editor that runs in the browser, where learners write actual code rather than reading about it. The editor supports running code, viewing a console, and checking work against test cases; the landing page shows test cases passing and failing alongside their expected input and output so learners can see exactly what is correct. The experience is organised into tabs covering Code, SQL, Web, AI Chat and Terminal, which reflects the breadth of the catalogue. A separate Playground lets users write and run code in the browser with no setup, and reference documentation exists for every supported language. The same editor technology can be embedded into other websites through a free, runnable code editor added with a single iframe. Gamification is the second major pillar. Coddy tracks a daily coding habit with a streak counter and a calendar view, and shows how many days remain to keep the streak alive. Streak Freeze items protect the streak, and the interface shows a limited number of freezes remaining, while a Double or Nothing challenge runs across multiple days. Learners also accumulate a score and an energy counter, visible alongside their current language. Goals and Daily Challenges appear in the sidebar navigation alongside Journey, Leaderboard and Profile. Competition is organised through leaderboards such as the Challenger League, where the top seven advance and a promotion zone is displayed. The leaderboard shows ranked learners with their scores and streak length, and the product encourages users to invite friends to earn rewards and compete on global leaderboards. Learning is supported by several reinforcement features. Bugsy, the AI tutor, reads your code and your error, explains what is happening and gives hints, and is explicitly described as never giving the answer. The landing page frames the model as read, listen, test yourself, ask the AI, or look up anything you have already covered. Each lesson can therefore be approached in several ways: an Audio mode narrates lesson content, with playback speed and a named voice; a Quiz lets learners test themselves; Ask AI brings in the tutor; and References let learners look up material they have already covered. Coddy also issues a Certificate of Completion for every course finished. The example certificate names the learner and the course, carries a verified mark, includes a date, and offers a one-click Add to LinkedIn action so the achievement can be added to a LinkedIn profile and resume. The overall approach is a structured journey rather than a flat catalogue. The main screen presents language courses as a path of hexagonal nodes. Completed nodes are marked as done, the current node is highlighted and labelled as a theory challenge, and later nodes are shown locked until earlier ones are finished, with a prominent Continue button driving the next step. Lessons alternate between theory and challenge content, and progress is reflected in the score, streak and energy indicators shown at the top of the journey. Beyond the core journey, Coddy has introduced Spaces: Coding, where users write and run real code from their first line to a finished project; Chess, where users learn the rules, tactics and openings one interactive board at a time; and Math, currently labelled Beta, where users solve equations move by move and draw graphs by hand with every step checked on an interactive board. The stated benefits centre on consistency, completion and proof of skill. Because lessons are short and interactive, the platform's positioning is that learners actually finish them. Streaks, freeze days and rewards are designed to build a daily habit, and leaderboards add social competition and encouragement. Bugsy's hint-only approach is intended to keep learners reasoning through problems rather than copying answers. Certificates give learners a shareable artefact for every completed course, ready for LinkedIn or a resume. Accessibility is part of the value as well: the product is described as available on iOS, Android and Web with 4.9-star ratings, so learners can code anywhere with no setup and no downloads. The product supports a range of concrete scenarios. A complete beginner can start with a first lesson in the browser, use the code editor and test cases to practise, and keep a daily streak going with the support of Streak Freeze on days when they cannot code. A learner preparing for interviews or coursework can follow the path for a specific language such as Python or SQL, listen to the audio version of a lesson, take the quiz, and ask Bugsy for a hint when stuck in the editor. A developer who wants to build a full-stack app can use Coddy Build, which allows chatting, previewing and publishing with AI. A teacher can assign lessons, track progress and grade automatically using the Teachers offering. Anyone who wants to look something up can use the free Tools, Cheat Sheets, Glossary, Git Commands and Visualizations resources, or open the Playground to run code without setup. Coddy is aimed at current and aspiring developers who want to learn to code, supported by the Product Hunt topics that list Android, Education, Developer Tools and Artificial Intelligence. The product also explicitly serves teachers through its Teachers offering, and runs an Affiliate programme that pays commissions on referrals. A dedicated resources section supports learners and developers with Blog, Docs, Playground, Cheat Sheets, Glossary, Git Commands, Visualizations, Certifications and free Tools. On distribution, Coddy is available on web, iOS and Android. Pricing is free to start, with a daily limit on the free tier and paid plans available: the Product Hunt landing page offers visitors a 50% discount on any plan, saved and applied automatically at checkout, and the Product Hunt description states the offer lasts 72 hours. Coddy's value proposition is straightforward: make coding education short, interactive and habit-forming, then make it available everywhere. By combining a real in-browser code editor and test cases with streaks, leaderboards, audio, quizzes and a hint-only AI tutor named Bugsy, Coddy tries to turn daily practice into something learners want to return to. With more than 20 languages, a free entry point with a daily limit, mobile and web apps, and shareable certificates, it targets beginners and developers who would rather build something every day than read a textbook.
OpenBot is a free desktop app that runs a team of AI agents on your own computer. Rather than a single chat window, OpenBot gives you persistent AI teammates: each agent has its own name, instructions and workspace, and agents can send each other messages, hand off tasks and share files while they work. OpenBot connects to Codex, Claude Code, Gemini, Grok, OpenCode, Cursor and Cline, so you can run your agents with the ChatGPT, Claude, Gemini or Grok plan you already pay for, or with your own model. It is available for macOS, Windows and Linux. The usual way to work with an AI assistant is one assistant, one chat, one provider. OpenBot starts from a different assumption: that the AI plans people already pay for should be able to work together as a team on the machine in front of them. OpenBot is positioned as an alternative to Grok Bot, and the site describes it as a free, local, open-source and multiplayer workspace for AI teammates. The problem it addresses is practical. Agent work is fragmented across providers and accounts, an agent loses its context when you close it or switch tools, and everything it touches tends to live on someone else's servers. OpenBot answers those points directly: agents keep their workspace and conversation when you restart the app or move an agent to a different provider, and workspaces, conversations, files and browser data stay on the computer that runs OpenBot rather than on OpenBot's servers. The source code is public on GitHub, so you can read, change and run it for any noncommercial purpose. Agents work as a team. Each agent you create has its own name, its own instructions and its own workspace, so you can describe the agent you want in one prompt, check its instructions and save it. From there the agents act like colleagues rather than tools: they send each other messages, hand off tasks and share files. In the launch example shown on the site, an agent called Research verifies the evidence while Builder checks the rollout path and Launch owns the release, and the user asks the team to prepare the launch plan, tag Research, and keep every decision traceable. The result comes back as a written plan with a workstream table, owners and statuses, plus attached files such as launch-brief.md and launch-metrics.csv. A later message asks the team to turn this into the final launch brief, using @Research's evidence and @Builder's rollout notes and attaching the source files. Because the agents are named and addressable, you can direct work to a specific teammate instead of hoping a single assistant remembers everything. The site also shows an agent handing a task to another agent, who fixes a file, asks a third to review it, and gets the change merged and the issue closed. OpenBot works with the AI plans you already have. Codex signs in with your ChatGPT plan and Claude Code signs in with your Claude plan; Gemini uses a Google AI Pro or Ultra plan, and OpenCode ships free models that need no account at all. Grok, Cursor and Cline are also supported providers. If none of those fit, you can connect any OpenAI-compatible endpoint, or run local models through Ollama or LM Studio. The provider is not a lock-in either: an agent keeps its workspace and conversation when you move it to a different provider, so the same teammate can start a job on one model and continue it on another. In the demo on the site, an agent called Ada begins a billing migration with Codex, which reports that six tables use the billing code and then changes four files and writes the migration, and Ada then continues the work on Claude Code to write the test for that migration. Everything the agents produce is stored on your computer. Workspaces, conversations, files and browser data stay on the machine that runs OpenBot, not on OpenBot's servers; the only external traffic is the prompts your agents send to the AI provider you chose, and the pages an agent opens in its browser. That browser is built into OpenBot: agents can open, read and control pages inside it, which is how they can work through a sign-in screen or a dashboard without you switching windows. OpenBot also lets you queue work. If an agent is already busy, you can send more messages and they wait in a queue that you can pause, resume or cancel, so you can line up the next task without interrupting the current one. And the workspace is multiplayer: you can invite other people to your team and collaborate live with the same agents, which requires an account. OpenBot's approach is to keep the orchestration on your desktop and to treat each model as an interchangeable worker. You download the app, connect a provider, describe the agent you want in one prompt, review its instructions and save it, then send it work immediately. Agents are described as persistent AI teammates, which means an agent is not a conversation you lose when the app restarts: its workspace and its conversation survive restarts and provider changes. Roles, rather than one-off prompts, are the organising unit. One agent can own research, another the build, another the release, and they coordinate by messaging each other and handing off tasks while you steer from the same window. Tasks given to a busy agent simply wait in the queue instead of being dropped. Because OpenBot is free, with no hidden fees and no locked features, the only cost is the AI plan you already pay for. Because it runs locally, your workspaces, conversations, files and browser data remain on your own machine. Because agents keep their workspace and conversation, work can continue across restarts and across providers rather than starting from zero each time. Because agents have names, instructions and their own workspaces, responsibility for a task is visible and handoffs between teammates are explicit. And because the source is public under the PolyForm Noncommercial License 1.0.0, you can read, change and run the code for any noncommercial purpose, although commercial use needs a separate license. OpenBot is explicit that it is a development preview: agents can read and change files, run commands, use the network and control the built-in browser without asking each time, so it advises giving them only tasks you trust and keeping backups. From the material on the site, OpenBot's use cases cluster around multi-step work that benefits from several specialised agents. Launch coordination is one: preparing a launch plan, tagging work, verifying claims and evidence, checking a rollout path, confirming the rollback owner and publishing a release note. Software changes are another: reading billing code, moving tables to their own schema, editing files, writing a migration and then writing the test for it, with a second agent reviewing a change before it is merged and the issue closed. Ongoing operational chores are a third: summarising the support inbox, drafting release notes and checking new sign-ups, all queued up while another agent is busy. Web-based tasks are a fourth, since an agent can drive the built-in browser through a page such as a sign-in screen or a dashboard as part of its work. And for anyone who wants to avoid hosted plans, Ollama or LM Studio plus an OpenAI-compatible endpoint covers the local-model path. OpenBot is aimed at people who already pay for an AI plan and want more than a single chatbot: developers, small product teams and anyone coordinating multi-step work, including teams that want to share the same agents live. It runs on macOS 13 or newer on Apple silicon or Intel, Windows 10 or newer on x64, and Linux on x64 or arm64 as an AppImage. No account is needed to use the app; you only need one to invite other people to your team. Pricing is $0, with no hidden fees and no locked features, and the code is published on GitHub under the PolyForm Noncommercial License 1.0.0, which is not an OSI open-source license because commercial use requires a separate license. OpenBot is, in short, a free and open-source desktop workspace that turns the AI plans you already pay for into a persistent team of local agents, complete with roles, handoffs, shared files, a built-in browser, a task queue and live multiplayer collaboration, all running on your own computer.
AUDR — Agent Usage Detail Record — is an open standard for recording who initiated an agent run and how much each cost, across every system a run passes through. It defines a common JSON schema that any harness, router, or billing system can emit and ingest, so a single agent run can be represented through records that share a common structure. AUDR was drafted at Chargebee, is licensed under Apache 2.0, and is stewarded by Chargebee, with the stated goal of moving cost governance to an independent foundation as adoption grows. It is useful anywhere you need a reliable record of what an agent run consumed and who or what it was associated with. The problem AUDR addresses is that a single agent run touches multiple systems. The application knows the customer and the feature. The router knows the tokens and the cost. The tools know what they executed. As the project describes it, a run can be fully observable at every individual layer and still leave you without a single end-to-end record of who ran it and what it cost. Without a shared way to join these observations, usage data is orphaned from the business context that gives it meaning. The telecom industry solved an analogous problem with the Call Detail Record, an open standard carriers converged on so a call's attributes could be captured and exchanged in a common format, independent of any single carrier's systems. AUDR is built on the same principle: a common record for agent runs that any harness, router, or billing system can emit and ingest to help businesses make sense of the economics at the run level. AUDR works through three rules. The first is a shared run ID, minted by the harness, passed to the router in request metadata, and echoed back, so that every system that touches the run carries the same ID. The second is clear authority per field: the harness owns attribution — customer, environment, initiator — while the router owns usage — tokens, provider. Each fact has exactly one source. A record carries the raw counts that drive cost, such as tokens, tool calls, and seconds of compute, alongside the business context that says whose cost it is: customer, feature, environment. Every layer keeps reporting what it already reports, and AUDR adds the rules that let those reports come together into one record. The third rule is strict merge rules. The sink assembles records sharing a run and span ID, and no component rewrites another's block. Conflicts are rejected, and a correction is a new record, never a mutation. The documentation illustrates this with a sample record in which run.run_id is "run_8f2a1c" (minted by the harness) and span_id is "span_4b91"; attribution includes a customer_id of "acme-corp" and an initiator of "end_user", both sourced from the harness; usage includes llm input_tokens of 1204 and output_tokens of 318, sourced from the router; and the emitter component is "router". One record, one authoritative source per field. Adapters capture records from the runtime you already use. The Core SDK builds, validates and delivers records straight from your own code, available in Python (audr) and TypeScript (@openaudr/audr), and every adapter and sink builds on it. NVIDIA NeMo Relay records completed LLM and tool scopes, with attribution read from the root scope's metadata (Python, audr-adapter-nemo-relay). LiteLLM registers as a callback on the SDK or Router and records completion, Responses API, embedding and rerank calls (Python, audr-adapter-litellm). Merge Gateway wraps the native SDK client and records every response, streamed or not, using the gateway's own token and cost report (TypeScript, @openaudr/audr-adapter-merge-gateway). Vercel AI SDK registers as an AI SDK 7 telemetry integration and records model, tool, embedding and rerank calls (TypeScript, @openaudr/audr-adapter-vercel-ai). Mastra registers as an observability exporter and records model, embedding and tool calls (TypeScript, @openaudr/audr-adapter-mastra). Adapters read identifiers, usage and timings, never prompts or outputs, and every package is Apache 2.0 and published to PyPI or npm. Sinks deliver records to your destination. The flow is runtime to adapter to core client to sink to destination. The Chargebee sink delivers records to a Chargebee site's usage-ingest batch endpoint for usage-based billing (Python audr-sink-chargebee and TypeScript @openaudr/audr-sink-chargebee), and the Lago sink delivers records to Lago's batch event endpoint for usage-based billing (TypeScript @openaudr/audr-sink-lago). Running something else? The core SDK emits records directly from your own code, and any destination can be reached with a new sink. To try it, you register an adapter with the runtime you already use and get a usage record for every model and tool call, including the customer it belongs to; you can write the records to a local file to start, with no account, hosted backend, or pricing configuration needed. AUDR is designed to sit on top of OpenTelemetry, not compete with it. OTel's GenAI semantic conventions provide the foundation for describing model calls and usage, and AUDR reuses them: an AUDR record can be emitted as an OTel span, and the OTel collector is a first-class sink. What OTel does not define is the set of rules needed when usage becomes a durable record — which attributes are required, how attribution is handled when it is missing, how retries remain idempotent, or how corrections are made. Observability can tolerate a dropped span; a usage record cannot, which is why AUDR adds those requirements and delivery semantics on top. FOCUS solves a different part of the same problem: it standardizes the billing data you receive from providers so costs from AWS, Azure and others can be represented in a common schema, while AUDR standardizes the usage you emit when an agent run happens, before that usage is priced. The two are complementary, and AUDR records can be rated by any backend and mapped into FOCUS-compatible cost data, completing the upstream half of an existing standard. The practical benefit is being able to answer concrete questions about agent economics at the run level. Wrap your router, emit the records, and AUDR can help you answer questions such as: How much does this agentic feature cost? What does this customer's agent usage look like, and how much does it cost? What are the unit economics and margins per customer for my agentic features? Which workflows or models are driving our costs? Which power users are driving our costs? AUDR adds nothing in the normal request path: it emits records asynchronously and out of band, so recording usage does not add synchronous work to inference. The one exception is optional pre-flight budget gating, which would make a single check before a run starts. Because the spec carries no prices or rating logic and the SDK has no concept of plans, invoices, or how a customer should be charged, AUDR records what happened and who it happened for, leaving what you do with that data up to you. You can point the records at Chargebee, a competing rating engine, your own, or a warehouse for analytics, and AUDR works the same way. You do not need a billing system to use it: records can be stored locally, sent to your warehouse, fed into an observability system, or used for internal cost analysis or future projections. A billing system is just one possible consumer of the record. Today five adapters, two sinks and the core SDK are published, in Python, TypeScript or both: adapters for NVIDIA NeMo Relay, LiteLLM, Merge Gateway, Vercel AI SDK and Mastra, and sinks for Chargebee and Lago. Support for OpenRouter is in development. The three rules at the core of AUDR are stable — one run ID across every layer, one authoritative source per field, and strict merging with no silent overwrites — and will not change without a major version, while the field set will continue to grow as providers introduce new things to measure. The project invites involvement: read the spec for the full schema, field ownership rules and delivery semantics; write an adapter for a harness or router not yet reached, which the project describes as roughly 200 lines against the shared fixtures; write a sink for a warehouse, ledger or billing system you already deliver usage to; or open an issue with a specific account of where a design decision breaks. Questions can be sent to audr@chargebee.com. In short, AUDR is an open, Apache 2.0 standard that turns fragmented per-layer observability into one joined record of who initiated an agent run and what it cost, giving teams building and monetizing agents a neutral, vendor-independent foundation for understanding agent economics and cost governance.
Rill is a free browser for Mac where the Claude Code and Codex agents you already use work beside you. It is an AI-native browser built around the coding agents you already have rather than a new assistant of its own. You browse normally, and when something on a page gives you an idea, you press ⌘E to turn what you are looking at into a task for your agent. Rill finds the right project, passes along the context, and the agent works while you keep browsing. Rill is for people who already run Claude Code or Codex on their Mac and want to hand work to those agents from the page where the thought actually arrived. An idea used to mean switching to the terminal. The moment you found something worth acting on — a method in a paper, a release note worth testing, a row in a table of consumer prices, or a page whose look you liked — you had to leave what you were reading, open a terminal, and describe from memory what you had just seen. Rill starts from the opposite position: you say it where you found it. Because the browser already holds the page, the text you selected, the row you pointed at with a click, or the paragraph you highlighted, the request travels with its context attached instead of being paraphrased. Rill also knows where the work goes. Your browser knows your projects, so each request lands in the right one without you having to work out which project a passing thought belonged to. The core gesture is ⌘E on any page. Pressing it opens a small note over the page you are reading, where you write your task or question. Rill finds your projects in your Claude Code and Codex history, and there is nothing to set up — no project list to maintain, no configuration to write. In the demonstrations shown on the site, a task written over an arXiv paper, "Try this method on my data.", is routed to the project longitudinal-study. A task written over the Polars 2.0 release post, "Try this on one lesson.", goes to lessons. A task that carries the page and a single row of a table you pointed at, "Chart this against last year.", goes to newsroom-charts. A task over a type foundry page that carries the page and a paragraph you pointed at, "Make my project pages like this.", goes to portfolio. When the request is not code at all, it goes to the web instead: a note over Wikipedia's article about New York City, "Find a nonstop from SF to NYC, Nov 12 to 16.", is sent on the web, and your agent goes looking in a tab behind yours. You never have to go and check on the work. While you read, agents at work are shown with their model, and tasks in a project are listed where you can see them. When an agent needs something from you, it asks in the corner rather than making you open a terminal to find out. In the site's demonstration, a task on the web for a nonstop flight sends a bubble over the essay being read: "Nonstop from SF to NYC. Needs your answer. Morning or afternoon departure?" with Morning and Afternoon buttons and a Reply box. You can answer it or keep scrolling; once answered, the agent carries on in the same tab. It reports back when it is done — the sample result for the chart task reads "Done · 2 files changed". Alongside the agent work, Rill tidies the parts of browsing that accumulate. Your tabs are sorted by AI into themes, each with a one-line summary — the screenshots show groups such as Music videos, Land and climate, Art collection and Space imagery, and on the start page, Art collection and Understanding music. Your history reads like a journal rather than a list: it shows where you went, what you asked for, and what got done, summed up in a sentence with a ribbon of the day. One example reads "History for Sunday, September 27: 64 pages in six stretches". After a few weeks, every project your agents have touched appears on one map — 38 projects in the demonstration, named by AI into areas such as Research and data, Writing and publishing, Design, Teaching, Home and life, and Tools and code, with the finished ones lit as Done. Talking is also available in beta: hold Fn and say the task instead of typing it, after setting it up once in Settings › Talking. Rill's approach is to make the browser the interface for the agent, on the reasoning that the best interface for agents is just the browser. Setup is three steps. You download Rill and drag it to Applications; you sign in to Claude Code or Codex, using either or both, with Rill walking you through it; and then you press ⌘E on any page. The AI features run the Claude Code or Codex on your Mac, under your own account, so Rill runs on the plan you already have — no new subscription and no API keys. Everything the agent needs about your projects and your context is already present in the browser window you are looking at. The benefit is that the gap between noticing something and acting on it closes. You do not copy a URL, re-describe a table row in words, or try to remember which project a thought belonged to; the page, the selection and the destination travel with the request. You keep reading while the work happens, and you are told — in a bubble beside the page — when you are needed and when the task is finished. Because your tabs are grouped and your history is summarised by day, the browsing you did around the work is legible afterwards rather than lost. And because Rill presents the result in the same window, checking on the agent no longer means leaving what you were doing. The scenarios on the site show the range. You are reading a paper on changepoint methods and send "Try this method on my data." to a project called longitudinal-study; while you browsed the page, the chart got made — a chart titled "July surface water temperature: one step, not a slope" for three lakes. You read a release note worth testing and send it to your lessons project. You point at one row of a table of consumer prices and ask for it to be charted against last year, for a newsroom project. You find a page whose look you like and send it to portfolio with "Make my project pages like this." You ask the same way for something that is not code at all — a nonstop flight from SF to NYC in November — and your agent goes looking in a tab behind yours. Or, holding Fn, you say "Add a dark mode to the customer portal that follows the system setting." and the agent gets to work in the customer-portal project. Rill is for Mac users who already run Claude Code, Codex, or both, and who want to point those agents at things they find while browsing; browsing itself works without either, and Rill also works as a browser without an agent. Without an agent you can ask about a page and get the answer beside it from the agent you already use, compare up to six tabs in a table that quotes each page, and let agents in a project read the web in tabs of their own, without your logins, which you can take over when you want. The basics are covered too: passwords in your Keychain, private windows, and sign-ins brought over from Chrome, Arc or Safari. Privacy is local by design — your history and passwords live on your Mac, history is kept as files for as long as you choose, passwords sit in the Keychain unlocked with Touch ID, and tab sorting and day summaries can be turned off in Settings. New tasks are read-only until you allow edits, and in git repositories each edit can be undone. A task on the web is told to stop before the step that pays, places an order, sends, posts or deletes unless you plainly told it to go through with it, and it cannot type into password, card or one-time-code fields. Rill is free, in beta, and runs on Macs with Apple silicon on macOS 14 or later. Rill's proposition is simple: your browsing and your agents in one window. It is a free Mac browser that runs on the Claude Code or Codex plan you already have, turns any page into a task with ⌘E, routes that task to the right project automatically, and lets you keep browsing while the agent works beside you.
Reviu is a native desktop app for reviewing the code your coding agents write. It is built for developers who run agentic coding tools such as Claude Code, Codex, or Gemini and want a dedicated place to inspect what those agents produced before it lands on a branch. Rather than treating an agent run as a disposable chat, Reviu turns each task into a durable session with its own conversation, branch, terminal, checkpoints, file edits, and review queue. From that session you watch the agent work, review every diff, send line comments back, and then finish the branch with real Git - staging, rebasing, committing, and pushing without leaving the app. Reviu sums this up by calling itself the review app for code your agent writes. Since the first launch, Reviu was rebuilt from a Git client with an agent panel into a review workspace for coding agents. The gap it targets sits between agent output and a clean commit: an agent can produce a large diff quickly, but a human still has to read it, decide what to keep, and turn those decisions into a tidy branch. Reviu states the premise directly - agent work only matters when it becomes a clean commit. The app is therefore built around the loop that starts before the commit: the agent works in a durable session, you review the diff, send fixes back from inline comments, then finish with hunk staging, interactive rebase, conflicts, history, and push in the same application. Reviu also positions itself next to existing Git tooling rather than replacing it, inviting users to keep the Git tools they already like and add the missing agent review layer. Reviu manages sessions like real work. Each task becomes a durable session rather than a disposable chat, carrying its own conversation, branch, terminal, checkpoints, file edits, and review queue, and you can switch between sessions without stopping running agents. Parallel worktrees let you run multiple agents at once without letting one task dirty another checkout - the product shows a main checkout alongside separate agent worktrees for tasks such as discount work and tax rounding. Attention states make the status of each session visible, showing what is running, waiting, failed, or ready for review. Readable agent activity keeps commands, reads, edits, permissions, and failures grouped as reviewable events, so an edit of forty-two added and eight removed lines in a source file, or a test command run, shows up as an event you can inspect rather than as an opaque log line. Diff review is the core of the app. You inspect the diff and leave line comments on local changes, including file, line, and side context, then batch those comments and send them back to the agent. The content illustrates this with a review queue on a feature branch where three comments are selected: a request to apply flat discounts before percentage discounts, a fix for discount order, a new rounding test, and a rename for an unclear helper. Once the comments are sent, the agent can act on them directly. Reviews happen against an isolated worktree so parallel agent tasks stay out of your main checkout. Reviu also describes the ability to checkpoint or undo turns, giving turn-level control over what the agent changed. Underneath the review layer is real Git. You shape the diff by staging the hunks you trust, unstaging others for another pass, and restoring the rest. You clean the branch before the pull request exists by squashing, fixup, dropping, and reordering commits. You recover from messy states by resolving conflicts, continuing rebases, stashing work, cherry-picking, and undoing mistakes. Every surface in the app follows the checkout, so changes, history, terminal, and review stay in sync with whatever branch is active. Git actions are reachable from the command palette in the same keyboard-first flow as the rest of the app: commit, amend commit, push, force push with lease, interactive rebase, and pop stash. The result is staged hunks, rewritten history, and a branch you can push with confidence. Reviu Pro adds GitHub. The paid tier is for developers whose local agent work ends in a GitHub pull request review and merge. A pull request dock brings your branch, agent session, working tree, review threads, checks, and merge button into one window, so you can use GitHub without turning every review into a browser tab hunt. An inbox surfaces events such as a requested change, a CI run finishing, or a reply in a file. When checks have passed and the review is approved, the dock shows that the merge is ready and lets you create a merge commit. The PR follows your branch: check out a branch and Reviu finds its pull request, or helps create one from the header. You can review GitHub diffs locally by opening PR files in the editor, commenting inline, replying to threads, and submitting a full review. Merging works like GitHub would, with squash, merge, or rebase using GitHub's generated title, message, bullets, and trailers. A browser extension adds an Open in Reviu button to GitHub pull requests, opening the branch locally ready for diff review, files, and terminal; it is available for Firefox and Chrome. Reviu's approach is local by default. It launches the agent CLI you already installed and signed into, so agents run as local processes on your machine with your existing subscription and no API key to paste. Your code and the agent process stay on your machine; Reviu does not run agents in the cloud and does not meter your agent usage. It drives any agent from the official Agent Client Protocol registry, naming Claude Code, Codex, Gemini, Copilot, Cline, and about twenty others. The app itself is fully native, built with Rust and GPUI, a Rust-based GPU-accelerated UI framework - no Electron and no webview. No account is required for agent sessions or local Git features; signing in is only needed for the GitHub integration in Reviu Pro. For users, the benefit is a single place where agent output becomes a reviewed, clean branch. The review queue turns scattered comments into batched instructions the agent can act on, isolated worktrees keep parallel agent tasks from interfering with each other, and attention states make it obvious which sessions need you now. Because Git stays close to the diff, review decisions become staged hunks, rewritten history, and a pushable branch rather than a manual cleanup exercise after the fact. On Pro, the pull request dock collapses branch, threads, checks, and merge into one window, reducing context switching between the local workflow and GitHub. Concrete workflows described in the content include running several agents in parallel on separate tasks - for example discount work, tax rounding, and cart property tests - each in its own worktree, and switching between those sessions while they continue running. Another is reviewing an agent's diff on a feature branch, leaving line comments with file and side context, and sending a batch back to the agent so it can correct the order of discount calculations or add a rounding test. A third is finishing a branch before any pull request exists: staging trusted hunks, reordering or squashing commits, resolving conflicts, and pushing. Pro workflows include finding a branch's pull request from the header, reviewing and commenting on PR files locally, submitting a review, watching checks and notifications in the inbox, and merging with squash, merge, or rebase. The browser extension supports starting in GitHub and finishing the local review in Reviu. Reviu is aimed at developers who use coding agents on their own machines and want to review that work with real Git tooling. It integrates with agents from the Agent Client Protocol registry, with GitHub on Pro, and with Firefox and Chrome through the Open in Reviu extension. It runs as a native desktop app on macOS for Apple Silicon and Intel, on Windows for ARM64 and x64, and on Linux through a terminal install command. Pricing is straightforward: the local agent review tier is free at $0 and covers agent sessions with ACP registry agents, parallel worktrees and durable session state, diff review with comments sent back to the agent, and local Git including staging, rebase, conflicts, and terminal. Pro is $9 per month or $79 per year, which the site lists as a 27% saving, with a 14-day free trial and cancel anytime; it adds the pull request dock with checks and merge, GitHub review comments and submit review, and inbox notifications and the browser extension. Mobile access and remote over SSH to servers and VPS are listed as planned rather than available today. Reviu occupies the space between an agent writing code and a branch being merged. It keeps the review loop - durable sessions, isolated worktrees, inline comments sent back to the agent - free on the desktop, and adds GitHub pull requests, checks, merge, and notifications as a Pro layer, all built on real Git and a native Rust and GPUI app rather than a webview.
Marv is a small AI companion for Windows that sits alongside your cursor and helps you get things done on your own desktop. It sees your screen, answers out loud when you ask a question, and then shows you the next step by drawing on top of whatever application you are using. The interaction is deliberately simple: you hold a hotkey — the website shows Ctrl + Alt — and ask about anything currently on your screen. Marv replies in speech so you can keep moving, while circles, arrows, highlights and written notes appear on screen to point the way. The website describes Marv as 'your cursor's new plus-one', a little companion for everyday desktop work, and early access is being offered for Windows through a waitlist. The friction Marv addresses is the interruption that comes with needing help. When you get stuck — on a formula, a line of code, or a control you cannot find — the usual move is to leave the thing you are working in, open a browser, search, read, and then try to translate what you found back into the app in front of you. Marv is built to remove that round trip. The Product Hunt listing says it lets you debug some code, work out a spreadsheet formula or find the right control in your video editor 'all without leaving the app you're using'. The website captures the same idea with the line 'One task, all the way through', illustrating it with a spreadsheet question that carries from the formula through to the next app. Instead of answering a single question and stopping, Marv is presented as a companion that stays with you as the task progresses. Marv's first capability is voice conversation tied to a hotkey. The website lays out three steps, and the first is 'Ask out loud. Hold your hotkey to talk.' The example prompt shown is a simple one — 'Where do I start?' — which reflects the kind of open question Marv is meant to handle. The second step is 'Get a clear answer. Marv speaks, so you can keep moving.' That detail matters: because the answer is spoken, your eyes and hands stay on the task, and you are not pulled into a chat window to read a wall of text. Underneath the interface the website shows Marv in a few states — listening, smiling and pointing — so you can tell at a glance whether it is hearing you, responding, or directing you. The third step is 'Follow Marv's lead. Circles, arrows and highlights show the way.' This is the feature that separates Marv from a plain voice assistant: rather than describing where something is, it marks it on your actual screen, so the instruction and the thing you need to click are in the same place. The Product Hunt description adds that Marv draws arrows, circles buttons and writes notes directly on your screen while it walks you through a task. Written notes are useful for anything that does not map neatly to a single click — a sequence of steps, a formula to type, or a list of things to do. The website's hero illustration shows exactly this spirit, with Marv peeking over the edge of a cream mouse pointer, holding on with both hands. Because Marv answers questions about what is on your screen, it has to be able to see your screen, and the website treats that access as something visible and controllable. A section headed 'Helpful when you need it. Quiet when you don't.' includes a 'Screen access' control shown in a paused state. In practical terms, that means Marv's view of your desktop is a state you can switch rather than something running invisibly. The site also publishes Terms and a Privacy Policy, which are referenced when you join the early-access waitlist with your email address. Together these details describe a companion that is present when you call on it and out of the way when you do not. Marv's approach is a loop rather than a one-off query. You hold the hotkey and speak; Marv listens, looks at the screen you are on, and responds with spoken guidance; then it draws its answer onto the same screen so you can act on it immediately. The website frames this as a 'conversation, on your desktop', and the demo on the page is captioned as taking a spreadsheet question 'from the formula to the next app' — a description of one task carried through end to end. Everything happens on top of the application you already have open, which is the core of the design: no separate window to manage, no switching, and no moving information from one place to another. The practical benefit is continuity. Spoken answers keep your hands on the keyboard and your attention on the screen, and on-screen marks remove the translation step between reading an instruction and finding the thing it refers to. The website's phrasing for this is 'so you can keep moving'. For someone who is momentarily stuck, that means the interruption lasts as long as the question rather than the length of a search. The other stated benefit is quietness: Marv is described as helpful when you need it and quiet when you don't, with screen access able to be paused. The examples given for Marv are concrete desktop tasks. Debugging code is named in the Product Hunt description, where Marv can point at what matters inside your editor instead of you pasting code elsewhere. Working out a spreadsheet formula is a second example, and the website's demo shows a spreadsheet question being carried through to the next app. Finding the right control in a video editor is a third, which plays to Marv's on-screen arrows and circles — pointing out a specific control in a dense interface is far quicker than describing its location in words. The website also illustrates a simpler everyday case with a Notepad file titled 'Weekend plan' containing tasks to book a train and pack a bag, alongside the prompt 'Where do I start?' — an example of Marv helping someone begin rather than solve something technical. Marv is built for Windows, and the site states that early access is for Windows, with a waitlist you join by entering an email address. That places the current audience at desktop users rather than mobile users: developers, spreadsheet users, video editors, and anyone working in software where a second window would break concentration. Beyond Windows, the website does not detail additional platforms, integrations or a technology stack. Pricing is not stated on the page either; the only current call to action is to join the waitlist, and the site notes that joining is subject to the Terms and Privacy Policy. Marv's promise is narrow and clear: a small companion that sees your screen, answers out loud, and draws the next step directly onto the app you are using. By keeping help inside the window you are already working in — and keeping screen access under your control — it turns a moment of being stuck into a spoken question and a marked-up answer, so you can carry one task all the way through without leaving what you were doing.
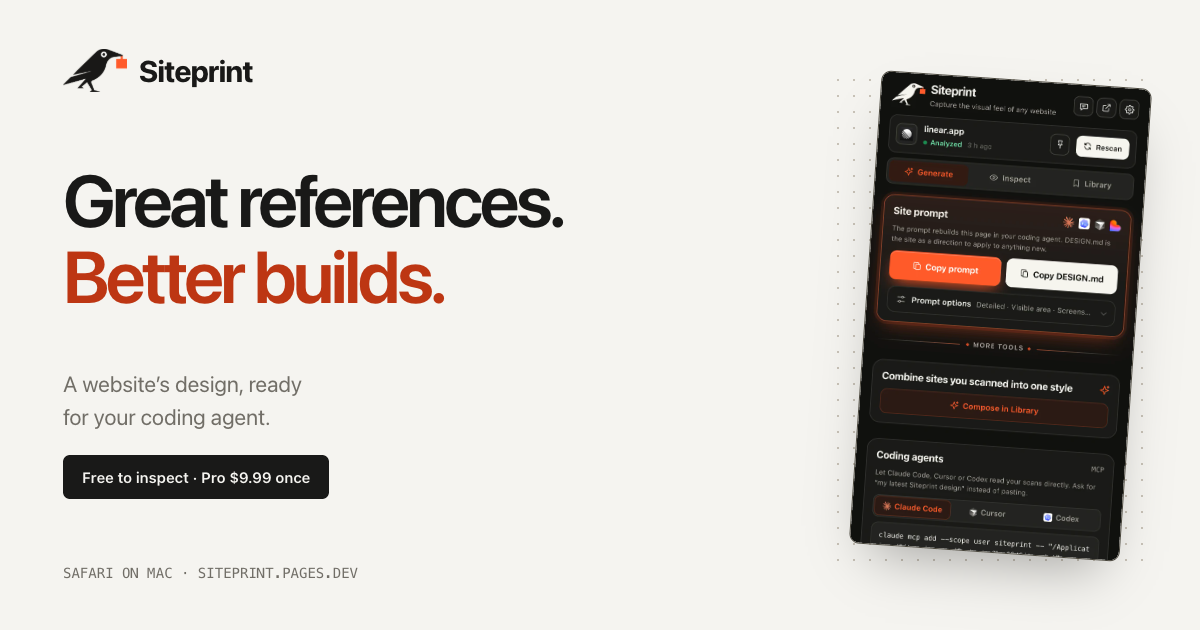
Siteprint is a Safari extension for Mac that measures the design of any website and turns what it finds into one exact prompt for a coding agent. Open a page in Safari, click the crow in the toolbar, and Siteprint reads the page's colors together with their roles, its type scale, spacing, corners and layout. From that measurement it produces a single prompt that can be pasted into Claude Code, Codex, Cursor, Lovable or any other AI tool, which then builds a new page from those values. It is made for designers, developers and founders who find a design they love and want their AI to work from measured values rather than guesswork. The extension runs on your Mac, with no account, no tracking and no uploads. The problem Siteprint addresses is that design inspiration is trapped in the browser. You find a site whose colors, type and spacing feel right, but the usual way to pass that look to an AI coding agent is to describe it in words. Words do not carry hex codes, font sizes or spacing scales, so the agent improvises: colors that are close but not the same, type at the wrong scale, layout that drifts away from the reference. Siteprint replaces that guesswork with measurement taken directly from the page. Instead of describing a design in vague terms, you hand your agent the values the page actually uses. Siteprint frames this as real values, not vibes, and that framing is the core of the product's purpose. The free Inspect view is where the measurement becomes visible. It shows the palette of the page with each color's role, the font families and the typography in use, and a blueprint of every section on the page. Alongside that, Siteprint includes an eyedropper and a grid overlay so you can check individual colors, spacing and alignment directly in Safari. Inspect, token export and the Library are available without paying, which means you can measure any site and study its design system before deciding whether you need the rest of the workflow. Generate is the Pro step that turns a scan into something your coding agent can use. It copies one prompt containing the exact values Siteprint measured, and it can also copy a DESIGN.md file. Themes are part of Pro as well. The published example DESIGN.md shows what the output looks like: a design direction section with canvas, surface, text and muted colors as hex values, a type section listing a display size at a specific weight and a body size at a specific weight, and a shape section listing corner radii. That file is the same kind of artefact you would normally assemble by hand from a browser inspector, and Siteprint produces it from a single click on the page. Compose is the second Pro capability and it is the one that goes beyond copying a single reference. Compose mixes two saved sites into a new style, so a palette from one design can be combined with the typography and layout of another. The product's own illustration of this is mixing Stripe's colors with Linear's type and layout. Because both sites have already been scanned and stored in your Library, the values are exact on both sides of the mix rather than approximated. This gives you a way to build a hybrid design direction that no single reference site could provide, while still keeping every value grounded in a real, measured page. For teams that work with coding agents, Pro also lets your AI read your scans directly. In the extension you open Generate, then Coding agents, and follow the setup for Claude Code, Cursor or Codex. On Macs that have Apple Intelligence, Siteprint additionally reviews each scan and answers your questions about the design, for example how to match a particular site's look. Apple Intelligence is optional: Siteprint states that everything works without it, and it is simply an extra layer of review and question answering on machines that support it. Siteprint itself does not build the site; it measures the design, and your coding agent builds from the prompt. The overall workflow is deliberately short. Siteprint describes it as three clicks: open any site, click the crow, and paste into your AI. Getting set up takes about a minute: get the extension from the Mac App Store, turn it on in Safari Settings, and click the crow on any site. Everything happens locally on your Mac, which is why the product can promise no account, no tracking and no uploads. There is nothing to sign up for and nothing leaving your machine, which matters when the pages you are measuring are client work, unreleased designs or internal tools. The benefit for users is that a design reference stops being an inspiration image and becomes a set of exact values an agent can act on. You no longer eyeball a hex code, guess a type scale or describe spacing in words, and you no longer accept output that is merely close to the reference. Because the prompt is generated from measurement, the design direction you hand to Claude Code, Codex, Cursor, Lovable or any other AI is consistent and repeatable. And because the pricing model is buy once rather than a subscription, the tool is a one-time purchase that keeps working. Concrete scenarios follow directly from the workflow. You might see a site whose palette you like and scan it to get the exact colors with their roles, then ask your agent to build a completely different product page using that palette. You might scan Linear and ask your coding agent to build a pricing page in that design direction, using the copied prompt or the DESIGN.md file. You might use Compose to mix Stripe's colors with Linear's typography and layout for a hybrid style. You might export tokens to carry a measured design into your own system, or open the blueprint in Inspect to study how a page structures its sections, spacing and corners before writing anything. On a Mac with Apple Intelligence you can also ask the design questions and get answers grounded in the scan. Siteprint is a Safari extension for Mac and requires macOS 14 or later. It is not available for Chrome or iPhone yet. It is aimed at designers, developers and founders, and specifically at anyone who uses an AI coding agent such as Claude Code, Codex, Cursor or Lovable, or any other AI that can take a prompt. The free tier covers colors, type and layout measurement, the eyedropper and grid overlay, token export and your Library. Pro costs $9.99 as a one-time purchase and adds one exact prompt, DESIGN.md and themes, mixing two sites with Compose, and agent access so your AI can read your scans. Support and the setup guide are available through the site, and feedback goes to the product's support email address. The takeaway is that Siteprint turns a design you admire into precise, measured instructions your AI can build from. By measuring colors with their roles, type scale, spacing, corners and layout inside Safari and packaging them into one exact prompt, it removes the guesswork that normally sits between a reference site and a new build. Free to inspect, $9.99 once for the full prompt workflow, no account and no uploads: Siteprint gives your coding agent real values instead of vibes.
devpit is a native desktop application for controlling your coding agents from a single window. It brings together a terminal per project, a board for the work, the cost of every call and an orchestrator that spans projects. It is built for developers who run coding agents such as Claude Code and want their sessions, tasks and spend in one place rather than spread across tabs and applications. devpit runs on Linux, macOS and Windows, is free and open source under Apache 2.0, and runs locally on your own machine using the Claude Code plan you already have. Most agent work happens in fragments. A terminal lives in one window, the task list lives somewhere else, and the cost of the calls is invisible until later. devpit's answer is one window with everything the work needs inside it, with panes side by side rather than tabs split across six applications. Its stated goal is that several agents can run at once and none of them get lost: sessions stay visible, the ones waiting on you surface first, and nothing advances without your knowledge. Because the app is local-first and writes nothing into your repository, it can be adopted without changing how a team works. The centerpiece is an orchestrator that works across projects. It is a chat that reads every board you link, so you can hand it a card and it starts a session, then reports back to you. A Sessions panel keeps track of every session of your account and puts the ones waiting on you first, letting you answer them in place, as yourself. Above your windows sits a capsule called the island, which shows what each agent is doing and lets you allow or deny from there. The island distinguishes states such as thinking (started, before its first step), working, asking, waiting, done, failed and sleeping. There are also reminders that only remind: you can ask devpit to remind you at three to review the PR, and it will tell you then without starting anything. Everything the work needs lives in panes side by side. The Chat pane shows a turn at a time, along with what each one cost. The Terminal pane is a real pty behind tmux, so it can be split, the window can be closed, and the process is still found running when you return. The Board pane shows your columns in your order, and moving a card starts the work. Capabilities are optional extras per project, Notes and Excalidraw today, opened as panes. There is also a view for files, diffs and a browser, so you can review what an agent changed and the page it serves without leaving the app. devpit drives the agent you already use: Claude Code today, with more behind the same interface, and your own agents are defined as markdown files. Each project gets its own workspace. The board, the panes, the terminal and the costs live in ~/.devpit, so nothing lands in your repository. There is nothing to gitignore and nothing appears in the diff, and a teammate can work with you without ever hearing about devpit. Every project has one target terminal; switching between lines of work switches what is attached, while the previous session keeps running. Sessions outlive the window: you can close devpit, reopen it, and what was running still is, because tmux holds the processes. A worktree is created per line of work when a step needs a checkout, and it is never removed while it holds uncommitted work. A spending cap sits on every call: the column sets the ceiling and the card gets the real cost. The board is deliberately conservative. Nothing advances on its own. A step writes down its output, its exit code and its real cost, then stops; moving on is your call, unless you have set a lane to move, which the board shows. The orchestrator has clear limits: it never moves a card into a lane that runs a step, never acts on a timer, and never approves anything in another session. Replies it drafts go out only when you send them. Under the interface, devpit is Rust and Tauri rather than an Electron app, and each terminal is a real pty behind tmux, or psmux on Windows. Agent status is reported through a devpit-agent hook for other agents, while Gemini CLI reports status with nothing to set up, and Claude Code works through the claude CLI you already have. The outcome for users is visibility and control. Sessions that would otherwise be forgotten stay listed, with the ones waiting on you at the top. Cost is attached to individual calls rather than discovered later. Work survives closing the window, so an agent can be left running and picked up again. Worktrees mean parallel lines of work do not collide, and they are protected while they hold uncommitted changes. Because everything is local-first and nothing is written into the repository, you can start using devpit without asking a team to change its process. And because it uses your existing Claude Code plan, there are no new API keys to manage. Typical workflows include running several projects at once and switching between them without losing the thread, since each project keeps its own board, panes, terminal and costs. A developer might hand a card to the orchestrator, let it start a session, and wait for it to report back. When an agent asks a question, it appears in the Sessions panel under waiting on you, and it can be answered in place. Someone working on a flaky test can watch the session in the island and allow or deny actions from there. A user can review an agent's diff and the page it serves inside devpit rather than switching tools. And a reminder such as reminding you at three to review the PR is used when the user wants a nudge and no agent activity at all. devpit is aimed at developers who already run coding agents, particularly Claude Code users who want one place to watch and steer them. It integrates with Claude Code through the claude CLI, supports status reporting from other agents through the devpit-agent hook, and works with Gemini CLI with nothing to set up; Codex, Cursor and opencode support is stated as coming. The stack is Rust and Tauri, with a real pty per terminal behind tmux (psmux on Windows). Installation is a shell command on Linux and macOS and a per-user installer on Windows, and the Linux build also runs in WSL 2. It is free and open source under Apache 2.0 and needs no account; an account today only signs you in. Access from a phone is possible over Tailscale by pairing a device with a one-time code and choosing what it may do. In short, devpit is a local-first, open-source control room where multiple coding agents run side by side, every session stays visible, every call carries its real cost, and nothing advances without your say-so.
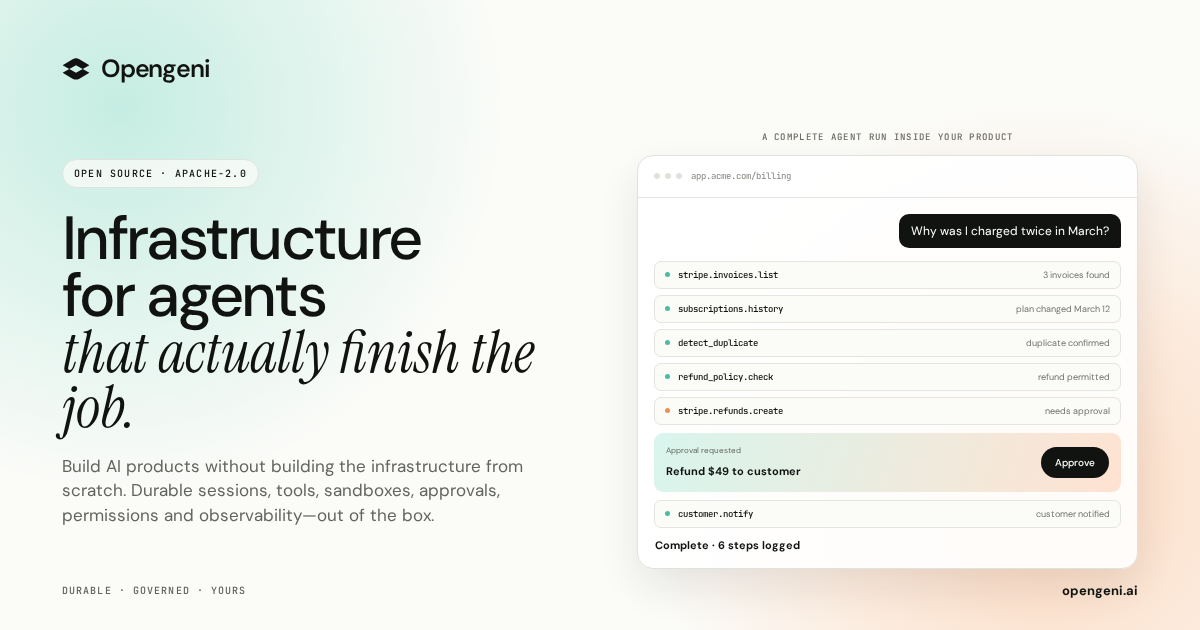
Opengeni is open-source AI infrastructure for putting agents inside your product, built so that you focus on your agents while Opengeni handles the infrastructure around them. It packages the pieces agents need to run in production: streaming, durable sessions, isolated sandboxes, tools, credentials, memory, multi-tenancy and React components. The project is licensed Apache-2.0 and, as the site states, it is built from running agents in production. The same API powers the Opengeni app, your product and your code, so a session can be rendered in the hosted app, embedded in your own interface, or driven programmatically. It is aimed at developers and teams who want to ship an agent feature rather than rebuild chat, sandboxing, credential and tenancy plumbing from scratch. The problem Opengeni addresses is the gap between an agent demo and an agent feature that survives real usage. The site lists the obstacles plainly: one dropped connection and the run is gone; agent code cannot run next to your secrets; every user needs their own OAuth tokens; every API needs wiring before an agent can use it; agents forget everything between sessions; every query has to know who is asking; and a better model ships, leaving you locked in. Each of these is framed as infrastructure you would otherwise have to build and operate yourself. Because the project comes from running agents in production, the emphasis is on the operational realities of restarts, failure recovery, per-user permissions and multiple paying customers rather than on an abstract architecture diagram. Durable sessions are the first thing Opengeni removes from your to-do list. Instead of a run dying when a worker restarts or a user closes a tab, the run keeps going and resumes at the event where it stopped; the site illustrates this with a run resuming at event 128. Sandboxes give the agent code somewhere isolated to execute, shown as a Python script that detects a duplicate charge using a scoped, short-lived token, so agent-generated code never sits next to your secrets. Credentials are handled per user, with connections to services such as Stripe, GitHub and Google Drive, and tokens that are refreshed automatically rather than pasted into prompts. Together, these three pieces mean an agent can be interrupted and still finish, can run code safely, and can act on behalf of one specific person without leaking long-lived secrets. Tools and MCP are how Opengeni connects agents to real systems. You point it at a specification such as billing.openapi.yaml and it exposes operations like invoices.list, refunds.create and customers.get as tools the agent can call; the site presents this as installing three tools from one file. That removes the manual wiring every API would otherwise need before an agent can use it. Memory is out of the box: agents learn from past sessions, so preferences such as refunds going to the original card, invoices being sent by email, or billing in EUR from April are retained, and the illustration labels memory entries with scopes such as Workspace and User. Memory removes the need to re-explain context in every conversation and lets an agent improve as it is used. Multi-tenancy is built in with row-level security, so every query knows who is asking; the illustration lists separate customers such as Acme, Globex and Initech. This means one deployment can safely serve many customers, which matters when you embed an agent for each of your own accounts. Opengeni is also model-agnostic: you can run agents on OpenAI, Azure OpenAI, OpenRouter or your own OpenAI-compatible endpoint, and swap between them so a better model shipping does not lock you in. Alongside these, the Product Hunt description highlights sessions that recover from failures, isolated sandboxes, 100+ integrations, human approvals, and visibility into every step and dollar spent. Opengeni is designed as a single API with multiple surfaces. The same session the Opengeni app renders at app.opengeni.ai can appear inside your own product or be driven from code. The code surface uses the @opengeni/sdk and @opengeni/react packages, with a provider, a session conversation component and a compiled stylesheet. The documented pattern is that your backend holds the API key and proxies the session routes, so the key never reaches the browser. Streaming, tool steps and the composer ship with the component, and these are the same packages the Opengeni app is itself built on, which keeps the embedded experience consistent with the hosted one. The React components are meant to be restyled in seconds. A single CSS custom property recolors every surface, and further variables control corners and typography, with accent options such as teal, violet, orange, blue, pink and graphite, corner styles ranging from sharp to soft to round, fonts such as DM Sans, Archivo and Mono, and a light or dark theme flipped by one attribute. A theme is applied with a wrapper class and a data attribute, so the agent adopts your existing design system instead of looking like a bolted-on widget. The site also includes an integration guide for embedding the assistant in your product and for keeping the key on your backend. Deployment is a choice between speed and control, and both options run the same Opengeni. Opengeni cloud is the fastest start: sign in and go, and you pay model cost plus 5%. Alternatively you can self-host the Helm chart on any Kubernetes, with Terraform for AWS, Azure and GCP, cloning the project from the Cloudgeni-ai/opengeni repository. Both paths share the same Opengeni API, workers and web app, so moving between them does not mean rewriting your integration. For the Product Hunt launch, the first 100 users receive $100 in cloud credit with the promo code PRODUCTHUNT100. The benefit is time to a working agent feature rather than a working demo. Sessions that survive failures mean users do not lose work when infrastructure hiccups; per-user credentials mean an agent can act with the right permissions for the right person; sandboxes mean agent code is contained; memory means the agent carries context forward; and multi-tenancy means the same deployment can serve many customers safely. Because streaming, tool steps and the composer come with the React component, the visible product experience is a few lines of code instead of a custom chat stack. The result is that engineering effort goes into the agent's behaviour and domain logic rather than into session durability, tool wiring and credential storage. The site's concrete example is a billing assistant. A customer asks why they were charged twice in March; the agent lists invoices, finds a duplicate, and issues a refund, then explains that two $49 charges landed on March 12 and that the refund will be back on the card in a few days. The same scenario is shown running in the Opengeni app, inside a customer's billing portal, and from React code. Other sessions listed in the app include a weekly churn summary, updating a refund policy document, and triaging failed webhooks, showing the same infrastructure applied to recurring analysis, internal document work and operational triage. Opengeni targets developers and engineering teams building AI agents into real products, and the Product Hunt topics are Open Source, Developer Tools, Artificial Intelligence and GitHub. The stack shown in the content is React and TypeScript on the client with CSS variables for theming, a backend that holds API keys, and Kubernetes, Helm, Terraform, AWS, Azure and GCP for self-hosting. Integrations named in the content include Stripe, GitHub and Google Drive, with other capabilities exposed as tools from OpenAPI specifications such as billing.openapi.yaml. Opengeni's promise is straightforward: agents in your product, infrastructure out of the box. By providing durable sessions, isolated sandboxes, credential handling, tool and MCP wiring, memory, multi-tenancy, model freedom and themable React components as one open-source, Apache-2.0 package that runs in the cloud or in yours, it shortens the distance between an agent idea and an agent feature your customers can actually use.