Category Focus/categories/api
API AI Tools
Discover and compare the best api AI tools and software. Browse 119+ curated tools with reviews and rankings.
Projects tracked
119
Sort mode
RECENT
Page
1
Discover and compare the best api AI tools and software. Browse 119+ curated tools with reviews and rankings.
Projects tracked
119
Sort mode
RECENT
Page
1
Okapi is a free GitHub App that watches the third-party APIs your app and AI agents call and opens a pull request with the fix before a breaking change hits. It is built for developers whose applications and agents depend on external APIs, where a single changed field, renamed parameter, or retired endpoint can take a production app down. Okapi describes itself as Dependabot for APIs: instead of waiting for a deprecation email or manually reading changelogs, you connect a GitHub repository and Okapi keeps your code up to date with every API it calls. The goal is simple — your app keeps working and your team stops chasing changelogs. APIs change all the time, and keeping up with every API's changelog is a hassle. Deprecation emails get lost, nobody has time set aside for the work, and no one owns it. Still, a small field change in an API response can take your whole app down — as Okapi puts it, a tiny update can bring down a big app. The problem is not that providers fail to announce changes; it is that the announcements arrive in many different places and formats, and the people responsible for a repository are busy building. Okapi exists to close that gap by watching for changes continuously so developers can focus on building rather than on maintaining connectors and reading release notes. Getting started takes one click. You connect your GitHub repository through the Okapi GitHub App, and Okapi then finds the APIs your app depends on by reading your code. It looks for the API calls the repository makes, from the big names to the niche ones that break more often, and keeps track of their changes. Installation is described as "1 click, then forget it," and the product is 100% free. Because discovery is based on the code you already have, there is no configuration list to maintain by hand and no inventory of providers to assemble: Okapi finds them in your repo for you and begins watching them. Okapi monitors each API call individually and suggests a fix before it breaks. Today it reads 1,173 API providers' own pages and tracks 841 upcoming breaking changes, according to the website. That coverage matters because deprecations and breaking changes are usually published by each provider on its own pages, in its own format, on its own schedule. By reading those pages directly, Okapi can surface an upcoming change — such as a field that will handle null values differently from a given date — and connect it back to the specific places in your code that use the affected call. The result is a continuous watch over the APIs your app depends on rather than a one-time audit. When an API call is deprecated or about to break, Okapi opens a pull request with the fix before it fails. The pull request is not a generic warning: it contains the actual change your code needs. In the Stripe example shown on the site, okapi[bot] opens a pull request titled "Update Stripe API for upcoming customer.address change", wants to merge one commit from a branch named okapi/stripe-customer-address into main, and explains in a comment that Stripe is changing how customer.address handles null values on October 15. The comment lists the effective date, the API, and the number of affected files (two), and the diff updates both files to handle the new response format. The pull request also carries release notes and a "what changed" section plus api-changes and stripe labels, so a reviewer can understand the change without hunting for context. Okapi works with any API, not only a fixed set of well-known providers. The site's examples span many languages and services: an OpenAI call updated from max_tokens to max_completion_tokens; a PubMed query changed from sort "date" to "pub_date"; a verification request that gains a verify_profile_id field; a notification URL moved to a new push endpoint; an ip-api lookup switched from HTTPS to HTTP; a Figshare download moved to the v2 API; a Mojang profile path corrected; and a Gemini configuration changed from a thinking budget to a thinking level. Each diff is small — often one or two lines — which is exactly the point: the changes that break production are frequently tiny, and they are easy to miss when nobody is watching every provider's changelog. Okapi's approach mirrors dependency automation, which is why it calls itself Dependabot for APIs. Rather than pushing commits directly, it opens a pull request for every change so a human reviews and merges it. The site states that Okapi never commits to your branches: every change comes as a pull request you review. If you do not merge the pull request, nothing changes in your code; the pull request stays open until you merge or close it. That design keeps developers in control while still removing the detective work of finding the change and the mechanical work of applying it. The stated benefits are straightforward: no more time spent maintaining connectors, and improved reliability over time. Instead of learning about a breaking change from a production incident, teams see a pull request with a fix and an explanation before the effective date. Deprecation emails that get lost no longer matter as much, because the watch is continuous and attached to the code that makes the call. Because the fix arrives as a reviewable pull request, teams can adopt it on their own schedule, inspect the reasoning, and keep their normal code review process intact. Concrete scenarios follow directly from the site's examples. A billing service that reads customer.address from Stripe can receive a pull request ahead of the October 15 null-handling change. An application calling OpenAI can be moved from max_tokens to max_completion_tokens. A literature search tool using PubMed can have its sort parameter corrected. A service calling a geolocation or media API can have a changed URL or protocol updated. Teams running AI agents that call external services can keep those agents working as providers evolve. And teams depending on niche APIs that break more often get the same monitoring as those using the largest providers. Okapi is aimed at developers whose apps and AI agents depend on third-party APIs, and at teams that do not have anyone specifically assigned to tracking provider changelogs. The access required is limited: Okapi reads your code to find the API calls it should watch, and it never commits to your branches. Removal is equally simple — uninstall the Okapi app from your GitHub settings and it stops right away. The product is 100% free, installs in one click, and works with any API, so there is no pricing tier or provider list to evaluate before trying it. In short, Okapi brings dependency-style automation to the APIs your code calls. It discovers the APIs in your repository, watches their providers for deprecations and breaking changes, and opens a pull request with the fix before the change can break your app — free, with one-click install, and with every change left for you to review.
FounderMail is email for founders who ship on Cloudflare. One click puts a Worker in your own Cloudflare account, and your domain has mail — real addresses on your own domain, for you, your team and your agents. You sign up, bring your Cloudflare account and your domains, and FounderMail does the rest: a small proxy sits in your Cloudflare account, mail comes in through it, and your replies go out the same way. Cloudflare sends and receives on your account, while FounderMail runs the mailbox behind it. The inbox lives at inbox.foundermail.app and holds every mailbox you hold in one list, personal and shared side by side, with each thread labelled by the mailbox it came to. The product is built for founders and small teams already running domains on Cloudflare who want real email without paying per seat and without forwarding to Gmail. The launch description frames FounderMail against two familiar alternatives: paying per seat for hosted email, and forwarding a domain's mail to Gmail. It also addresses a newer requirement — AI agents that need to work with mail. As the description states, you, your team and your AI agents work from the same inbox, and agents get their own access instead of your password. The site summarises the promise as "Cloudflare email without the setup or the maintenance," meaning the DNS records, the relay and the mailbox are handled for you rather than assembled by hand. FounderMail also draws a hard line: it will not install on a domain that already receives mail somewhere else. It checks, and it stops, because taking over that domain's MX records would end the existing mail. That makes the product suited to domains that are new to email or are being moved deliberately. The inbox itself is organised around a single unified view. All inboxes — every mailbox you hold — appear in one list, with personal and shared addresses side by side rather than scattered across separate accounts. Each thread is labelled with the mailbox it came to, so you can tell at a glance whether a message arrived at Ada, Team or Billing. The interface is keyboard first: j and k move between items, e archives, and ⌘K reaches everything else. The mobile inbox view shows thirteen conversations from one user's three mailboxes in one list, each tagged with its destination mailbox, which illustrates how the unified list works in practice. FounderMail is explicitly built for agents. It offers a REST API, OAuth and two MCP servers: one for mail and one for the control plane. A token issued for one is refused by the other, so access to mail does not silently become access to administration. Agent seats let you give an agent a seat on any inbox, and reading and sending are separate scopes — read-only means read-only. The site answers the question "Can an agent send as me?" directly: only if you let it. An agent given read access to a mailbox can read it and cannot send from it; give it send, and it sends from that mailbox's addresses. Agents can also be pointed at the published llms.txt at https://foundermail.app/llms.txt to discover how the service works. Shared addresses and multi-domain setups are first-class. Every address — hello@, sales@, support@ — can be held by as many people and agents as you like, so a support inbox can belong to an invited teammate and a read-only triage agent at the same time. One relay per Cloudflare account covers every domain on that account, and you can bring as many accounts as you have. Mail leaves from your domain with your own DKIM, SPF and DMARC records, so your domain's sending reputation is built on your own records rather than someone else's. The setup is described in three numbered steps. First, sign up: 14 days free, no card, so you can make an account and look around before connecting anything. Second, bring your Cloudflare account and domains, and FounderMail does the rest — the proxy in your Cloudflare account handles inbound and outbound, Cloudflare sends and receives on your account, and FounderMail runs the mailbox. Third, assign inboxes to as many people or agents as you like, each with addresses on your own domain. The requirements are explicit: your domain's DNS must be active on Cloudflare, on an account with the Workers Paid plan, because sending from your account needs it. The install proves that before it touches your domain's mail. Ownership is split in a way the site spells out. Yours: your Cloudflare account, the DNS records (MX, DKIM, SPF), the relay that sends and receives, your domain and every address on it, and your domain's sending reputation. Ours: the mailbox, stored on FounderMail's infrastructure. If you leave, you can take a copy first — every mailbox as an mbox file, from Settings → Your data in the console. If your subscription ends, FounderMail keeps your mail so you can come back or take it out, and gives you at least 30 days' notice before deleting it. The site also warns that disconnecting does not put your MX records back, so you should turn off Email Routing and publish your new records first before moving to another provider. Concrete workflows follow from the address model shown on the site. A founder can hold a personal inbox such as matthew@yourdomain.com as owner, while support@yourdomain.com is held by a teammate invited by email and simultaneously by a triage agent with a seat and read-only access. Billing addresses can be shared between an owner and another invited person. Because unlimited people, agents, mailboxes, addresses and domains are included on both plans, the same pattern scales from a single founder to a team running several domains across several Cloudflare accounts, all reachable from one inbox list. Agents that need to act on incoming mail can be granted read scope without send scope, which keeps automated triage separated from the ability to reply as the domain. On pricing, both plans start with 14 days free and no card. Founder is $20 a month with 20 GB of mail; Team is $200 a month with 200 GB of mail. People, agents, mailboxes, addresses and domains are unlimited on both. Storage is a fair-use allowance measured as the 30-day average of each day's peak; each email counts at least 10 KB, a message delivered to several mailboxes counts in each, and the Trash counts until it is emptied. FounderMail emails you at 80% and 100%, and states that your mail never stops because of it. One mailbox holds about 10 GB, and the console tells you when one is filling so you can add another. There is no service level agreement; the service is provided as it is. On data handling, FounderMail commits to processing your mail only on your instructions, keeping it confidential and secure, using only the providers its privacy notice names and telling you before adding one, notifying you without undue delay if a breach affects your mail, and deleting it when you do. FounderMail's primary value proposition is ownership without administration: real mail on the Cloudflare domains you already run, with your own DNS records and sending reputation, one inbox for every mailbox you hold, and first-class seats for AI agents whose read and send permissions are kept separate. For founders already on Cloudflare, it turns an awkward email decision into a single install.
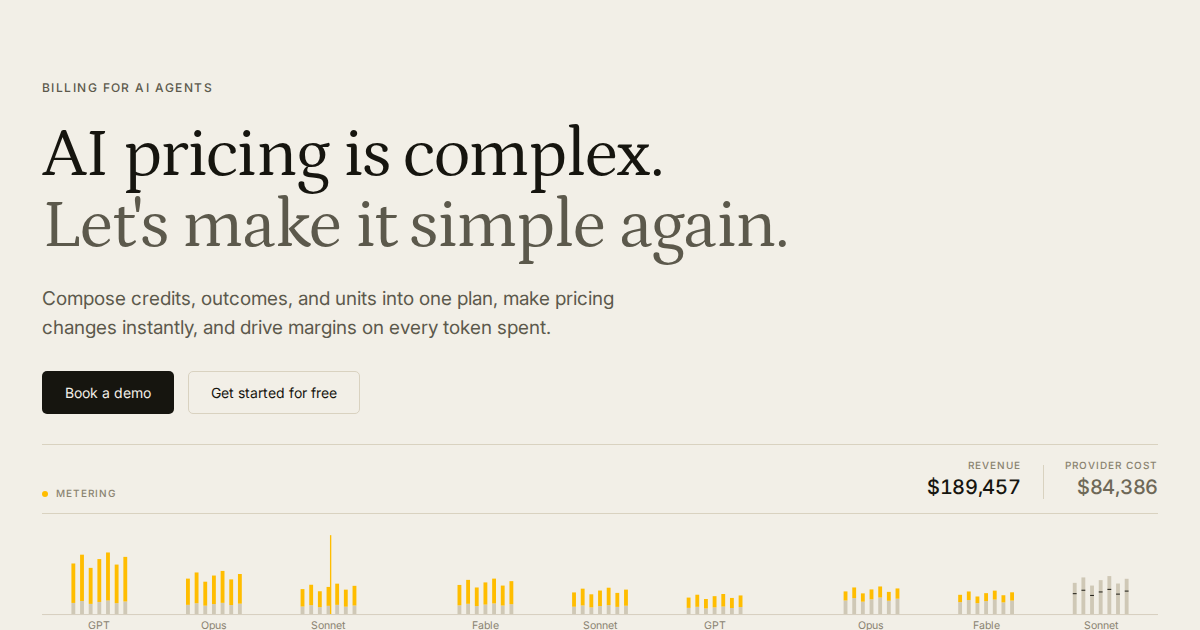
Clocknext is monetization and billing infrastructure built specifically for AI agents and AI-native applications. It lets teams track AI usage from their product in real time, turn that usage into billable metrics with flexible pricing plans, and monitor costs, margins, and profitability at every level. The platform is aimed at AI founders along with revenue and engineering teams who need to convert tokens, completed outcomes, and countable units into revenue. Its stated goal is to make AI billing simple again: every AI interaction has to be metered, priced, and billed, and Clocknext supplies the infrastructure for that so teams do not have to assemble it themselves. The problem Clocknext addresses is the gap between counting usage and earning from it. As the company puts it, every token is easy to count, but turning it into revenue isn't. Without the right infrastructure, teams risk losing revenue, momentum, and peace of mind. Cost visibility is a large part of that risk: a model switch made in June should not surface as a surprise in September, which is why Clocknext tracks cost as it happens, against the signal that caused it. Engineering dependency is the other friction point — metering pipelines, wallet logic, and invoicing all have to be built and maintained unless a platform owns them, and pricing changes routinely get queued behind engineering work. Clocknext is designed so that pricing moves at the speed of the business rather than the deployment calendar. Pricing is assembled from primitives that can be mixed and changed without touching the code that reports usage. Credits are a token-denominated allowance drawn from a wallet as agents work. Outcomes price the completed result rather than the compute behind it. Units cover seats, repos, integrations, and anything countable. Composites combine primitives for multi-action agents and bill them as one line. In the product's own example, 100,000 credits at $0.008 come to $800.00, 47 outcomes at $12.00 come to $564.00, 12 seats at $29.00 come to $348.00, and a voice agent composite spanning four meters comes to $410.00 — all of it landing on one plan and one invoice totaling $2,122.00. Teams start with one primitive, add the rest when needed, and change the mix freely. Payment methods are equally configurable, supporting prepaid, postpaid, hybrid, and top-ups. With prepaid, customers fund a wallet before they use anything and usage draws it down in real time, so there is no chasing payment after the work is done. Hybrid combines a commitment upfront that covers expected volume with anything beyond it billed after, with both landing on the same invoice under one plan. Postpaid meters through the month and settles once at the end, fitting the purchase order and procurement cycle enterprise buyers already run. Top-ups let customers buy more credits or outcomes on their own whenever they need them, with the balance landing in their wallet straight away. Margin control sits alongside billing. Clocknext bridges the gap between provider cost and usage with margins that keep a product's bottom line healthy in real time, showing revenue against provider cost with margin as the visible band between them. A customer view surfaces cash balance, credit allowance, units consumed, revenue, provider cost, gross margin, and month-over-month movement, alongside a monthly table of revenue, provider cost, margin, and gross margin. Because margin is tracked by account, by agent, and by model, an account that falls below target is flagged — for example, a customer showing 8.2% margin against peers at 74.9% and 66.9% — and can be repriced immediately. Changes to the plan, the rate, or the credit conversion take effect on save, with no engineering involvement. Operationally, the product is built around usage signals rather than a bespoke metering pipeline. Setup runs in three steps: install the SDK, send a usage signal, and map signals to pricing. From there, pricing packages are built by mixing credits, outcomes, and units and bundling them into composites when a product needs its own price, then published to all customers live with no deploy. Engineering teams get a drop-in usage SDK and API so there is no metering pipeline to own, while wallets and invoicing are built in. Product teams can run no-code pricing experiments, ship new plans in hours, and A/B test monetization without an engineering dependency. The stated outcomes are speed and financial clarity. Clocknext reports a time to live of two days from signup to the first invoice out the door, eight hours of billing operations saved every week on reconciliation and invoicing, and a 90% increase in gross margin after pricing moved onto the platform. Teams can catch losses immediately because cost is attributed to the signal that caused it, and they can reprice without a deploy whenever a rate or conversion no longer works. For revenue teams, the value is per-agent margin analytics, self-serve credit top-ups, and revenue and provider cost in a single view, so pricing decisions can be made against profit rather than top-line numbers alone. Concrete workflows follow from those building blocks. A team launches a product with a hybrid plan, covering expected volume with a commitment and billing overage after. A voice agent with several billable actions is modeled as a composite of four meters and billed as one line item. A revenue team notices an account whose gross margin has slipped below target and reprices that offering, with the change going live on save. Customers top up credits on their own instead of waiting on an account manager. An enterprise buyer procures on postpaid terms through a purchase order while prepaid customers fund a wallet before use. Product teams test a new rate with an A/B experiment and publish the winner to all customers. Clocknext is positioned for AI-native teams globally, including AI founders and the product, engineering, and revenue functions inside those companies, and it lists Boomerang, Facilio, Superb AI, Strivelabs, and Ninjahire among the teams using it. The platform is offered with a free start and a free trial — free up to $100K USD in billed revenue — alongside a demo booking path for teams that want to see it in action. It also publishes a guide to pricing economics for AI agents, aimed at teams refining their pricing strategy. In summary, Clocknext is monetization infrastructure for AI agents that unifies metering, flexible pricing primitives, prepaid and postpaid payments, and real-time margin analytics in one system. Its primary value proposition is straightforward: meter AI usage as it happens, price it in whatever mix of credits, outcomes, and units fits the product, change that pricing without a deploy, and see margin per customer, per agent, and per model so AI billing stops being the bottleneck between usage and revenue.
Glasshand hosts real iPhones and Macs in its own data center and rents them, month to month, to AI agents. Instead of asking an agent to imagine what a phone or a desktop looks like, you give it an actual device that it can see and operate. You connect Claude Code, Codex, Cursor, OpenClaw, Hermes, or any other agent through the Glasshand API, and the agent rents an iPhone or a Mac from glasshand.com with a prompt. From there it can watch the screen and tap, type, or click exactly the way a person would. Glasshand is aimed at people who want their agents doing real work inside Apple's ecosystem: running social accounts, building and testing native apps in Xcode, or handling everyday admin that lives behind a sign-in. The page frames the core problem as realism. Glasshand runs real iPhones and Macs, "not virtual machines, emulators, or simulators," and asks why a real device is better. The answer it gives is that a rented device works just like the iPhone or Mac you use every day: it reaches Apple's ecosystem, it can carry a real phone number, and it can be locked with a password you set yourself. That matters for the kinds of tasks that break on a simulated device, such as installing apps from the App Store, receiving a verification text at a phone number, or completing sign-in and checkout flows on hardware that behaves like the phone in a customer's hand. Control happens through a dedicated controller. The agent asks the controller to show the screen, the controller looks, and the iPhone answers with what is displayed, for example the home screen. The agent then works through steps the way a person does: see the screen, open the browser, type a search, and check the result. Glasshand illustrates this with a simple goal, "Find the weather in San Francisco," where the agent reads the screen, opens the browser, types the query, and verifies the answer. Because the loop is see-then-act, the same approach carries from a one-off lookup to multi-step work inside apps, and the agent responds to what is actually on screen rather than to a fixed script. Because the hardware is genuine, the software is genuine too. Agents download real apps, including Instagram, TikTok, WhatsApp, and more, from the App Store rather than working against stripped-down replicas. An iPhone can also be given its own phone number by adding an eSIM plan with SMS, which lets the agent receive verification texts and use iMessage. That combination is what makes account-based work possible: a verification code arriving at the device's own number is exactly the step that stalls an agent running anywhere without one. Users also set a real password that locks the device, just as they would on their own phone. The third piece is account context. Users sign in to iCloud and the apps they already use, so the agent can work with calendars, contacts, messages, and files to get tasks done with the context it needs. This is the difference between an agent that can open an app and an agent that can act inside it. Glasshand also states that the setup persists: apps, files, and sign-ins stay put between tasks until the device is released. A single rented device therefore accumulates your configuration once, and every later task your agent runs starts from a device that is already signed in and already equipped. The rental lifecycle is stated plainly. Your device starts factory-reset, ready for your apps and accounts. It is not shared with other customers, it is yours alone, and you set the password. When you release it, Glasshand erases your data and restores the device to factory settings, and the controller is wiped and reset too. Sessions are not billed by the hour or the day; devices are rented month to month, and you can cancel at any time. If you cancel, your device stays available until the end of your current billing period, then your subscription ends. Getting started is designed to happen inside the agent's chat rather than in a separate console. You tell your agent to rent an iPhone or a Mac, paste the prompt Glasshand provides, and then approve and pay when the agent asks. The same flow is offered for both device types: rent an iPhone from glasshand.com and connect so the agent can see the screen, tap, and type, or rent a Mac and connect so it can see the screen, click, and type. Glasshand lists Claude Code, Codex, Cursor, OpenClaw, and Hermes as compatible, alongside any other agent that connects through the API, and a demo can be booked as well. Glasshand names three broad jobs. Running your socials means posting on Instagram, TikTok, and LinkedIn, replying to comments and DMs, finding leads, and following up, which depends on being signed in as a real account on a real app. Building and testing apps means building native apps in Xcode on a hosted Mac and testing sign-in and checkout on a real Mac or iPhone, so the flows that usually fail only in production get exercised on real hardware instead. Working with your accounts means signing in to iCloud and the apps you use so the agent can reach calendars, contacts, messages, and files. Everyday admin sits alongside these, and the site sums up a device's purpose as running social media, building and testing native apps, and handling everyday admin. The people this suits are those already directing agents and wanting them to reach places an API alone cannot: social media teams and founders posting across Instagram, TikTok, and LinkedIn; developers who need real hardware for Xcode builds and for sign-in and checkout tests; and anyone whose calendars, contacts, messages, and files live behind an iCloud sign-in. The requirement is an agent that can call the Glasshand API, such as Claude Code, Codex, Cursor, OpenClaw, Hermes, or anything else, and a willingness to rent month to month rather than by the hour or day. The proposition is narrow and concrete: your agent gets a real iPhone or Mac, hosted and maintained by Glasshand, that it controls by seeing the screen and acting on it, that keeps your apps and sign-ins between tasks, and that is erased and factory-reset when you let it go.
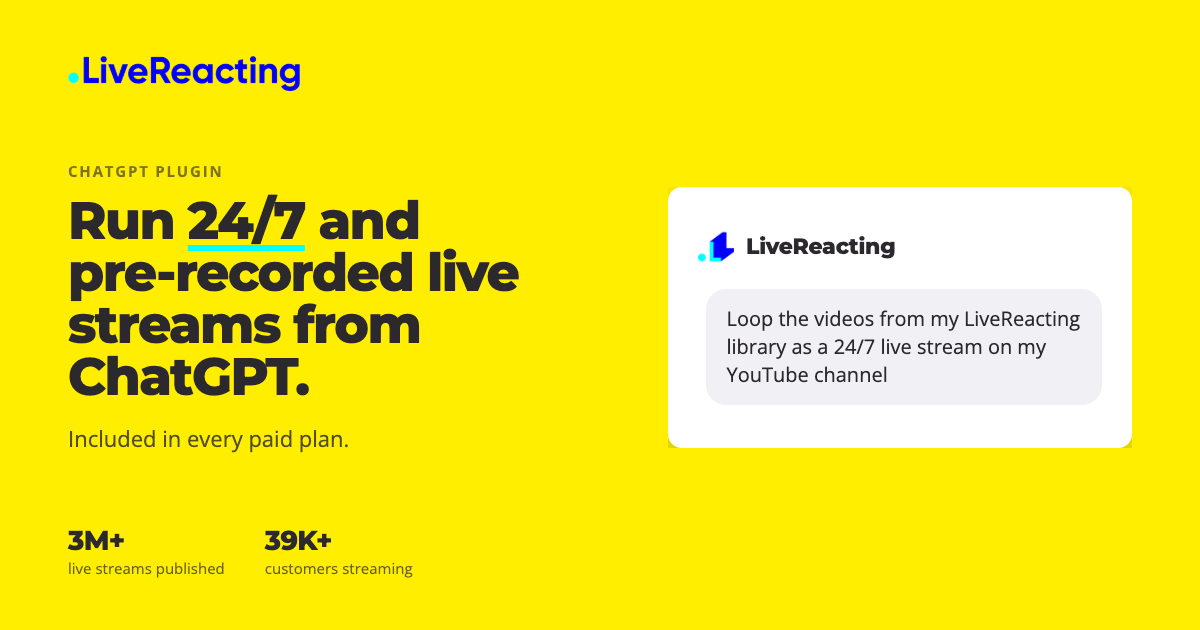
LiveReacting for ChatGPT is a ChatGPT plugin that lets people create and manage live streams by typing a request into a ChatGPT chat. After installing the plugin and signing in with a LiveReacting account, a user types @LiveReacting and describes the stream they want: a 24/7 loop of videos on their YouTube channel, or a recorded video that should go live at a time they choose. ChatGPT then works with what already exists in the LiveReacting account — the videos in the library and the channels that have been connected — and builds the stream there. LiveReacting's servers send that stream to YouTube, Facebook, Twitch, LinkedIn, X or any other platform the user has connected, all at the same time, so the user's computer can be off while the broadcast runs. Running a continuous or scheduled live stream normally means opening a streaming tool, preparing the video files, building a playlist, picking destinations and starting the broadcast — a sequence of steps that has to be repeated for every new stream. LiveReacting for ChatGPT moves that work into a conversation. The product page frames the experience as asking for a stream "in your own words": type @LiveReacting, then say which videos, which channel and what time, and ChatGPT works out the steps and reports back when they are done. This matters for creators, pages and teams that publish recurring or scheduled streams and would rather describe the outcome they want than operate a streaming interface each time. Two of the plugin's core capabilities are looping videos as a 24/7 live stream and scheduling a recorded video. For a 24/7 stream, the user names the videos and the channel; ChatGPT puts them in a playlist in the order the user wants, and that playlist plays on a loop until the stream is stopped. For a scheduled stream, the user gives ChatGPT the date and time the broadcast should start, up to 28 days ahead; LiveReacting starts the stream at that time and ends it when the video ends. The scheduled mode plays the video once, which contrasts with the loop that runs continuously. Both modes are created from the same chat, so a user can move between a permanent channel and a one-off broadcast without leaving the conversation. The plugin works with videos that are already in the user's LiveReacting library, and it can add new ones from a link. A user can give ChatGPT a Google Drive link, a Dropbox link, a public link to a video file, or a video from their own YouTube channel, and ChatGPT adds that video to the library. When building a 24/7 stream from library videos, ChatGPT finds the videos in the library and checks that each one can be streamed before building the looping playlist. Videos stored on the user's own computer are handled differently: they are added to the library in the LiveReacting Studio first, after which the user can ask ChatGPT to use them. In the chat itself, ChatGPT takes a new video from a Google Drive, Dropbox or public link rather than from a file the user attaches. Multistreaming is built into the same request. A user can pick several channels for one stream, and LiveReacting sends it to YouTube, Facebook, Twitch, LinkedIn, X or any other platform connected to the account at the same time. This means a single chat request can reach several audiences at once instead of requiring a separate setup for each destination. The product page also notes a practical limit on Facebook: Facebook ends a live stream after 8 hours, so a 24/7 stream cannot run on Facebook alone. Adding YouTube or another platform to the same stream keeps it running there, which is why multistreaming matters for continuous channels. Streams are not frozen once they start. From the chat, a user can add a video to the playlist or switch to another scene while the stream is live; viewers see the change and the stream keeps running. The plugin also reports on performance. A user can ask whether a stream is live and how it is doing on each channel, and for past broadcasts ChatGPT tells them how long each one ran and its peak viewers. Together these two capabilities turn the chat into a lightweight control and monitoring surface for streams that are already broadcasting. Under the hood, the plugin connects to the LiveReacting MCP server, the same server that Claude, Claude Code, Cursor and other AI agents use. Setup is short: choose Open in ChatGPT, click Install plugin, and sign in with a LiveReacting account when ChatGPT asks; then, in any chat, type @LiveReacting and ask for the stream. ChatGPT receives access to the LiveReacting account but never sees the user's platform logins — YouTube, Facebook, Twitch and other channels are connected inside the LiveReacting account, and ChatGPT picks from the ones that were connected. The actual broadcast is produced by LiveReacting's servers and sent to the chosen platforms, which is what allows the user's computer to be switched off. The main benefit is that a stream can be requested in natural language and then runs without the user's machine being involved. Because LiveReacting's servers send the stream, the user is not tied to a computer during the broadcast. Because the plugin works with the videos and connected channels already in the account, users do not need to rebuild assets for each stream. Because the playlist can be changed and the status checked from the same chat, routine maintenance — swapping a video, checking which channels are live, reviewing how long a past broadcast ran and its peak viewers — happens in the conversation where the stream was created. The product page illustrates the workflow with example prompts. One asks to loop the videos from the LiveReacting library as a 24/7 live stream on a YouTube channel, which suits a channel that should always be broadcasting. Another asks to live stream a recorded video from Google Drive on a Facebook page today at 8 PM: ChatGPT imports the video from the link, builds a stream that plays it once, then schedules it for 8 PM on the Facebook page. A third asks to show the status of running live streams, and ChatGPT lists which streams are live and how each one is doing on every channel. The same capabilities cover multistreaming one stream to several destinations and adding a new video to a playlist mid-broadcast. The plugin is included in every paid LiveReacting plan. On the Free plan, ChatGPT can connect, but each request stops with a message that the account needs a paid plan. The page is explicit about what the plugin cannot do: it cannot build overlays, polls or trivia, which are created in the LiveReacting Studio, the browser-based stream editor — although ChatGPT can still start, schedule, stop and check a stream that has them. It cannot import a YouTube playlist or channel; users give one video link at a time in the chat, or import the whole playlist or channel in the Studio. And it cannot run a 24/7 stream on Facebook alone, because Facebook ends a live stream after 8 hours; adding YouTube or another platform to the same stream keeps it running there. In short, LiveReacting for ChatGPT turns a chat message into a running broadcast. It combines 24/7 looping playlists, scheduled pre-recorded streams up to 28 days ahead, multistreaming to the platforms a user has connected, live playlist and scene changes, and status and viewer reporting, all handled on LiveReacting's servers so the user's computer can stay off.
Render Sandboxes, currently in beta, gives every AI agent its own isolated compute, persistent state, and filesystem. In the product's own words, it is a computer for every agent. Each sandbox is a separate Linux computer that an agent can use to run commands, keep files, and return to work it left running, rather than operating inside the same environment as the application it serves. Sandboxes are designed for developers building agents and agent harnesses — the product cites Claude Code and Codex as examples of what can run inside one — as well as for teams that need a safe place to execute untrusted code. The stated purpose is to give agents real tools, files, and processes that persist between sessions, all on the same platform as the rest of the application. Agents need somewhere to work. Running a coding agent or an autonomous task loop directly on application infrastructure raises practical questions: where do the files live between runs, how do you stop one agent from reaching another's data, and what happens to compute spend when the agent sits idle waiting for input. Render Sandboxes addresses those questions by making the sandbox the unit of work. Each one is isolated, so user-submitted code, model output, and uploaded files stay separated from the app's data and secrets. Each one persists, so an agent can pick up where it left off. And each one can be suspended, so idle waiting does not accumulate compute charges. The product also targets scale: Render says you can reliably run thousands of sandboxes at once, on the same platform as the rest of your app. Sandbox lifecycle is managed with TypeScript or Python SDKs or a CLI. The documented flow is explicit: create a sandbox and set a maximum lifetime, then wait until the sandbox is ready. From there you upload files and download artifacts, moving inputs into the sandbox and pulling out the files the code generates. You can run commands and stream output, receiving stdout, stderr, and the command's exit code as it arrives rather than waiting for a batch result. The quickstart example shows the same sequence in code: create a sandbox with a timeout, upload a task file, execute a Python agent followed by a test run, capture a snapshot, and terminate. Because output streams, an agent can inspect a failure and try a fix inside the same session. Snapshots give sandboxes a starting point. You can save a snapshot of a sandbox and later fork an independent sandbox from it, running processes included — so a session that has already installed dependencies, cloned a repository, or started a service does not have to repeat that work. New sandboxes can also start from custom images or saved snapshots preloaded with the files and tools each task needs, which Render describes as giving agents a head start. Multiple agents can work from the same starting point by forking the same snapshot, and each fork is independent. This matters for parallelism: instead of provisioning a fresh environment per task and paying the setup cost every time, you snapshot a known-good state once and branch from it. Isolation is the core of the design. Each Render sandbox runs in its own Firecracker microVM, so agents can use Docker and return to processes they left running without sharing a kernel with anything else. On top of isolation, Render provides access controls. You decide which domains each sandbox can reach: outbound requests can be limited to approved domains, or outbound traffic can be blocked entirely. Render API keys can be created with only the permissions a task needs — for example, managing sandboxes without access to other services (listed as early access). Sensitive credentials can be brokered: approved API requests are authenticated without giving sandbox code the raw keys or tokens (also early access). Together these controls let teams run untrusted code without handing it the keys to production. Overall, the approach is to treat each agent's environment as a disposable, resumable machine rather than a long-lived server. Sandboxes start in under a second, even when traffic arrives in bursts, and they run on the same platform as the rest of your application, so the agent's compute sits alongside the app it is working on rather than in a separate system to be wired up. Sandboxes suspend automatically when idle, with no compute charges until your agent sends its next command, and they wake with files and memory intact. While a sandbox runs, you are billed only for the CPU it actually uses. The benefits follow from those mechanics. Agents keep their work between sessions instead of rebuilding context and environment on every run. Failures are visible and debuggable because logs, errors, and exit codes stream back. Setup cost is paid once and reused through snapshots and custom images. Demand spikes are absorbed because start times stay under a second and thousands of sandboxes can run concurrently. Spend tracks actual CPU use rather than wall-clock time spent waiting for input, since idle sandboxes are suspended. And risk is contained: untrusted code, model output, and uploaded files stay isolated from application data and secrets. Render names three use cases directly. First, run your agent inside a sandbox: give agents tools, files, and processes that persist between sessions. Second, spin up a full copy of your app: run your whole stack with Docker Compose inside a sandbox so your agents can test changes end to end. Third, safely execute untrusted code: keep user-submitted code, model output, and uploaded files isolated from your app's data and secrets. The lifecycle primitives extend these — snapshots and forks support multiple agents working from the same starting point, and streamed output supports agents that iterate on a failing test, while sub-second starts support bursty workloads where many sandboxes are needed at once. The product is aimed at developers and teams building agents and agent harnesses, and at applications that need to execute code they did not write. It fits teams already deploying on Render, since sandboxes live on the same platform, and it is exposed through TypeScript and Python SDKs and a CLI, with a quickstart that walks through installing the Render CLI, signing in through the browser, creating a sandbox, running a command, and terminating. Pricing is usage-based: sandboxes suspend when idle, there are no compute charges until the next command, and while running you pay only for the CPU actually used. Render points to its pricing page for details. Render Sandboxes packages a simple idea — a computer for every agent — into an operational one. Isolation comes from Firecracker microVMs; persistence comes from a filesystem and snapshots that survive suspension and can be forked; control comes from domain restrictions, scoped API keys, and credential brokering; and economics come from suspending idle sandboxes and billing actual CPU. As Stuart Layton, Head of Technology at FinQore, puts it in the customer quote on the page, Render Sandboxes have kept the promise of moving fast. For teams putting agents to work on real code and real files, it is a way to give them a machine without giving them the keys.
MachineMail is an email API built for AI agents. It gives each agent a real inbox that it can sign up with, wait on, and reply from, so an agent can send and receive actual email instead of being confined to a chat window. Agents connect over MCP from any client — the site lists Claude Code, Codex, OpenCode and Copilot — or through an API. Every inbound message arrives as agent-safe text with a trust level attached, and the agent reads it over MCP wherever it runs. MachineMail is aimed at developers and teams building autonomous agents that need a working email address to complete real tasks, and it presents itself as email for both humans and bots, with no per-inbox fee. Agents increasingly need an email address to do real work: to sign up for a service, receive a one-time code, wait for a reply, or take in an invoice. Handing an agent a mailbox is risky, because everything that lands in an inbox is untrusted input written by someone else. MachineMail frames this as the core problem — the site promises that nothing in the inbox can hijack your agent and describes mail your agent can safely read. Instead of passing raw mail through, it converts each inbound message into agent-safe text, removes hidden instructions before the agent reads a word, and attaches a trust report and a trust level. A message from a lookalike domain such as paypa1-payouts.ru, for example, is presented with a failed DMARC check, a link display mismatch, hidden text that was removed, and a quarantined level. Connecting an agent takes one command. MachineMail exposes a single Streamable HTTP MCP server, and developers either sign in with OAuth from the MCP client or pass an API key when running in CI. The documented setup command adds the server to Claude Code, and the site says the same prompt works with Cursor, Codex, OpenCode and Copilot, plus any other MCP client. For agents that cannot be configured by hand, the site offers a copyable agent prompt: paste it into Claude Code, Cursor or another MCP client and the agent registers itself through auth.md, receives a sandbox inbox and one ephemeral inbox, and shows a six-digit code that the user enters at /claim to bind the agent to their organization. Addresses are created either with a single API call or automatically through a catch-all domain. Once a domain is pointed at MachineMail, any address on that domain works and the inbox appears on first delivery, which means an agent can be handed an address in advance without provisioning anything first. The site shows a mix of ephemeral inboxes with expiry timers — signup-7f3k@acme.dev expiring in 24 hours, otp-runner@acme.dev in 23 hours, invoice-intake@acme.dev in six days — alongside permanent addresses such as qa-bot-12@acme.dev and support@acme.dev. There is no per-inbox fee: the site states $0 per inbox and per trust report on every plan. The trust layer sits at the centre of the product. Every inbound message receives a trust report and is sorted into one of five levels, and the agent is instructed to act on the level rather than on anything the sender says. Verified messages can be acted on; known messages are summarised; unknown messages are read only; suspicious messages are reduced to reasons only; quarantined messages are withheld entirely. The report itself lists the evidence behind the level — the example on the site includes a failed DMARC result, a link whose display does not match its target, and hidden text removed from the message before the agent saw it. Because the level is attached before the agent reads the text, the agent never has to make its own judgement call about whether a sender is genuine. Delivery can be pull or push. Webhooks push mail into the developer's own stack: they are signed, retried for five days and replayable from the dashboard, with event types such as inbox.created, message.received, message.received.quarantined and message.bounced. Replayability lets a team re-run a delivery after fixing a handler without losing the messages that arrived during the outage. For agents that prefer to fetch, the MCP server provides wait_for_message, which holds the call open until mail actually lands, for up to a minute, so the agent does not have to poll in a loop. In the site's illustration the waiting call returns a message from no-reply@acme.dev with a verified trust level and agent-safe text containing a one-time code. MachineMail's overall approach is to handle the email plumbing and the security judgement in one place, then expose only the safe result to the agent. A trust level is not a single check but a combination of SPF, DKIM and DMARC alignment, the account's own allow and block lists, prior correspondence with the sender, link and attachment checks, and a classifier. The report lists every reason it used, so a developer can see exactly why a message was verified or quarantined and can adjust their allow and block lists accordingly. Because the same report is produced on every message, on every plan, at no extra cost, the trust decision stays consistent whether an agent is reading a one-time code, an invoice or a support request. The practical benefit is that an agent can be given a genuine email identity without also being given an attack surface. The agent gets an address it can sign up with and reply from, mail it can read as clean text rather than raw HTML, and an explicit instruction about how much to trust each message. Developers get a managed inbox they do not have to provision one by one, webhook delivery they can replay, and a return call that blocks until mail lands instead of burning cycles on polling. Ephemeral inboxes add a disposable option: addresses that expire on their own and are cleaned up by a reaper, so short-lived agents do not leave mailboxes behind. The example addresses on the site map onto concrete workflows. A signup inbox such as signup-7f3k@acme.dev lets an agent register for a service and receive the confirmation, then disappear after 24 hours. An address like otp-runner@acme.dev is built for receiving one-time codes, which is exactly what wait_for_message is shown returning. invoice-intake@acme.dev covers a longer six-day window for documents that arrive asynchronously, while permanent addresses such as qa-bot-12@acme.dev and support@acme.dev suit bots that need a stable, long-running mailbox for testing flows or handling support correspondence. In each case the agent reads agent-safe text with a trust level rather than the raw message. MachineMail is built for developers and teams running autonomous agents — particularly those working in Claude Code, Cursor, Codex, OpenCode or Copilot — who need their agents to hold a real address. Pricing starts free: the Free plan costs $0 and covers 3,000 messages a month, with paid plans starting at $9 a month and no per-inbox charge. A message counts as each inbound delivery and each outbound send, while spam, quarantined and rejected mail do not count, and neither do drafts until they send. Ephemeral inboxes are cleaned up by a reaper that deletes the inbox with its messages, raw MIME and attachments, then emits inbox.expired, and new mail before expiry pushes the deadline out. The API is described as AgentMail-compatible. In short, MachineMail gives AI agents what they have been missing — a real, low-cost email address — and pairs it with the thing an inbox full of untrusted mail actually requires: a per-message trust report, a defined level of action, and agent-safe text that has already had hidden instructions stripped out before the agent reads a single word.
XWiki MCP Server is a free, open-source, self-hostable extension that connects an XWiki knowledge platform to the AI agent of your choice. XWiki itself is a versatile knowledge platform for teams of all sizes, used to create wikis, documentation spaces, intranets, procedures and knowledge bases, where knowledge is organized in real time, collaborators work together, information is found faster and access is managed. The MCP Server adds a connection layer so that AI agents such as Claude Code, Codex, OpenCode, Pi, GitHub Copilot and MS Copilot — or anything else that speaks MCP — can work directly with that accumulated knowledge. Its stated purpose is to give your AI your wiki's knowledge while keeping the control: the extension is optional, installed by you and configured by you, rather than being a vendor-side feature that operates on your documentation without your say. The extension arrives at a specific moment for XWiki. XWiki has been around for over 20 years, which the team notes is plenty of time for organizations to build up a lot of knowledge in their wikis: documentation, internal procedures, and custom applications full of structured data. As AI agents become ingrained in daily workflows, the makers started thinking of ways to make all that internal knowledge available to them. The positioning is blunt: when knowledge grows, other tools start to break, and XWiki scales. A related problem raised in the launch discussion is that knowledge systems can eventually become write-only, and connecting them to an agent of choice may help surface what is already stored. The other half of the problem is control. The makers point out that Confluence announced this year that it will train AI on user documentation, something they completely disagree with, and that is why the XWiki MCP server keeps control in the hands of users, with the freedom to host as needed. Once an agent is connected, the first capability is reading. You can use the extension to query your knowledge base to get answers, so an agent can find out about an old project decision rather than a person digging through pages manually. Because the agent navigates the wiki with the same permissions as your user account, what it can see mirrors what you can see. Write, delete and page creation tools are destructive and are disabled by default, which the makers describe as the default starting point so no accidental oopsies happen; they can be turned on by ticking a box on the configuration page. That means a team can begin with read access, observe what the agent does with its wiki, and only later decide to allow changes. When write operations are enabled, the scope goes well beyond reading. The extension lets agents create and edit pages, update attached documents, and even build a small internal app. Since XWiki supports structured data, agents can work with objects and classes, not just read and write pages — the makers call this combination of XWiki and AI especially good for developers. Working with structured data means an agent is not limited to free text: it can operate on the data models that custom applications inside the wiki are built on. The launch description lists three things you can already do with the extension: query your knowledge base to get answers, create and edit pages, and work with structured data directly in XWiki. Control is enforced at several levels. The MCP endpoint is an OAuth protected resource: it advertises the XWiki OIDC Provider through the standard RFC 9728 metadata and a WWW-Authenticate header on a 401 response. Clients such as Claude Code or Claude Desktop discover it, run the normal OAuth authorization code flow against the OIDC Provider, and send a Bearer token; XWiki validates the token and the agent acts as that user, with that user's rights. The XWiki OIDC Provider extension must be installed for this. On the content side, XWiki has several deconflicting mechanisms: when collaborative editing is disabled, pages are locked while someone edits them; when collaborative editing is on, page saves are propagated to all users; if conflicts do appear, you choose whether to merge the changes or keep one or the other. Unlimited version history lets you revert a page to a previous version, and reverting restores the whole page — as a workaround for partial reverts you can preview any version and copy-paste changes into the latest version. Scripting capabilities, on top of being open source, make it possible to define and use your own deconflicting strategies. Overall, the product is an MCP server: an extension that speaks the Model Context Protocol, the interface through which AI agents call tools on an external system. Anything that speaks MCP can be connected, and the makers name Claude Code, Codex, OpenCode, Pi, GitHub Copilot and MS Copilot as examples. Installing it is a choice rather than a given: you decide if and when to install it, which model to connect through it, and where everything runs. You can self-host everything — XWiki, the MCP server and the AI model — if that is what you need. Because XWiki and the MCP server are fully open source, anything missing from the MCP layer is probably already doable through the REST API, which agents are described as quite good at using; if something is missing from the API, the open-source project can be extended or the changes contributed upstream. There is also a repository of skills and knowledge for agents (xwiki/xwiki-dev-llm on GitHub), an installation guide, source code on GitHub (xwiki-contrib/ai-llm) and feedback tracked on JIRA. The stated benefits follow from that design. Teams get an agent that can find out about an old project decision, update pages and attached documents, or build a small internal app, without exporting their knowledge to a third party. Discoverability and efficiency improve with the help of agents while the platform remains human-focused, which the makers describe as the focus: not turning the wiki into an agent-only system, but making what people wrote easier to reach. Documentation owners keep control rather than handing it to a vendor, and administrators keep the ability to run everything on their own infrastructure. Starting with read access gives a team room to see what the agent does with its wiki before enabling writes, and unlimited version history plus page-level conflict handling provide a route back if an agent edit goes wrong. Concrete scenarios named in the launch material include asking an agent about an old project decision recorded in the wiki, having it update pages, having it update attached documents, and having it build a small internal app. More broadly, XWiki is used to create wikis, documentation spaces, intranets, procedures and knowledge bases, and the MCP Server exposes that material to an agent of choice, so an organization's documentation, internal procedures and custom applications full of structured data become reachable by that agent. The makers also frame this as a fit for agentic workflows: one commenter noted they were using Confluence org-wide and that it was not coping with agentic workflows. The extension can be explored for use cases the team has not yet thought of, and the makers explicitly invite experimentation. The extension targets teams and organizations already using XWiki, and by extension any team that treats documentation as a long-lived asset — the wiki, intranet, procedure and knowledge base use cases XWiki serves. Named integrations are the AI agents themselves: OpenCode, Pi, Codex, Claude Code, GitHub Copilot and MS Copilot, plus anything else that speaks MCP. Two XWiki extensions are relevant: the XWiki OIDC Provider extension, required for the OAuth flow, and the MCP Server extension itself, installed and enabled as needed. The product is free and open source, listed with free options on Product Hunt and launched under Productivity, Open Source and Artificial Intelligence tags; the launch reached 175 upvotes and 38 comments with a #4 of the day badge for October 30th, 2026, while XWiki itself is rated 4.8 from 6 reviews. The takeaway is straightforward: XWiki MCP Server gives AI agents access to a wiki's knowledge — reading, writing and working with structured data — while every decision about installation, connection, hosting and permissions stays with the organization that owns the documentation. It is free, open source, optional and self-hostable, with destructive operations off by default and the agent bound to the rights of the connecting user. For teams whose knowledge has grown beyond what older tools can carry, that combination of reach and control is the point.
BrewPage is free HTML and Markdown hosting for AI artifacts, static websites, documents, reports and files. Publish content and get an HTTPS link without required registration, a repository or a deployment pipeline.Share AI-generated HTML from ChatGPT, Claude, Codex and other assistants as a rendered page. Publish a multi-file static site, share Markdown as a readable document, or deliver a generated report or file through a link. Developers and AI agents can automate publishing through the HTTP API, MCP server, GitHub Action and public publishing integrations. JSON and key-value hosting are also available.Typical uses include sharing an interactive report with a client, sending a generated dashboard to a teammate, publishing a small static website, and turning an AI artifact into a link someone can open.BrewPage is temporary hosting: content expires. Retention is up to 30 days without a profile and up to 90 days with a free profile. Publications retain format and size limits; a free profile extends retention rather than making links permanent. The hosted service is proprietary; its public MCP server and publishing integrations have their own open-source licenses.
JST-2 is Viggle's physics-native world foundation model for generating 3D scenes, characters and full-body motion in one shared world. Built by Viggle, which describes itself as a spatial GenAI platform, the model is centered on characters: it takes one image, or text, and returns a complete full-body 3D character with motion dynamics already built in, ready to animate without separate rigging and skinning steps. The same model generates 3D scenes, which Viggle says take about one second, and produces motion from text or video. It can be tried free in the PINOC browser app, used through Viggle's API, or accessed via MCP with agents such as Claude Code. The character research page documents how the model was tested and where it still falls short. In a conventional animation or game pipeline, a generated character is only the starting point. Rigging and skinning are specialist work measured in hours, and once a rig is built it decides how the character moves for the rest of its life. JST-2 targets exactly that handoff: instead of building a shape and then attaching a rig, it builds the character and its motion dynamics in one generation, so a single input image or prompt yields something already animation-ready. A second problem is input quality. Real creative inputs are not studio plates, and lighting, angle, framing and occlusion are all over the place. Characters are often cropped, turned away, or missing hands and feet, and the model is designed to complete those partial inputs into a body whose structure and proportions hold together. JST-2 generates 3D characters from a single image or from text. In Viggle's blind human tests against Meshy 7.1 and Tripo H3.1, the model led both baselines on character generation, with its strongest results on facial detail. Face quality scored 63.0% against Meshy 7.1 and 82.0% against Tripo H3.1, where a score of 50% means equal preference and draws count as half a win. Facial detail is what preserves a character's identity in 3D, which matters when the asset is your own digital double, an actor's stand-in, or an IP character you will reuse for years. Texture quality, body quality and clothing quality were also rated above both baselines: against Meshy 7.1 the model averaged 58.4% overall, and against Tripo H3.1 it averaged 73.2%. The model also completes characters from cropped or partially occluded images across a wide range of visual styles. When only the upper body is in frame, when the subject is turned away, or when hands and feet are hidden, JST-2 extends the visible region into a full body whose structure and proportions hold together. Viggle notes that on clean images all three tested models are usable and the gap opens on difficult ones, and that real creative work rarely starts from a clean image. The test set reflects this: alongside the photoreal, stylized, cartoon, anime and sci-fi categories used by major commercial 3D asset platforms, it adds hard samples drawn from what users actually upload, including unusual poses, occluded subjects, off-axis viewpoints, bodies cropped out of frame, difficult lighting, low-resolution and blurred images, and busy backgrounds. Motion is where the model is most differentiated. On animation readiness, defined as how a generated character moves once it is driven, JST-2 led Meshy 7.1 with an average score of 73.8% and Tripo H3.1 with 88.9%. The criteria were joint alignment, rig usability, deformation quality and hand rigging. Hand rigging reached 82.8% against Meshy 7.1 and 89.3% against Tripo H3.1, while deformation quality reached 77.6% and 93.2% respectively. Every finger moves on its own, and once the character moves, clothing, hair and accessories deform with the body rather than fighting it. All of this happens in a single generation: complete body, 3D character and motion dynamics at once, with no remesh and no separate rigging step left for the user. Under the hood, JST stands for Joint Space-and-Time. The model represents the world as persistent atoms in 3D space: each atom represents a piece of matter or an object part and retains its identity as it moves and deforms, carrying an explicit xyz position plus learned vectors for its attributes and dynamics. These atoms are encoded as Physics-Native Tokens, and the JST decoder turns them into 3D Gaussian splats. A JST-2 character is built from these tokens, and the dynamics vectors inside its Physics-Native Tokens encode how each part deforms under different motions. Because those dynamics are learned from data rather than authored by hand, the character arrives ready to animate without separate rigging and skinning steps. The practical benefit is removing a specialist bottleneck. Rigging and skinning normally take hours of expert work, and the resulting rig locks in how the character can move for its whole life. With JST-2 the character and its motion dynamics come out of one generation, so teams can go from a single image or prompt to something they can drive. Identity is preserved in 3D through stronger facial detail, which helps when the same character is reused across projects. Because the model handles cropped, occluded and awkwardly framed inputs, teams can work from material they already have rather than requiring studio-grade photography. And since scenes, characters and motion are generated in one shared world, the outputs are meant to fit together rather than being assembled from separate tools. Use cases follow directly from the benchmarks. Viggle names digital doubles, actor stand-ins and IP characters that will be reused for years as the kinds of assets where preserved facial detail matters. Game and animation pipelines benefit from characters that arrive without a rigging step, with hands that articulate finger by finger and clothing that deforms with the body. Teams working from user-uploaded or imperfect imagery can complete partially framed subjects into full bodies. Beyond characters, the model generates 3D scenes in about one second and produces motion from text or video, and it can be driven through an API or through MCP with agents like Claude Code, which supports automated and agent-based workflows. The product is aimed at people building 3D characters and scenes: character artists, animators, game and animation production teams, and developers who want to call the model programmatically. Access options named in the content are the PINOC browser app, where it can be tried free, the Viggle API with a developer portal and documentation, and MCP for use with agents such as Claude Code. Viggle also lists related products including Meme Maker, PINOC, Games and the API. The technical foundation described is the Joint Space-and-Time representation, Physics-Native Tokens and 3D Gaussian splats, with learned dynamics driving character motion. Viggle is explicit about current limits. Gaussian artefacts can appear around limb joints, and in some cases the shoulder-to-torso join, the armpit and the gaps between fingers show holes, merging or collapse, which the page calls the most visible failure mode. Surface detail has a ceiling: hair, clothing and materials read cleanly at normal viewing distance but soften as the camera moves in. Unusual bodies that depart from normal human proportions, such as very long limbs, an exaggerated head-to-body ratio or a non-humanoid silhouette, can produce off joint placement and deformation. Clothing, hair and accessories deform with the body but are not simulated, so they do not swing from inertia or collide with the body or each other; scene collisions and object interactions still rely on rule-based physics. Viggle says upcoming releases will improve how complex clothing deforms during motion and how hair moves, and that JST-3 is in development to replace those rules with learned dynamics. In summary, JST-2's value proposition is a single model that produces complete, animation-ready 3D characters from one image or text, with motion dynamics built in rather than rigged afterwards, backed by Viggle's own blind human benchmarks against Meshy 7.1 and Tripo H3.1 and extended by scene generation and text- or video-driven motion in one shared world.