Trending Radar/trending
Track the hottest AI launches.
Follow real-time momentum across daily drops and the best of the month. Every signal is curated for teams hunting the next breakout product.
Active launches
10
Drops today
10
Top categories
5
Follow real-time momentum across daily drops and the best of the month. Every signal is curated for teams hunting the next breakout product.
Active launches
10
Drops today
10
Top categories
5
Kerno is an AI backend runtime QA engineer that writes and runs backend tests against your running application and its real dependencies. It independently tests your critical flows locally against your real stack, catching runtime and security bugs inside the agent loop before they merge. Kerno is built for engineering teams and coding agents that ship backend code and need fast, trustworthy verification of every change, and its stated purpose is to verify and secure everything your agents ship — locally. In most backend teams, the bottleneck is not writing code, it is proving it works at runtime. Verification typically happens hours later in CI, where failures pile up, draining engineering time, forcing expensive rework and slowing releases. The content illustrates this with simulated DORA-style metrics where lead time, production incidents, change failure and weekly rework all rise as verification is delayed. Static review reads your code and unit tests run on mocks, so neither can see runtime behavior such as double charges across services, authorization leaks across tenants, SSRF through a callback URL hitting internal metadata, broken contracts, resilience failures and MCP tools that return an empty body instead of an error. Kerno is positioned as the runtime quality and security layer for your backend, giving every developer and agent staff-level testing knowledge to catch the expensive runtime issues DIY testing and code review miss, right at the source. Kerno organizes its work into three modules. Module A, Real evidence, verifies every code change against your live stack and dependencies, catching the functional and security bugs that only surface at runtime, before they ship. Module B, E2E coverage, verifies every critical flow a code change touches: Kerno maps a change's blast radius and verifies each flow end to end. Module C, Consistent quality, brings the same high-quality verification loop to every engineer by giving coding agents structured signals and persistent code context on every change. The runtime test floor follows four steps. Step 01, Map: Kerno builds a graph of your codebase and docs, maps every entry point and the dependencies behind it, and maps your critical user flows with you. Step 02, Test: it tests each user flow as one journey across your APIs, then covers every entry point behind it in depth. Step 03, Verify: it re-runs every flow a change touches and shows the step that broke, with the outcome the user expected and what actually happened. Step 04, Heal: it updates entry-point tests as your product changes and re-generates flows when behavior changes on purpose, so the suite evolves with your code. In practice this means a diff on a flow such as checkout step 03 on POST /payments is surfaced as a specific change — for example charges going from 1 to 2 — and self-healing records intended changes such as updated tests and added flows from a pull request. Kerno catches the bugs that only appear at runtime inside the agent loop, across a set of verification gates. End-to-end user flows verify complete user journeys across your APIs, from the first request to the outcome read back from your system. Contract and schema validation checks request and response structures, data types, required fields, serialization rules and version compatibility. Authorization and authentication reviews token validation, role-based access rules, permission scopes, session handling and credential-related flows. Security validation covers broken object- and function-level authorization, injection, excessive data exposure, mass assignment and SSRF against the OWASP Top 10. Boundary and edge cases validate payload size limits, pagination behavior, null or empty values, malformed inputs and constraint-based validation. Error handling and resilience validate status codes, error body formats, retry behavior, backoff procedures, timeout handling and controlled fallbacks. MCP server testing verifies each tool an MCP server exposes, including returned content, structured output, schema conformance and error handling. AI agent testing, listed as coming soon, is intended to verify how your agent calls tools, chains model steps and handles streaming responses, with model providers mocked for deterministic runs. Kerno connects to the services and datastores you already run and manages the data layer so it can exercise them the way your application does. Kerno runs locally: `kerno init` starts the agent, indexes your endpoints, and runs a Kerno MCP server that your coding agents connect to, while `kerno status` reports indexing and application reachability. Kerno learns your business and standards: you can define custom rules in plain English, scoped to the repos and paths you choose, and it applies them on every run in scope. It also learns from every test run and the feedback you give it, building a sharper model of your codebase and standards over time through a lessons store that records discovered behaviors. Setup follows a clear schedule. In the first hour you install Kerno, point it at your repo, map every entry point, connect it to your running app and its dependencies, and map your critical user flows together. By the first day, Kerno covers your critical flows and builds baseline tests for every API, task and event behind them, and adding Kerno instructions to your agent guidance file enables validation of every change. Within the first week you roll out to your team, with the Kerno MCP connected to your agents, validating every code change and re-running the flows it touches before they reach production. A runtime control console at portal.kerno.io provides Analytics, Coverage and Behaviour Drift views across all repositories, showing flows covered, entry points covered, code changes tested, potential issues caught, tests in your suite and active developers, plus per-repo breakdowns. The stated benefits are concrete. The content reports 6× faster merges for PRs tested by Kerno, 48% more runtime issues caught, and 10 hours freed up per engineer every week to build. Verified customers describe Kerno as being up and running in minutes with no manual work, making API migrations smoother by instantly validating that every change made by Cursor worked as expected, providing quick feedback with no manual effort when used with Claude Code while saving debugging of integration issues post-merge, catching side effects and issues that would definitely break backends, and acting as a force multiplier that lets teams ship releases much faster without the manual overhead of QA. Kerno fits into everyday delivery workflows for backend teams. A team maps and tests its critical flows, such as checkout, refund-an-order and team-invite, then uses the console to track coverage, analytics and behavior drift across repositories. When an agent adds a feature, for example partial refunds to checkout, Kerno validates the affected flows and endpoints and reports failing steps such as a double charge on POST /payments before a fix brings all checks back to passing. Bugs are caught inside the agent's session before a PR is opened, and every PR is then re-checked in CI. Engineers can review reported potential issues such as a PATCH with no changed fields returning 200 and bumping updated_at, an IDOR attempt blocked when a customer changes another customer's id, mass assignment protection, payment details never appearing in a response, and an email change that stays inactive until confirmed. It also supports testing of MCP tools such as get_order_status and consumer entries such as charge.retry and order.shipped. Kerno is aimed at engineering teams, individual engineers and coding agents shipping backend code. It connects over MCP to any coding agent, including Claude Code, Codex, Cursor and GitHub Copilot. It supports eleven languages (TypeScript, JavaScript, Python, Java, Go, Rust, C#, C, Kotlin, Ruby and PHP), eight data and messaging systems (PostgreSQL, MySQL, MariaDB, MongoDB, ClickHouse, Redis, Kafka and RabbitMQ) and three clouds (AWS, Azure and Google Cloud). Security is a stated priority: Kerno encrypts everything end to end, never retains your code, and a SOC 2 Type 2 audit is in progress, with private code never stored or used for training. A free starting path is offered through `kerno init` and a free signup at portal.kerno.io, and the content references free-plan organizations retaining event data for 30 days versus 90 days for paid plans, indicating both free and paid tiers. Kerno's core promise is simple: verify and secure everything your agents ship, locally. By moving runtime verification into the agent loop instead of waiting for late-stage CI, Kerno gives every developer and agent staff-level testing knowledge, catches expensive functional and security issues at the source, and helps teams merge faster with fewer regressions reaching production.
Reelbird is a free, open-source screen recorder for macOS 15 and later. It records your Mac screen, camera and microphone, and a share link is on your clipboard the moment you stop recording. Later you can add auto-zoom, a smooth cursor and captions, then update that same link. It is built for Apple silicon Macs, requires no account, and is MIT licensed. Its main purpose is to combine the fast, link-on-stop workflow of Loom with the polished auto-zoom look of Screen Studio in a single take, for free, with the files kept on your Mac. The problem it solves is a split in existing screen recording tools. Loom gets you a link fast, but on its free Starter plan it stops each video at 5 minutes, keeps 25 videos, records up to 720p and offers no downloads, and it has no auto-zoom. Screen Studio produces polished auto-zoom videos but costs $29 a month, or $9 billed yearly, and its share link only exists after you export. Reelbird does both from one take, for free: the link is ready when you stop, the polish can come later under the same link, and every take is kept as MP4 files on your Mac. Reelbird sets no limits of its own. Where the alternatives still do more: Loom has comments, view counts and apps for every platform, and Screen Studio has a more mature editor and a signed download. Recording starts with a simple choice. You pick a display, a window or an area, and the shortcut ⌥⇧R starts a recording from any app. The picker shows windows to choose from, including ones on other desktops, along with switches for microphone, camera, system audio and Share while recording. Camera, microphone and system audio record as separate tracks, so screen, camera, microphone and system audio stay apart. Keeping those tracks separate means you can move the camera bubble or mute system sound after recording instead of committing at capture time. The recording bar shows the timer, microphone level, pause, restart, delete and Stop. Share while recording is the core of the workflow. With it turned on, Reelbird uploads a 1080p stream to your own bucket as you record. When you stop, a Shared popover shows the link with Copy, Open in Browser and Update Link, and the link is already on your clipboard. You can paste it anywhere and it plays in any browser a moment later, with no app and no sign-in. The link never changes, even when you update the video: after editing, Update link replaces the video and the URL stays the same, so everyone you already sent it to sees the new version. Polishing happens under that same link, whenever you have time. Auto-zoom follows your clicks and typing, with a Subtle to Punchy slider in the Zoom inspector and zoom regions marked on the timeline; a real export zooms in on each click, then out again, planned from the clicks in the recording. The cursor is redrawn from the log so it glides smoothly instead of jittering, and you can resize or hide it after recording. Preview and export use the same Metal renderer, so the file looks exactly like what you watched. Framing options include background, padding, rounded corners, shadow, and a camera bubble you can move after the fact. Audio and captions are handled on the Mac. Auto level measures your voice and sets it to −16 LUFS, so a quiet take comes out at a normal level. Voice enhance uses Apple's sound isolation to take out room noise and hum where your Mac supports it, then applies a gentle compressor, de-esser and presence lift. Ducking dips system audio about 12 dB while you speak and brings it back when you stop. Captions are made on your Mac by Apple's speech recognition; you can burn them in or offer them as a track viewers can turn on. Cut Long Silences finds pauses and removes them in one go, and any cut can be restored. Safe peaks put a limiter on every track and on the mix with a −1.5 dBFS ceiling so nothing clips. Reliability and output formats are designed around not losing work. Every track is written to disk in 2-second segments from the first frame, so if your Mac crashes Reelbird recovers the take on next launch, minus at most two seconds. Warnings for a silent microphone, stalled capture, audio drift, a filling disk or uploads falling behind show up during the recording rather than after it. Exports come in the usual formats: MP4 (H.264), HEVC, ProRes and GIF with hardware encoding, in landscape, square, vertical or 4:3. Overall, the architecture is deliberately simple. Your Mac records and uploads; your bucket — Cloudflare R2, S3, B2 or MinIO — stores the files; any browser plays them. Setup takes about ten minutes, once: a bucket, a scoped API token and a public URL, entered through endpoint, bucket, region, access keys, public URL and prefix fields and verified with Test Connection. Reelbird is native and light: Swift, ScreenCaptureKit and Metal, with no Electron and no third-party dependencies. A take is an open project format — a .reelbird folder of standard MP4s, JSON and an event log — so nothing is locked in. Privacy follows the same principle: nothing leaves your Mac unless you share it. Recordings, edits, captions and transcripts stay in ~/Movies/Reelbird. Captions and titles come from Apple's on-device frameworks, with no API keys and no cloud. Shares go only to the bucket you set up, signed with your own keys, and the secret lives in your Keychain. There is no account, analytics, telemetry, crash reporting or update checks. Links are unlisted, not secret: anyone with a link can watch, so share accordingly, and Stop sharing deletes every file under that link. Reelbird can also be driven by an MCP helper: adding it to an assistant exposes list_sources, start_recording, stop_recording and share, so you can ask for a 20-second demo of a settings page you just changed and get the polished share link back. The benefits follow from that workflow. Because the link arrives the moment you stop, you can share immediately and improve the video later without resending anything. Because the polish happens under the same link, you avoid re-exporting and re-sharing. Because the files live on your Mac and your own bucket, you control storage and cost — Cloudflare R2's free tier of 10 GB with free egress covers most people. Typical scenarios include recording a quick demo of a feature you just shipped, turning a raw take of a task app or settings page into a walkthrough with zooms and captions, recording a voiceover with system audio and ducking or muting it afterwards, and capturing automated demos on request through the MCP integration. Installation, platform and pricing are straightforward. Reelbird is free and MIT licensed, with no paid tier, watermark or export limit. Download the zip from the download page, unzip it, and drag Reelbird to Applications; it is signed with an Apple Developer ID and notarized by Apple, so it opens like any other app. You can also build it from source with git clone and make install using Apple's Command Line Tools, with no Xcode needed. It runs on macOS 15 or later on Apple silicon Macs, and version 0.1.1 shipped in October 2026. It does not work on Windows or Linux, and that is not planned, because Reelbird is built on Apple frameworks throughout. In short, Reelbird gives Mac users a free, open-source way to record the screen, camera and microphone, get a share link the moment they stop, and polish that same take later with auto-zoom, a smooth cursor, captions and audio cleanup under a link that never changes. With your own storage bucket, no account and no telemetry, it is a privacy-conscious alternative that combines Loom's speed with Screen Studio's polish.
siliXon is a web platform that turns natural language into electronics. You describe the board you want to build in plain English, and siliXon takes it all the way to a routed, manufacturable PCB built on real, purchasable components. The company's framing is simple: natural language in, electronics out, for the whole world, not just engineers. The platform is built so that anyone with an idea can create their own electronics regardless of electronics background. Its design agent, Rocky, guides the process and lets you decide how much of the work it hands you. As siliXon puts it, if you can describe what you want, you can build it. Electronics design is locked behind years of studying and experience. According to siliXon, less than 0.01% of the world can design a circuit board, which means the vast majority of people with an idea for a device have no practical way to turn it into working hardware. Hardware is hard, and electronics is harder. The company also reports that after talking to over 100 engineers, it found engineering teams can take, on average, 2–3 months to get a PCB from concept to market-ready. siliXon's stated goal is to make electronics accessible to anyone: describing what you want should be enough to start building it, rather than requiring knowledge of components, schematics and copper routing. The workflow siliXon presents has four steps: Describe, Clarify, Generate and Manufacture. In the first step you provide just your ideas in simple English, with no constraints required. You can type a prompt such as "I want a garden sensor that texts me when the soil is dry." In the second step, siliXon's assistant Rocky chats with you along the way to help you figure out what you want your electronics to look like. Rocky asks you questions to verify your intent and gives you options to choose from, with the option it thinks is better recommended. Beta users have highlighted this behaviour: a student and hobbyist said they liked the self-validation and how it explains everything too, which makes it easier to cross-reference and learn on the go, while a founder appreciated that the response asks questions to verify and offers answers to choose from with the recommended option marked. In the third step, siliXon's system determines the best components and their placement, draws the schematic and routes the board. Rocky picks real, purchasable parts, and every component on the board exists on the market. The generated board remains visible and editable in both 2D and 3D. You can move parts, draw or remove traces, add vias, and revise the design through conversation — editing directly or simply asking Rocky. Rocky v1.5 is described as more accurate, far more precise in how it changes your board, and able to actually see the layout it is working on. The platform's placement and routing engine is highlighted as a world-class autorouter and autoplacer: siliXon placed third on comma.ai's PCB Golf contest, whose purpose was to get the smallest board possible given a set of components and a scoring algorithm, and it was the only autonomous entry on the podium. The fourth step is manufacture. Your board must pass all of siliXon's engineering checks before it goes to manufacture; the company runs physics and manufacturing tests and states that every board must pass them before being sent off. Once that is done, you send it off to manufacture and, as the site puts it, it is in your hands in a few days ready to use. You own the design, and siliXon provides all the necessary files to manufacture your board, including downloadable files. The Pro plan adds KiCad import and export as well as private PCBs, and the ability to upload silkscreen images is listed as coming soon. siliXon positions itself as more than an AI wrapper. Asked whether it is just another piece of "AI slop" software, the company answers that the product is built on sound electronic engineering principles, that AI helps speed up parts of the design process, that every component on the board exists on the market, and that each board is checked against physics and manufacturing tests before being sent off to the manufacturer. It states that the product is built to allow anyone to create their own electronics without needing to understand the intricacies of electronics design, and that the system checks to make sure your board can work and be manufactured. Because it is in early beta, siliXon currently allows users to create 2- and 4-layer boards and encourages users to play with mostly digital designs, as analogue circuit capabilities are limited. The headline benefits are speed and accessibility. siliXon promises end-to-end design in minutes: describe a board and get real parts, placement, routing, checks and files to manufacture. It also claims the fastest board generation in the world — going from a real prompt to a manufacturable circuit board in minutes, then sending it off to the manufacturer. For engineers, the benefit is iteration: iterate on your board quickly and make sure you only need to manufacture once, with the guidance that the more specific your prompt is, the better the final result. For beginners and hobbyists, the benefit is confidence and learning: the system teaches you along the way, and you can start with an idea and make changes as you see fit. siliXon addresses three broad user situations. A beginner who has an idea but no idea what a resistor is can use the platform to create their own electronics without understanding the intricacies of electronics design, with the system checking that the board can work and be manufactured. A hobbyist who designs and builds for fun but finds electronics tricky to grasp can start with an idea and make changes as they see fit, being taught along the way. An electronics expert can prompt the system with exact components, communication protocols and size to get a more precise result and iterate quickly. The site also offers real example boards to explore rather than only starting from a sentence: a Temperature indicator (27.5 × 32 mm, 2 layers, 18 parts, 14 vias), a Bluetooth remote (69.5 × 65.5 mm, 2 layers, 20 parts, 18 vias) and a USB Macro Pad (57 × 42.5 mm, 2 layers, 29 parts, 57 vias), each with a public preview link. siliXon is explicitly built for anyone with an idea, not only engineers — beginners, hobbyists and experienced electronics engineers alike. It is a web product: users sign up through app.silixon.io, and the platform is described as being in early beta. Pricing has two tiers. Free is £0 per month and lets you try siliXon on a real board with one end-to-end project every two weeks, limited Community access with two remixes, and public projects only; no card is needed. Pro, marked as most popular, is £14.99 per month with unlimited projects, Community access, unlimited remixes, private PCBs and KiCad import and export, while uploading silkscreen images is listed as coming soon; Pro is billed monthly and can be cancelled anytime. siliXon also notes a Product Hunt launch promotion of 48 hours of Pro, free, with no card needed. Overall, siliXon's core promise is that a sentence is enough to get started with electronics. By combining a conversational design agent, real purchasable components, an autorouter and autoplacer, physics and manufacturing checks, and fully owned design files you can send to manufacture, it lowers the barrier that has kept circuit board design in the hands of a tiny fraction of the world — natural language in, electronics out.
SuperLocalMemory is a governed memory brain for AI agents, positioned as one local-first memory shared by every agent a person or team runs. According to its listing, Claude Code, Codex, Cursor, ChatGPT and any MCP or CLI agent share the same governed memory, so context learned in one tool is available to the others. The product's stated purpose is to give agents durable memory that is trustworthy rather than approximate. Instead of guessing, recall tells you whether a memory actually answers the question, is only related to it, or is missing entirely. It is aimed at people running one or more coding agents on the same project, and at builders who need memory to be governed, with profiles, roles, an audit trail and verified erasure wrapped around a core that runs on the user's own machine. The project is open source under AGPL-3.0 and built by Qualixar, described as an AI Reliability Engineering lab behind 10 open-source products. The maker's relaunch post describes a rebuild around failures that showed up only after the first versions could already save and retrieve context. The harder failure was that a retrieval layer usually returns the closest thing it has, even when that thing does not actually answer the agent's question. In a chain of agents this compounds: one agent saves a half-related note, the next one treats it as fact, and the error travels onward. A second class of problem appeared once several agents shared durable state. The team needed to know when a fact was true, which agent wrote it, and who was allowed to read it, and whether deleting it really removed the derived copies. Those questions, accuracy of recall and governance of shared memory, are the two axes the relaunch was organised around. The headline capability is governed recall that refuses to bluff. Queries return one of three labels: supported, related, or no answer. Memories that are merely similar are handed back separately and labelled as related, while something is only marked as an answer when a stored memory actually supports it. When several agents share one memory, that label travels with the handoff, so a downstream agent inherits the uncertainty instead of a false certainty. An optional Answer Check verifies recall, checked by Laya on the user's Mac or by Jev online. One commenter singled out this distinction as the most valuable part of the design, noting that returning no answer is more useful than passing a vaguely relevant fact to the next agent. SuperLocalMemory is presented as one memory brain for every agent rather than a separate store per tool. Claude Code, Codex, Cursor, ChatGPT and any MCP or CLI agent connect to the same governed memory, whether through the Model Context Protocol or the command line. The system is described as mesh-connected, and the relaunch is accompanied by a separate mesh product listing from the same maker. The stated benefit is continuity across tools: what one agent learns does not have to be re-explained to the next one. The stated risk, which the makers explicitly invite feedback on, is where shared memory helps and where it becomes dangerous when more than one coding agent works on the same project. That open question is the reason access control and labelling sit in the shared layer instead of being left to individual agents to handle. Beyond text, the product includes optional local picture and PDF memory. Users can find pictures and PDFs by describing them, using Google's EmbeddingGemma 2. Memory is also time-aware: recall takes time into account, and every fact keeps a record of who wrote it and when, and the system tracks when each fact was true. The research behind the product describes related machinery, including a full cognitive memory taxonomy, adaptive forgetting, a memory lifecycle modelled as Langevin dynamics rather than hand-tuned decay, a retrieval metric drawn from information geometry, a distance metric that prefers full-fidelity embeddings over quantized ones, and a formal way to detect contradictions between memories. Governance is the V4 layer of the system. It enforces profiles, scopes, roles and role-based access, maintains a hash-chained audit trail, and offers verified erasure so that deleting a memory can be shown to have removed it. The first preprints describe local-first memory for multi-agent AI with a defence against memory poisoning through isolation and Bayesian trust scoring, and no cloud or LLM calls. Reliability claims are presented with unusual candour: the V4 paper opens with a negative result, reporting ten mechanisms that were implemented and reachable on a live call path yet ineffective at their final connection, plus two mechanical checks added to tell implemented, reachable and effective apart. Fault-injection testing of the write path covered eleven scenarios each run 200 times, holding 2,199 of 2,200 scoped properties. Measured properly, a governed write takes 11.0 ms, and most of that is described as the cost of durability rather than governance. The overall approach is local-first and evidence-led. The core memory path runs on the user's machine, so memory does not have to leave it. Memory is stored as facts rather than loose text; facts are ranked so that recency and relevance are respected, and old memories are forgotten. Everything is open source under AGPL-3.0, and the design is backed by four arXiv preprints published between February and August, covering local-first memory for multi-agent AI, the mathematical foundations of retrieval and forgetting, the cognitive taxonomy of the living brain, and the V4 governed memory system. According to the co-authors, each paper added something the product actually ships. Benefits stated or directly implied include a reduction in compounding errors across agent chains, because related-but-wrong context is labelled instead of silently promoted to fact. Users get continuity: one memory shared across Claude Code, Codex, Cursor, ChatGPT and other MCP or CLI agents, so context carries over between tools and sessions. They get provenance for every fact, the ability to know when a fact was true, and an audit trail of what happened. They get to enforce who can read what, and to demonstrate that data was erased. They also retain control over where the core runs, since it sits on their own machine, and they can inspect the implementation because it is open source. Concrete scenarios described in the content include running more than one coding agent on the same project and sharing memory between them; finding pictures and PDFs by describing them rather than by filename or folder; recalling a fact while knowing whether it is still true and which agent wrote it; and applying roles and scopes so that different people or agents see different parts of a shared memory. Another scenario is the handoff between agents, where the supported, related or no-answer label is passed along so the receiving agent does not treat an approximate memory as an answer. The makers also invite technical readers to examine the evaluation of the write path under fault injection, which speaks to teams that need reliability evidence before trusting governed memory in production workflows. The audience is developers and teams working with AI coding agents, particularly people running more than one agent on the same project, along with anyone building on MCP or CLI agents who needs shared, governed memory. Integrations named in the content are Claude Code, Codex, Cursor, ChatGPT, and any MCP or CLI agent. Google's EmbeddingGemma 2 powers picture and PDF retrieval, while Laya and Jev perform Answer Checks locally and online respectively. The launch is listed as Free and categorised under AI Coding Agents and LLM Memory, with topics including Open Source, Developer Tools, Artificial Intelligence and GitHub. The project is open source under AGPL-3.0, with code hosted on GitHub under Qualixar, and makers Arun Pratap Bhardwaj, Varun Pratap Bhardwaj and Garima Singh are listed on the launch. SuperLocalMemory's primary value proposition is memory an agent can be trusted with. By refusing to answer when the stored evidence does not support a claim, by keeping provenance and time attached to every fact, and by wrapping a locally running core in roles, an audit trail and verified erasure, it aims to make shared agent memory both useful and safe across the tools a team already uses.
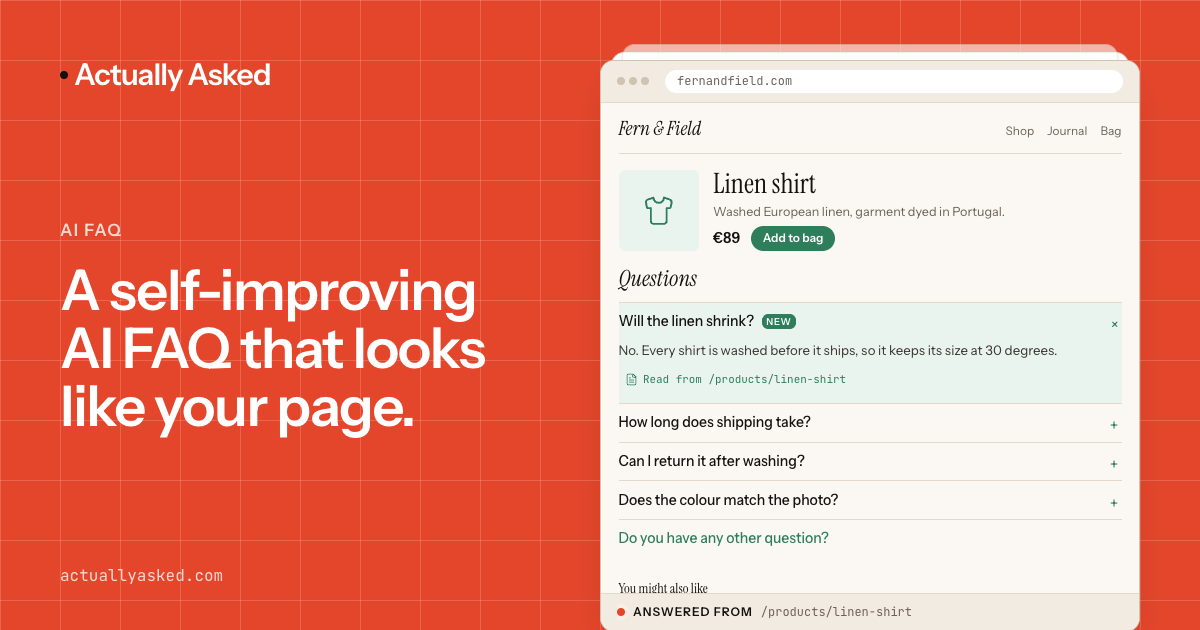
Actually Asked is an AI FAQ app for websites and Shopify stores. Rather than adding a floating chat bubble, it places a FAQ section directly inside your page, styled in your own fonts and colours, so it looks like part of the site. Visitors ask their question in their own words and receive answers taken only from your own pages, your help center and files you upload. The questions visitors ask most then join your FAQ on their own. The problem it addresses is a familiar one: businesses answer the same questions again and again by email. Sizing, shipping times, caffeine content, whether a jacket is truly waterproof, what a cancellation policy covers, what to bring to a first appointment. The answers usually already exist somewhere on a product page, in a help centre article or inside a PDF, but visitors either cannot find them or do not want to dig. Actually Asked is aimed at any site where people ask before they buy, book or sign up. The company puts the filter simply: if people email you the same questions again and again, it is for you; if nobody asks you anything yet, it is not. Three features carry the core experience. The first is an inline FAQ: a FAQ section that lives in your page rather than a chat bubble, and that is styled like your site. The marketing content shows the same widget rendered in the look of three different shops, a linen shirt store, a coffee roaster and an outdoor gear shop, each with its own typography and colours. The second is highlight to ask. Visitors select any sentence on the page and ask a question about it, which turns a specific line of copy, such as a sizing note or a care instruction, into an entry point for an answer. The third is the self-improving FAQ. The questions visitors ask most join your FAQ on their own, with nothing for you to approve. You can still edit, pin or remove any entry, and the product states that your edits are never overwritten. Answers are restricted to your own sources and nothing else. On the Sources page you connect your site, its pages, and on Shopify your products and store policies, which are read again every 7 days. You can add the address of a help center or knowledge base, and you can upload PDF or Word files such as size charts, care guides, manuals and price lists, including files that are not public. Answers can quote a file but never link to it. The onboarding view shows a site of 38 pages, a Shopify catalogue of 212 pages and four policy pages, all read at 04:00 with the next read scheduled for 04:00 the following day. The weekly gap report arrives as one email every Monday. It lists the questions asked most, the ones your pages do not answer, and what was added to your FAQ. A sample report shows 214 questions asked in the week, 87% of them answered and nine with no answer to write about. A separate leads feature captures visitors who leave an email address, so you have someone ready to reply to. Finally, an MCP integration lets you manage your FAQ by asking Claude, ChatGPT or another assistant, for example publishing FAQ entries through a tool call. Setup is presented as three steps. First, you add your domain, plus your help center or PDF and Word files if you have them; those sources are read, private files included, and your first FAQ entries are written from them. Second, you paste two lines, a div carrying your site key and an async script tag from the Actually Asked CDN, and the FAQ appears where you put it; on Shopify you add it as a block in the theme editor instead. Third, visitors ask, and your FAQ grows. The distinguishing choices are the absence of a chat bubble, the tight sourcing rule that answers come only from your pages, and the fact that popular questions are promoted into the FAQ automatically rather than waiting on a human editor. The outcome the product describes is a FAQ that looks like yours and learns from visitors. Popular questions are answered once and added permanently, so the same email does not need to be written twice. Because answers are grounded only in your own material, the reply a visitor sees reflects what you already publish. The Monday report gives a regular view of the questions your pages fail to answer, which points at content worth writing. Leads are collected for follow-up, and the whole FAQ can be maintained from a dashboard, the Shopify admin or an AI assistant. Four use cases are documented. Online stores, including Shopify, WooCommerce, Squarespace and custom shops, use it for product and policy questions such as whether a size runs small. SaaS and apps use it on pricing pages and documentation for plan and "does it do X" questions, illustrated by a per-seat pricing example where an annual discount question is answered from the /pricing page. Travel and hospitality businesses such as hotels, rentals and tours handle check-in, cancellations and what is included, illustrated by a room booking page answering whether breakfast is included from the /rooms page. Services and clinics, including agencies, clinics, studios and coaches, cover booking, pricing and what to expect, illustrated by a first-visit page that answers what to bring. Actually Asked was built first for Shopify stores but works on any website whose visitors have questions before they buy, book or sign up. Integration paths include a Shopify theme block, a WordPress Custom HTML block or footer script, a Webflow Code Embed, a Framer Marketplace plugin or pasted component, a Squarespace Code block, and static HTML, React, Next.js or custom templates. There is also a free gap-finder tool to find FAQ gaps and an MCP route for managing the FAQ through Claude or ChatGPT. Pricing starts free with 50 AI answers a month on one site, then $12 a month; every plan includes unlimited team members, and you pay for the answers you use and the sites you run. Actually Asked replaces the chat bubble with something more durable: a branded, inline FAQ that answers from your own sources and quietly grows with the questions visitors actually ask. It is free to start, live on your site in about ten minutes, and aimed at any business that keeps answering the same question by email.
withHuman is the approval layer for AI agents. It lets you put your most consequential agent actions behind human approvals so that your agents can do real work. Its core behaviour is interception: every tool call an agent makes is held before it runs, checked against your rules, and either approved or denied automatically or routed to the right person on your team. withHuman is framework-agnostic, open source and built on open standards, and it works across Claude Code, Codex and agents built with LangGraph, Pydantic AI and more through an open protocol called AAP. Crucially, it gives you one set of rules for every agent your company runs. Agents are increasingly trusted with actions that carry real consequences: refunding a customer, paying an invoice, merging a pull request, rolling back a production deployment or sending a marketing campaign. Once such a call is made, it is often impossible to take back. The site describes the purpose of withHuman as covering "the actions you can't take back" by letting agents draft everything while shipping nothing until someone accountable has looked. Without a control layer, teams must choose between blocking agents from useful work entirely or letting them act unsupervised. withHuman exists to remove that trade-off, so agents can be put to work accountably rather than being held back. Every tool call, whatever the agent. Each tool call is intercepted by AAP, the Agent Approval Protocol, and sent to withHuman for approval. If the agent supports AAP, withHuman just works. Concretely, the product ships SDKs for LangGraph, CrewAI, Mastra and other agent frameworks, hooks for Claude Code, Codex and other coding agents, and the open Agent Approval Protocol for your own agents. In the worked example, a support agent's stripe.refund call is held by withHuman before it reaches Stripe, so nothing leaves the agent runtime until a decision has been made. This interception layer is what makes everything else in the product possible: because the call is paused rather than executed, withHuman can inspect it, apply policy, notify a person and only then let it run. No approval fatigue. The site is explicit that approval fatigue is the enemy, and the way to avoid it is to write policy rules that approve or deny routine requests automatically, sending only the tough stuff to humans. An approval pipeline can express conditions on the agent, the tool, the arguments and the agent context; an AI judge handles calls that rules can't describe; and webhooks hand decisions to your own policy service. In a live example pipeline, kubernetes.pods_list is approved by a rule for read-only tools, an email reply is approved by an AI judge as a routine support reply, db.drop_table is denied by a rule against schema changes, and a vendor.pay call over the team budget is sent to a person through a webhook, meaning three of four calls were decided without a person. The refund example shows the same idea in miniature: refunds under $20 are automatically approved, and anything more asks a human. Escalation paths decide which requests go to which team or person. You write rules that route by agent, tool, arguments or team; teams set their own escalation order and on-call flows; and requests escalate when nobody answers in time. In the illustrated example an under-$1,000 refund goes to the support team, a $2,400 refund goes to finance lead Sam Alvarez, and an out-of-hours request goes to Priya Nair, who is on call. Reviewers are then met where they already work: requests arrive in Slack and Discord, in iPhone and Android apps with push, and by email, text message and WhatsApp, so each reviewer's notification rules pick the channels. Every decision is kept on the record. withHuman maintains an append-only audit log run history: each entry records the request, the decision and the reviewer, such as db.delete_rows approved by d.chen, stripe.refund approved by s.alvarez with a note verifying with finance, k8s.apply denied by m.okafor, and crm.update_contact approved by d.chen. The log keeps reviewer identity on every row and the full request with each decision, so when someone asks who approved a given action, the answer is available. Overall, withHuman acts as a pipeline between the agent and the tool it wants to call. In the site's step-by-step example, a customer asks for a refund and the support agent decides to issue it; the agent's tool call is intercepted and held by withHuman before it reaches Stripe; the rules check the call and either approve or deny it automatically or ask a human to look; the request is sent to the Payments team, where Chris is on call; the human is notified on their preferred platform; the human sees the tool call and request context and decides; and the approved refund finally reaches Stripe while the agent carries on. The distinctive architectural choice is that integrations are made with AAP rather than with withHuman, so agents and frameworks wait on human decisions through an open spec, and you can swap providers without rewriting a single agent. The benefit is straightforward: withHuman lets teams put agents to work without giving up accountability. Because routine calls are decided automatically by rules or an AI judge, reviewers are not buried in approvals. Because risky calls are routed to the right person together with the full request context, decision-makers see exactly what is being proposed before it happens. Because every request, decision and note is kept in an append-only history with reviewer identity, the question of who approved something always has an answer. And because the protocol and the core are open source, teams avoid lock-in and can leave whenever they choose, running the queue, audit trail and web UI on their own infrastructure or letting withHuman host it. Use cases centre on consequential actions: an AI SRE agent requesting a kubernetes.rollout_undo to roll payments-api back to v2.41.0 after the 5xx rate crossed 2%; coding agents running Bash commands; customer support agents issuing stripe.refund calls; finance and accounting agents running bill.pay; sales agents using docusign.send; marketing agents sending campaign.send; and personal assistants creating calendar events with calendar.create_event. In each case the pattern holds: the agent prepares the action, withHuman pauses it, a rule or a person decides, and only then does the action execute. withHuman is aimed at teams running agents in production across engineering, support, finance, sales, marketing and SRE functions; the example reviewers include a Payments team member who is on call, a finance lead and an SRE. Integration is broad. Installing the CLI connects every supported agent on your machine, covering Claude Code, Codex, OpenClaw, Pi, Hermes and DeepSeek, and the supported list also includes the MCP gateway, LangGraph, Deep Agents, Pydantic AI, OpenAI Agents, Claude Agent SDK, Google ADK, CrewAI, AI SDK, Mastra and an HTTP API with POST /api/aap/v1/requests. withHuman is open source with a hosted version, and the Product Hunt listing notes a promotion giving three months of the Scale plan free with the code PRODUCTHUNT. In summary, withHuman is the approval layer for AI agents: it intercepts tool calls, applies automatic policy for routine actions, escalates the consequential ones to the right accountable human, records every decision, and does so through an open, self-hostable protocol that avoids lock-in. Its value proposition is simple and stated plainly on the site: put your agents to work, accountably.
Nostaliga is an iPhone and iPad app that turns your listening history into a personal timeline. Pick any song and see the day around it: your photos, places, runs, check-ins, shows and posts. The app brings your music, photos, workouts, walks, the places you have been, and the movies and shows you have watched into one timeline, so that a single track becomes an entry point into a period of your life rather than just a piece of audio. Nostaliga is made for anyone who has ever heard a song and been pulled straight back to a specific time and wanted to see that moment again, the photos that were taken, the route that was ridden, the place that was checked in to, and not only feel a vague sense of nostalgia. The app grew out of a very specific memory. The maker describes hearing "1-800-273-8255" by Logic and being instantly back in 2017, the first year he was cycling, doing long rides with that song on repeat. The song remembered those rides better than he did, but the routes and the photos from them were scattered across Strava, his camera roll and Last.fm. That fragmentation is exactly the problem Nostaliga sets out to solve. The music that triggers a memory lives in one service, the photographic evidence lives in another, the workout data in a third, and the check-ins, shows and social posts somewhere else again. Nostaliga anchors all of those threads to listening history, so instead of hunting through several apps for the same day, you can start from the song and let the app reassemble the context around it. The central interaction is deliberately simple: pick any song and Nostaliga shows you the day around it. The app looks through your listening history and brings back the photos, places, rides, walks and moments from the times you played that track before. Photos, places, runs, check-ins, shows and posts all sit in the same view, arranged around the music rather than around a date. This matters because most memory tools ask you to remember a date or scroll a photo library; Nostaliga starts from the thing that actually triggered the memory. The song is the index, and everything else, where you were, what you photographed, what you were doing, hangs off it. Nostaliga also includes an On This Day experience that works across the years. Instead of looking only at a single song, you can go back to the same date in earlier years and see what belongs to it. That gives the timeline a second axis: one direction from a song into a day, and another from a calendar date back through the years. Together they turn the app into something closer to a personal archive with two ways in, so the memory can be found whether you remember the music or the date. The app draws on a broad set of sources so the timeline is not limited to music. It works with Apple Music and Last.fm for listening history, Photos for imagery, Apple Health and Strava for runs, rides, workouts and walks, Swarm for check-ins, Trakt for the movies and shows you have watched, and Calendar for events. If your listening history does not live in those services, you can import your Spotify listening history, and you can also import your Twitter, Instagram or Facebook archives. Each of these sources contributes a different kind of evidence about a day, where you went, what you did, what you watched, what you shared, and Nostaliga's job is to line them up against the music. Underneath, Nostaliga's approach is defined as much by what it does not do as by what it does. There is no account, and there is no analytics or tracking. Your timeline is built and stored on your device, so the assembled record of your listening, photos, places and activity stays with you instead of being uploaded and held by a service. That makes the app a local, personal archive rather than a social or cloud product. The result is a timeline you can explore without signing up, without a profile, and without the sense that your memories are being collected by someone else. The benefits follow from that design. A song stops being only a song and becomes a way back into a particular stretch of life, the year you were cycling, the city you were in, the film you were watching that week. Because the sources are gathered rather than scattered, you do not have to remember which app holds which fragment; the timeline does it for you. And because the listening history is the organizing principle, the memory is triggered by the same thing that would have triggered it in real life: hearing the track. Finally, the on-device, no-account model means the value of the archive is not tied to a subscription or a login. Concretely, Nostaliga is used when a song brings back a period and you want to see it rather than only recall it. You might pick a track that was on repeat during a first year of cycling and use it to pull up the routes and photos from those long rides. You might use On This Day to revisit the same date in earlier years and see what you were listening to, where you checked in and what you were watching. You might start from a film or show in Trakt and work back to the music of that month, or start from a check-in in Swarm and see what was playing. If your history is spread across Apple Music, Last.fm, Strava, Photos and social archives, importing those sources is the first step in building the timeline you then browse by song or by date. Nostaliga is an iOS app for iPhone and iPad, listed under iOS, Music and Photography. Its connected sources include Apple Music, Last.fm, Photos, Apple Health, Strava, Swarm, Trakt and Calendar, along with imports for Spotify listening history and Twitter, Instagram or Facebook archives. It is free to use. Because it requires no account and performs no analytics or tracking, there is nothing to sign up for before you begin: the timeline is assembled and kept on your own device. The takeaway is that Nostaliga treats your listening history as the thread that ties your memories together. By combining music with photos, places, runs, check-ins, shows, posts and calendar events in one on-device timeline, and by letting you enter it either from a song or from a date, it makes rediscovering the days behind your favorite songs a matter of picking a track and seeing what comes back.
Afterparty is an AI agent product that does the work that comes after a meeting. Your note taker records the call and hands over the transcript, and Afterparty finds every action in it and writes the draft that action calls for: the recap email, the Slack message, the calendar invite, the CRM update. It works on top of the note taker you already use rather than replacing it, and it draws context from your email, calendar and Slack so each draft goes to the right person in the right thread. It is built for anyone who leaves a meeting holding a list of follow-ups, and its purpose is to turn that list into drafts you simply approve. The product is framed around an everyday problem: note takers give you a list, and Afterparty does the list. Recording a call and producing a tidy set of action items is the first half of the work. The second half — writing the recap to the client, posting the update in Slack, sending the invite for the next session, moving the deal in the CRM — is still manual, and it is where meeting momentum is usually lost. Afterparty is aimed squarely at that second half, so the follow-through happens right when the meeting ends instead of waiting for someone to find the time. The first thing Afterparty does is catch every action, even the ones said in passing. From a sample kickoff transcript it pulls out commitments such as sending a list of store managers, sending a recap and pilot proposal with pricing by Friday, writing up a one page plan for leadership, setting up a sandbox account, checking with Dana about onboarding capacity, and booking a room for the prep session. If you do not have a note taker, you can paste a transcript or upload a .txt, .vtt or .srt file instead, so the same workflow applies to any meeting you can capture. Context is what makes the drafts usable. Before writing, Afterparty reads your email and Slack so each draft goes to the right person in the right thread. The example on the site shows an action to "Send Priya the recap and the pilot proposal" turning into a draft addressed to Priya Shah with the subject line "Pilot recap and proposal," written in your voice and referencing the twelve-week pilot across Harbor Street, Eastgate and Millbrook, the priced proposal coming by Friday, the one page plan, and the kickoff workshop on October 14. Afterparty also skips what is already done and asks when it needs something. For an action to send an NDA, it searches Gmail for "in:sent NDA Kestrel" to see whether the document has already gone out. For a one page pilot plan in Notion it raises a question — "What budget should the plan assume?" — with an answer field, plus "Answer and draft" and "Skip" options, so you can supply the missing detail or drop the action entirely. Nothing happens without you. Every action waits in Afterparty, and approving an email simply places a draft in Gmail or Outlook — you still press send. One click moves each approved item into the right app, and the agents move on to the next one. The product also learns from your edits. When you approve, edit or dismiss a draft, Afterparty notes who people are and how you like things written, and the next meeting's drafts start from that. A visible memory panel in the example captures details such as "Tom Becker: handles the sandbox and anything technical" and "You sign off with 'Talk soon, Alex'," and the rewrite example shows a bloated opening being trimmed down. You can read, change or clear this memory in Settings. Once your recorder is connected, the whole flow runs after every call. You connect the recorder a single time, every transcript arrives on its own, and the agents get to work the moment you hang up. Supported meeting tools include Granola, Fireflies, Fathom, Zoom, tl;dv, Google Meet and Gong. Under the hood, Afterparty's agents are strictly read-only. They look at your email, calendar and CRM for context, but they cannot send, post or change anything. Reading is also targeted: for each action the agents look up only what that draft needs, such as recent threads with the people from the meeting, your calendar around the dates that came up, or the CRM contact — and they only read while a meeting is being drafted. Drafts are written in the language the meeting was held in. Privacy is treated as a core promise. Your meetings, drafts and app data are never used to train AI models, and no other user can see them. Deleting your account in Settings removes everything with it: meetings, drafts, memory and app connections. The full details live in the privacy policy. The benefit is speed and completeness rather than another tool to manage. Recap emails, Slack posts, invites and CRM notes are ready before you are back at your desk, written with context pulled from your own tools, and every one of them waits for your approval. You keep the final say on every send, post and update. Use cases described on the site include sales and client meetings, where a kickoff call generates a recap email, a priced proposal follow-up, a one page plan for leadership and a CRM stage update in HubSpot; internal coordination, where an action becomes a Slack message asking a colleague about onboarding capacity; scheduling, where a follow-up session turns into a calendar invite; and document work, where an action to produce a one page plan is drafted in Notion. Each of these is drafted from the transcript plus the context already sitting in your inbox, calendar and chat. Afterparty connects to meeting recorders, email, calendar, chat, CRM and project tools, listing Gmail, Google Calendar, Outlook, Slack, Microsoft Teams, HubSpot, Salesforce, Attio, Notion, Linear, Jira, Asana, ClickUp, monday.com, Google Docs, Google Drive, Confluence, OneDrive, Granola, Zoom, Google Meet, Gong, Fireflies, tl;dv, Fathom, Zendesk, Intercom and GitHub, plus "many more." Pricing starts free at $0 a month for email and calendar drafts and five meetings a month with no credit card. Pro is $29 a month (or $290 a year, saving $58) for sends to every app, auto import, learning how you write, and 20 meetings a month. Max is $79 a month (or $790 a year, saving $158) for frontier models, your own instructions, six months of context and 60 meetings a month. Prices are in USD, and every plan includes the approval inbox and memory you control. Afterparty is, in short, the second half of the meeting. Your note taker delivers the list; Afterparty turns each item into a finished draft in the right app, with the context to send it to the right person, and leaves the final click to you — so the actions from a call get done while the call is still fresh.
Daddy Issues is a companion app for dads, described on its own site as a way to "think ahead" and "fight less." At its core it delivers a weekly family briefing, built by AI around a dad's actual week. The product is aimed squarely at fathers who are involved, who care, and who already do a lot, but who still find themselves reacting instead of anticipating. Its stated purpose is to help dads stay one step ahead each week, before anyone has to remind them. To do that, it connects the elements that make up family life — kids, calendar, responsibilities and tasks — and surfaces what is coming up, what might be missing, and what is worth handling now. The problem Daddy Issues addresses is not a lack of effort or intention — the site says so directly. The failure point it names is timing. A dad may be present and helpful, yet still hear "Did you think about this?", still find out about things too late, and still end up reacting rather than anticipating. The app draws a sharp line between helping and owning: "If someone has to remind you, you're not ahead. You're catching up." It lists the roles a dad does not want to play — the one who gets reminded, the one who reacts late, the one who "helps" but doesn't lead — and sets the opposite as the goal: being the one who already handled it. Because that gap between effort and timing shows up as last-minute stress, repeated reminders and small disagreements, the product treats planning ahead as the thing worth fixing. The central feature is the weekly briefing. It is presented not merely as a summary but as an AI that "connects the dots you don't see." Each week it lays out what's coming up, what actually matters, what the AI spots early, and what to handle now. The briefing is built around the user's real week rather than a generic checklist, and it is designed to be acted on immediately: the user can turn briefing items into actions and add them to their calendar, then be done. The interface example on the site shows a week for Monday, April 14 containing a kindergarten trip on Thursday with a snack needed, a doctor follow-up that is overdue, and a birthday on Sunday with a gift still missing, summarised as "3 items need attention this week." A second core capability is that the app learns how a family works. As the user creates tasks, the AI understands patterns and begins anticipating what matters earlier. The stated result is that things stop slipping — including things the user had not been tracking before. This is a meaningful distinction from a static reminder list or a shared calendar: rather than depending on the dad to enter every future obligation, the system uses the tasks and routines he does create to anticipate what is likely to matter next. Over time that shifts the dynamic from catching up on what was already missed toward surfacing it while there is still time to act. The site describes a deliberately short path to value in three steps. First, connect your basics: calendar, kids and routines. Second, get your weekly briefing, which the AI builds around your actual week. Third, act early, before things pile up. The onboarding is positioned as lightweight — "Takes 1 minute · No setup stress" — with calls to action to "Start being ahead this week" or to "Show me my first week." The emphasis throughout is that the product should fit into an already busy life rather than adding another system to maintain; the dad supplies the basics, and the briefing carries the ongoing thinking work. Daddy Issues frames its approach as owning rather than helping. Its origin story reinforces that: it didn't start as an app but as a personal fix, built by a dad who was tired of being behind — trying to keep track of everything, still missing things, still being reminded. He built something that helps you stay ahead, described honestly as "not perfectly. But consistently." That combination — AI that connects the dots across kids, calendar, responsibilities and tasks, plus a weekly briefing rhythm tied to a real calendar week — is the product's distinctive method. Rather than issuing a stream of constant notifications, it consolidates anticipation into one recurring habit. The promised outcomes are relational as much as logistical: less stress, fewer reminders, more trust. The site sums this up by saying the user doesn't just help more — they take ownership. Read out, those benefits follow from the mechanics: because the briefing surfaces what is coming before it becomes urgent, there is less last-minute scrambling; because the dad is no longer the person who needs reminding, the recurring friction of who remembered what is reduced; and because he acts early, he is seen to be ahead rather than catching up. The tagline "Think ahead. Fight less." captures the same two-sided promise — better preparation and calmer family life. The example week on the site doubles as a set of concrete use cases. A kindergarten trip on Thursday surfaces early in the week, with the detail that a snack is needed — exactly the kind of small item that is easy to discover the night before. A doctor follow-up is flagged as overdue, turning a vague worry into a specific action. A birthday on Sunday is flagged because the gift is still missing, giving the dad lead time to sort it out. Elsewhere the site asks the question "backup clothes for daycare?" — another everyday logistical detail that matters only if it is handled before the morning it is needed. In each case the pattern is the same: the briefing names the item, then the dad turns it into an action and adds it to his calendar. The target user is explicit: dads. The site describes them as involved, caring and already doing a lot, and notes the product is "built for dads - by dads" and "built from real life. Made for yours." The expected starting task is to connect basics such as calendar, kids and routines. On privacy, the site states that it uses anonymous statistics to see how the site is used, with no ad tracking and no profiles, and that essential login storage always stays on, with a linked privacy policy at daddyissues.app/privacy. The product is accessible on the web at daddyissues.app, with "Log in" for existing users and a "Start being ahead this week" path for new ones. In short, Daddy Issues is not trying to make dads try harder; it is trying to change their timing. By connecting kids, calendars, responsibilities and tasks, learning from the tasks they create, and returning a single weekly briefing covering what's coming up, what matters and what to handle now, it aims to replace reacting with anticipating. The result it promises is less stress, fewer reminders and more trust — and the shift from helping out to taking ownership. For a dad who is already doing a lot and still hearing "Did you think about this?", that is the whole proposition.
Navige is a governed layer that sits between your AI agents and everything those agents pay for — the language models, tools and metered APIs each run depends on. The stated promise is straightforward: every run gets cheaper and faster, with the same result. Navige intercepts the calls your agents make, decides whether the step really needs the model that is about to be used, reuses answers that are still valid, trims oversized context and tool payloads, and blocks repeated failures before they add to the bill. It is built for teams running programmatic AI workloads in production — agent developers working with frameworks such as LangChain, LangGraph, CrewAI, OpenAI Agents, MCP and Agentforce, and the organisations paying for the models behind them from Anthropic, OpenAI, Google, AWS Bedrock, Mistral and Meta Llama. The problem Navige addresses is that AI agents spend money continuously while they work, and most cost tooling only reports on that spending after the fact. The site frames the failure modes plainly: runs that never finish, where agents keep running without producing an output; big model, small task, where a step is answered by far more intelligence than the outcome required; chasing, not remembering, where the same work is redone instead of reused; one budget, many agents, where multiple agents touch the same work; and misread, then paid for, where an incorrect result still costs money. As the site puts it, everyone else shows you what the run cost after it has run, while Navige changes the step before it runs. That distinction matters because the bill is effectively decided before the dashboard ever sees it — by the routing, context and tool-call decisions taken while the agent is still working. The first two cost-control mechanisms are Cache & Reuse and Context trimming with tool payload capping. Cache & Reuse is described as “Never Pay Twice”: instead of paying for another model call or tool call, Navige reuses a verified answer when it is still valid. This targets the repetitive portion of agent work — the same conclusion reached the same way many times — which the site says carries the most opportunity for savings. Context trimming and tool payload capping is summarised as “Only Pay For What’s Used”. Before sending the next request to the model, Navige limits oversized tool results and trims accumulated history, so the request contains what the result is actually built from rather than everything that has piled up. Together these two mechanisms attack the two most common sources of wasted tokens: paying twice for information you already hold, and paying to transmit context that no longer contributes to the answer. The second pair of mechanisms is Loop & failure guard and Smart routing. The loop and failure guard is designed to “Stop Runaway Jobs” — it blocks repeated failures before another call adds to the bill, which directly addresses agents that keep retrying indefinitely and never produce an output. Smart routing is described as “The Right Model, once it’s earned”, choosing a model based on the complexity of the task. The underlying idea is labelled Sufficiency Intelligence: send suitable requests to smaller models, and if the system is unsure, keep your originally chosen model. Crucially, the site is explicit that this is not discounting — where a step needs a frontier model, sufficiency keeps it there. Nothing about the approach proposes a cheaper answer to the same question; it proposes the same answer, reached at the level of intelligence it actually needed. Beyond per-call optimisation, Navige adds operating controls. According to the product description, teams can set budgets, catch runaway loops and approve sensitive actions before they execute. Cost and savings are reported by job, with estimates clearly labelled so that measured figures are never confused with projections. Changes can be previewed before the corresponding controls are switched on, which lets teams see the effect of a routing, caching or trimming policy before it governs live traffic. One stat on the site highlights that tool calls are checked against your rules before they run, not flagged afterwards — governance is positioned as preventative rather than retrospective. Architecturally, Navige is a single governed layer. Your agents sit on one side and the models they pay for sit on the other; you plug both in once and every call runs through that layer. For platform connectivity the site says you change one line, and your frameworks, keys and providers stay exactly as they are. Navige also includes a sufficiency calculator: you enter monthly programmatic AI spend (models, agent traffic and metered AI tools, excluding employee seat licences) and describe whether most of the work is repetitive, mixed, complex or unknown, and which behaviours sound familiar — premium models used by default, large prompts or context, retries, loops or repeated calls, paid tools, search or data APIs, or multiple agents touching the same work. The result is deliberately presented as a range, never a single number, and the page is clear that the calculator estimates opportunity while Navige measures reality once connected. The measurement approach is the part that guards against silent quality loss. Connected, Navige leaves a slice of your jobs running untouched and compares the two, so the difference is observed rather than assumed. Results are checked as well as cost: a step that became cheaper and started being wrong is reported as a failure, never as an opportunity taken. For users, the stated outcome is the same destination with no detours — same result, smaller bills, and runs that get lighter in four distinct ways while your existing frameworks, keys and providers remain unchanged. The site also reports that tool calls are governed before they run, that AI spend is managed priced to the millionth of a dollar and live, and that over 51 agents are already connected. Use cases follow directly from the failure modes and mechanisms described. Repetitive workloads benefit most from Cache & Reuse, since the same conclusion reached the same way many times can be served from a verified answer. Workloads with large prompts or heavy context benefit from context trimming and tool payload capping. Multi-agent setups where several agents touch the same work, or where several agents draw on one budget, benefit from the governed layer and budget controls. Teams suffering retries, loops or repeated calls benefit from the loop and failure guard. Workloads that pay for search, data APIs and other metered tools benefit when a held answer is still good enough. And any team that wants a human approval gate before sensitive actions run can use that control. Navige targets developers and organisations running programmatic AI at scale. Supported frameworks and platforms listed on the site include LangChain, LangGraph, CrewAI, OpenAI Agents, MCP and Agentforce, and the models span Anthropic, OpenAI, Google, AWS Bedrock, Mistral and Meta Llama. Onboarding is described as a one-line change that leaves existing frameworks, keys and providers untouched. Navige is positioned to sit between your agents on one side and the models they pay for on the other, with the calculator inviting teams to compare an illustrative opportunity estimate against the measurement Navige produces once connected. Pricing detail is not spelled out on the pages captured here beyond the statement that Watchtower is free forever, plus a dedicated pricing page and an enterprise option listed in the footer. Navige’s core proposition is sufficiency rather than frugality: sufficiency isn’t about using less AI, it’s about using exactly enough. By sitting in the path of every agent call — routing, caching, trimming, guarding and governing — it aims to cut AI agent and LLM spend without changing the output, and to control runaway spending before the bill is written rather than explaining it afterwards.