Category Focus/categories/code-assistant
Code Assistant AI Tools
Discover and compare the best code assistant AI tools and software. Browse 89+ curated tools with reviews and rankings.
Projects tracked
89
Sort mode
RECENT
Page
1
Discover and compare the best code assistant AI tools and software. Browse 89+ curated tools with reviews and rankings.
Projects tracked
89
Sort mode
RECENT
Page
1
OpenCode is an open source AI coding agent that helps you write code in your terminal, IDE, or desktop. The project describes itself simply as an open source agent, and its stated purpose is to sit inside the environment where developers already work so that an AI assistant is available without leaving that environment. It is available as a terminal interface, a desktop app, and an IDE extension, and the Product Hunt listing notes it can also be used as a web app. Free models are included out of the box, or you can connect any model from any provider, including Claude, GPT, Gemini and more. That combination of an open source codebase and flexible model access is the core of what the product offers. The problem OpenCode addresses is visible in how developers currently work with AI coding assistants. Most assistants tie you to a single vendor's models, a single interface, or a single subscription, and the site notes that teams and individuals end up worrying about inconsistent performance and quality across providers. OpenCode takes a different route: because it is open source, it can be inspected and self-directed, and because it connects to many providers rather than one, the choice of model stays with the developer. The site also highlights a privacy dimension, stating that OpenCode does not store any of your code or context data so that it can operate in privacy sensitive environments. Taken together, these choices reflect a demand for coding agents that are transparent, portable across providers, and safe to run on code that cannot leave a controlled environment. The first major capability group in OpenCode is model access and provider choice. The site states that free models are included and that you can connect any model from any provider, including Claude, GPT, Gemini and more. Beyond those named providers, OpenCode supports any model across 75+ LLM providers through Models.dev, and that list includes local models, which matters for developers who want to run inference on their own hardware. Two subscription integrations are called out explicitly: you can log in with GitHub to use your Copilot account, and you can log in with OpenAI to use your ChatGPT Plus or Pro account. That means an existing AI subscription does not go to waste, and you avoid being locked into one vendor's model lineup. The second capability group concerns where and how the agent runs. OpenCode is described as available as a terminal interface, a desktop app, and an IDE extension, and the Product Hunt description adds that it is available as a web app as well. The site summarizes this under "any editor." It is LSP enabled, meaning OpenCode automatically loads the right Language Server Protocols for the LLM, which gives the model accurate, language-aware context about the code it is working on. It also supports multi-session use, so you can start multiple agents in parallel on the same project, and share links, which let you share a link to any session for reference or to debug. Together these features make OpenCode fit into real workflows rather than a single chat window. The third capability group is around privacy and model quality. On privacy, the site is explicit: OpenCode does not store any of your code or context data, which is what allows it to be used in privacy sensitive environments, and a dedicated privacy page for enterprise use is linked. On model quality, OpenCode offers Zen, described as access to a handpicked set of AI models that OpenCode has tested and benchmarked specifically for coding agents. The stated benefit of Zen is that you do not need to worry about inconsistent performance and quality across providers, because you are using validated models that are known to work well for agentic coding. Between the privacy stance and Zen's validated models, OpenCode is aiming at two of the most common hesitations about adopting a coding agent. Overall, OpenCode works as an agent that lives in your development environment and talks to whichever model you choose. Installation is handled through common package channels — the site shows a curl install command and lists npm, bun, brew, paru and yay as installation options — so the setup step fits into whatever toolchain a developer already uses. Once running, the agent loads the appropriate LSPs for the language in front of it, which serves as the context layer for the LLM. Model routing is handled through Models.dev, the provider directory that gives OpenCode access to 75+ LLM providers, including local models, while Zen sits alongside that as a curated, benchmarked set of models chosen specifically for coding agents. The same agent is then reachable from a terminal, a desktop app, an IDE extension, or the web, which means the underlying approach stays consistent even when the surface changes. The benefits OpenCode claims are backed by adoption numbers on the site. It reports over 208,000 GitHub stars, 950 contributors, and over 13,000 commits, and states that OpenCode is used and trusted by over 16 million developers every month. For an individual developer, the practical benefits are the freedom to pick a model and provider without rewriting a workflow, the ability to reuse an existing Copilot or ChatGPT Plus/Pro subscription, and the option to keep everything local or self-hosted when working with sensitive code. For teams, the privacy stance — no storage of code or context data — is a way to adopt an AI coding agent in environments where sending code to an unknown third party is not acceptable. Concrete use cases follow directly from those capabilities. A developer can run OpenCode in the terminal to write and modify code without leaving the command line, or install the IDE extension to work inside their editor. With multi-session support, they can start several agents in parallel on the same project — for example, one working on a frontend task while another handles a backend refactor. When something goes wrong, they can generate a share link to any session and send it to a colleague for reference or debugging. Developers with an existing GitHub Copilot or ChatGPT Plus/Pro account can log in and use that subscription instead of paying for a separate one, and teams operating in privacy sensitive environments can use OpenCode because it does not store code or context data. OpenCode is aimed at developers and development teams: anyone who writes code and wants an AI agent inside their terminal, IDE, desktop, or browser. Its integrations are listed plainly — GitHub Copilot accounts via GitHub login, ChatGPT Plus and Pro accounts via OpenAI login, and 75+ LLM providers through Models.dev, including local models. It installs via curl, npm, bun, brew, paru, or yay. The site states that free models are included and that OpenCode is open source, and it links to a privacy page for enterprise users, but it does not publish specific pricing tiers or plan details in the content provided here. In short, OpenCode is an open source AI coding agent built around three ideas: an agent that meets you in your terminal, IDE, desktop, or browser; open access to models from any provider, including free and local ones; and a privacy first design that does not store your code or context data. Backed by a large open source community and a curated set of benchmarked models through Zen, it gives developers a flexible, transparent alternative to a single-vendor coding assistant.
Codemind is a build service that a coding agent calls directly. Instead of writing code itself, your agent hands Codemind a task — a title, the acceptance criteria and the stack — and Codemind writes the code, tests it against those criteria and returns the files. A build that passes is counted as one verified build; a build that fails returns an error code and no charge. It is built for developers who already work inside coding agents such as Claude Code, Cursor, Codex and OpenCode, and who want the writing, testing and fixing to happen somewhere other than their own session and plan. Everything is designed so the agent's plan goes on planning and review, while Codemind handles the build. Coding agents typically operate in a write, run and fix loop. Every attempt, including the ones that fail, consumes tokens or plan quota, and the trial and error fills up the agent's context. While the agent is busy running that loop, it cannot move on to the next task. Codemind addresses this by moving the writing, testing and fixing to its own servers, off your plan. Rather than paying for every attempt whether the code works or not, you pay for verified builds only: a build that passes tests written from your acceptance criteria. Codemind states that it has not measured how total cost compares with an agent writing the same code itself, and that it will publish the method when available. The workflow has three steps. First, your agent sends a task containing a title, the acceptance criteria and the stack; if the criteria are too vague to test, Codemind says so before it starts. Second, Codemind writes the code and tests it against your criteria before anything comes back. Third, the files return to your agent, which writes them into your project. A build that passes counts as one verified build. The design intent is that you stay in your coding session while the writing, testing and fixing happen on Codemind's side, off your plan. Every build comes back with its result. You see whether it passed and what you were charged. A passing build produces a build receipt — for example, a task such as checking the webhook signature on POST /events in a TypeScript stack, sent from Claude Code over MCP — showing that the code was written, that it was tested against your criteria, how many files were returned and what you paid. A build that fails returns an error code and no charge; code that fails its tests does not reach your agent, so your agent can retry or do the task itself. Builds inside your free allowance cost nothing either way. Pricing is a flat rate charged only for code that works, with no seats and no tokens to count. The Free plan costs $0 and requires no card: it includes 100 verified builds in your first month, then 50 every month, with up to 2 builds at once and 20 an hour. Pay as you go costs $0.10 per verified build for builds beyond the free allowance, drawn from a prepaid balance you top up — although paid top-ups are coming soon and are not available yet. A Custom plan, by contact, offers a negotiated volume rate, reserved capacity and support. A Pro plan is coming soon at a price to be announced, adding Swarm and higher limits of up to 10 builds at once; Ship is also coming soon. If you use up the free allowance, new builds are refused with a clear message until your next month starts, and nothing is charged unless you have added a paid balance. Your free allowance counts verified builds only. Setup is designed to be run by the agent itself. A button copies a one-line prompt — read and follow the setup steps at codemindhq.dev/agent-onboarding/SKILL.md — that you paste into your coding agent. The agent adds the Codemind server to your host and asks you to reload it, and a free account is created when it connects. You then restart your agent and delegate your first task. No script runs and no key is stored, though if you restart your host, Codemind starts a new free account. You can also sign up yourself in the dashboard. If you already have a key, you can add the server by hand with a claude mcp add command that keeps your key out of the config file. Codemind's MCP endpoint is https://api.codemindhq.dev/mcp and it needs no API key; agents are instructed to call get_usage_guide before their first build_feature. The stated benefits fall into productivity and performance. On productivity, a coding model normally works through one task at a time, whereas Codemind builds run side by side on its servers — 2 at once on Free, more with Pro — so your agent can send a task and move on to the next one instead of sitting in a write, run and fix loop. Because the writing and testing happen off your plan, your tokens go on planning and review, letting your agent get more done on the same plan. On performance, a build is marked verified, and charged, only after it passes tests written from your acceptance criteria; code that fails its tests does not reach your agent; and the trial and error happens on Codemind's side, so it does not fill up your agent's context. The result is code that has already been tested coming back to your agent. Codemind works over MCP or REST, and the same builds are available from your agent or from your own code. It currently builds JavaScript and TypeScript, including Cloudflare Workers, Node and React. You can send a task to create new code, or change files you already have by sending the current file with the task and getting the complete modified file back. Your agent can also ask for a code review or a test run on its own. Beyond a single build, two larger modes are planned: Swarm, where your agent defines a set of tasks and a swarm builds them in parallel, verifies each one and tells you once when the whole set is done; and Ship, where you hand over a spec and the target repositories and Codemind splits it into tasks, builds them and delivers the result. Both are coming soon, Swarm with Pro. You can also estimate your savings through the analyze page linked from the site. Codemind is aimed at developers who use coding agents and want to delegate implementation work without leaving their session. It supports Claude Code, Cursor (tested through its agent CLI), Codex (CLI 0.160.1 or later; 0.27.0 has no remote MCP) and OpenCode, with Cline coming soon. It does not replace your coding agent: your agent still plans the work and edits your project, while Codemind takes the tasks it delegates and returns code that has already been tested. Languages other than JavaScript and TypeScript are not supported yet. Codemind keeps what it needs to run your builds and show you their results, with details on what it stores, for how long, and how to ask for export or deletion on the Privacy page. Taken together, Codemind's value proposition is straightforward: your agent's plan goes on planning and review, while a separate build service writes, tests and fixes the code and returns only what has passed. You are billed per verified build — $0.10 after a free allowance, with failed builds costing nothing — and you start with 100 verified builds in your first month without a card. Delegate your first task and see what comes back.
Hypervibe is a native macOS application that brings AI coding agents together on one infinite visual board. Instead of juggling terminal tabs and separate windows, you can run Claude Code, Codex, Gemini CLI and a catalog of other command-line agents side by side as nodes on a single canvas. It is built for developers who already work with agentic CLIs and want to see, organize and orchestrate many of them at once, on their own Mac, using the agent subscriptions they already pay for. macOS 14 or later on Apple Silicon is required. The starting point for Hypervibe is a simple observation: don't let a screen decide how many agents you run. Developers adopting AI coding agents quickly hit the limits of the terminal. tmux gives you panes, but as the Hypervibe comparison puts it, it does not tell you which agent is waiting for you, hand a task from one agent to another, or bring every conversation back when you reopen. Terminal tabs multiply, context is lost between sessions, and there is nowhere to plan next to the work itself. Hypervibe keeps the real terminal and adds the board around it: status per console, teams, loops, voice, and a place to plan. Each console on the board is a real terminal. Every one is a full PTY with a controlling terminal, so Ctrl-C, job control and full-screen TUIs behave exactly like iTerm. The agents run as the interactive CLIs you are already logged into, which means you use your own subscription rather than API keys, and nothing falls outside the plan you already pay for. Hypervibe runs the binaries already on your PATH, supports Claude Code, Codex, Gemini, Grok, opencode and a catalog of 34 CLIs, and also accepts any custom executable you add yourself: if it runs in a terminal, it can live in a node. Around those terminals, Hypervibe provides a set of studios and board tools. Live web tiles show a localhost preview with a real Web Inspector docked to the board. A code studio lets you browse the file tree, preview code with highlighting, and pin files as nodes on the board. A markdown studio offers an Obsidian-style vault with a file tree, autosaving editor and a force-directed link graph. A diagram studio turns diagrams of your repo into loose ink figures you can spill onto the board and export as PNG or .excalidraw. A document studio generates documents from the repo with a live preview and exports a real paginated PDF. Kanban, sticky notes, text and checklists sit beside your consoles so you can plan next to the work, and ink and markup let you draw directly on the board or mark up dropped images in place. A live git card shows your branches alongside a GitHub panel for commit, push and pull. Orchestration is where the board goes beyond a pretty desktop. You can line up a whole team in the composer and launch twelve consoles in one action. Consoles can be grouped into teams, with a mission map to keep track, and work can be handed from one agent to another. Loops know when to stop: you can trigger a console on a schedule, on idle or on output, give the loop a goal, and it retires itself once the goal is met. Voice control lets you direct the board by speaking; the voice planner turns spoken instructions into plans and the app speaks short replies back. State and continuity are handled with care. Every workspace is saved on each change, and sessions come back so consoles return exactly where they were, conversation included. A usage pill per CLI and token analytics by day and agent are built from your local session logs. Profiles with isolated homes let you run two accounts of the same CLI side by side. Project memory works at the per-repo and global level, and nothing reaches a console unless you push it. Under the hood, Hypervibe is local-first. State lives on your disk as versioned JSON and speech is transcribed on-device. Only three things talk to the servers: your sign-in, handled by Firebase Authentication; your planner commands with their board context, which the planner service sends to Groq to turn into a plan; and the text of the short replies the app speaks, which the gateway sends to Inworld to generate audio. Your microphone audio and your repositories never leave your Mac. You also have the last word: agents type, but you send. Nothing prepared for you is ever sent for you, a live console only dies by an explicit confirmed action, and each CLI's auto-approval flag is a global opt-in that is off by default. Getting started follows three steps. First, install your CLIs: log in to Claude Code, Codex, Gemini or whichever agents you use, the same way you do today, and Hypervibe runs the binaries already on your PATH. Second, open a repo by pointing Hypervibe at a folder, which becomes a board with workspaces you switch like tabs and presets that lay one out in a single tap. Third, spawn consoles by adding agent consoles as nodes and putting them to work, directing them by voice or keyboard, grouping them into teams, or leaving them on a loop. The outcomes follow from that structure. Because every console is a real terminal, developer workflows, keyboard shortcuts and full-screen tools keep working. Because each agent runs on your own subscription, there is no resold model access and no separate API key bill. Because the workspace is saved on every change, reopening Hypervibe brings back the exact arrangement and conversations you left. Because loops can watch for output, idle time or a schedule, agents can keep working without a human watching each step, and because their goals retire the loops, automated work stops on its own. Concrete scenarios fall directly out of the features described. A developer can run Claude Code, Codex and Gemini CLI side by side on the same repo to compare their output, using profiles with isolated homes to run two accounts of the same CLI at once. A larger effort can be laid out as a team of consoles on a mission map, with handoffs between agents and twelve consoles launched at once from the composer. While agents work, you can keep a live localhost preview open in a web tile with the Web Inspector docked beside it, check the git card and push from the GitHub panel, or generate a PDF document and a repo diagram from the same board. Loops handle recurring or conditional work: a console triggered on a schedule, on idle or on output, given a goal like a specific task to finish, retires itself when the goal is met. Usage analytics track token consumption by day and by agent from local session logs. Hypervibe is for one person working on their own Macs. It requires macOS 14 or later on Apple Silicon, and ships as a direct download rather than through the Mac App Store because real terminals need to spawn real processes that the App Store sandbox does not allow. The Pro plan costs USD 19 per month, billed monthly with taxes calculated at checkout, and can be cancelled anytime with a 14-day refund window on first purchases and annual renewals. Pro includes 10,000 credits every month for the voice planner and spoken replies, unlimited on-device voice dictation, 34 agent CLIs on one visual board, teams, handoffs and automated loops, the documents, diagrams and code studios, and all updates. Credits renew monthly, and if they run out, new voice planner requests and spoken replies pause until renewal while the board, consoles, voice dictation and local commands keep working. Agent subscriptions such as Claude, Codex or Gemini are paid separately to their providers, and Paddle acts as merchant of record. A Discord community run by the makers of Hypervibe is open for showing boards, reporting bugs and shaping what comes next. The takeaway is that Hypervibe turns a pile of terminal tabs into one workspace for AI coding agents. It keeps the real PTY terminals and your existing subscriptions, then adds the board, the teams, the loops, the studios and the voice control that make running many agents at once manageable, all on your Mac and with your repos never leaving it.
OpenPilot is an open-source, MIT-licensed desktop AI agent that runs locally on your machine and connects to the language model you choose. Rather than bundling its own hosted model marketplace, it acts as an AI harness: you point it at any OpenAI-compatible endpoint—OpenAI, OpenRouter, a local server such as Ollama or LM Studio, or a custom base URL—and it gains practical access to your workspace. Once connected, the agent can create and edit files, run real terminal commands, search the live web, and work through full projects from start to finish. It is built for developers and builders who want an agent that does the work inside their own environment, using their own keys and their own models, without a vendor login or platform tax. The native Windows app is available now, with macOS builds releasing soon. The problem OpenPilot addresses is the trade-off many developers face when adopting AI coding agents: powerful hosted agents often require a vendor account, lock you into a single model provider, and add what the site calls a "platform tax." OpenPilot takes the opposite approach. It describes itself as "a harness, not a hosted model marketplace," which means it supplies the tooling and the agent loop while you supply the intelligence. Because you bring an OpenAI-compatible endpoint and your own API key, you can swap providers without rewriting your workflow, keep usage tied to the keys you already pay for, and avoid being locked to models that may change, deprecate, or become more expensive. The site frames the product simply: "Own the harness. Bring the model." The agent's core capability is working directly with files. Across a workspace folder that you designate, OpenPilot can read, write, edit, grep, and glob. When you ask for a full project, it scaffolds the structure by writing files such as package.json, src/index.ts, and src/routes/users.ts, then refines the result through follow-up instructions with actions like edit_file. The site's own example shows a short sequence of write_file and edit_file calls ending with "4 files · project ready." Because the agent operates in place, you can keep iterating on the same project—adding routes, adjusting configuration, or extending existing code—rather than regenerating everything from scratch each time. File and shell access are scoped to the workspace folder you open, and the Product Hunt listing notes that you approve sensitive actions as the agent works. The terminal is a first-class tool in OpenPilot rather than a simulated code snippet. The agent can run real shell commands in your workspace, which means it can install dependencies, start servers, and run test suites. Output from those commands—including stdout—streams back into the chat, so you can watch results appear as the agent works instead of waiting for a summary. The site illustrates this with an npm test run that reports passing auth and user specs and a total of twelve tests passed. This matters because many real development tasks are not about writing code alone; they depend on feedback loops—installing a package, seeing a build fail, reading the error, and fixing it. By streaming command output back into the conversation, OpenPilot keeps that loop inside one place. OpenPilot also reaches beyond the local repository. With live web research powered by TinyFish, the agent searches and fetches pages in real time when documentation, APIs, or error messages live outside your codebase, then grounds its answer in what it actually read—the site shows an example of searching for a Node fetch timeout, fetching a docs page, and returning a cited answer plus a fix. Alongside research, the agent supports skills and long-term memory. Skills are reusable playbooks you can drop in, and preferences can be persisted in an AGENTS.md file. The agent loads these into context, and it can update memory when you ask it to. The example AGENTS.md content captures the idea: prefer TypeScript strict mode, use pnpm in this repository, and never commit .env. This gives the agent durable, project-specific guidance instead of forcing you to repeat the same instructions in every conversation. When the built-in toolset is not enough, OpenPilot supports the Model Context Protocol (MCP). You can connect MCP servers and flip them on per chat, extending the agent with the systems you already run—databases, browsers, or internal APIs. The site illustrates the configuration with an mcp.json file that defines a server named docs with a command. Because MCP servers are toggled on a per-chat basis, you can keep the agent's available tools scoped to what a given task actually needs rather than loading every integration at once. Underneath everything, OpenPilot is a bring-your-own-model harness. Setup follows three steps described on the site: add a model, open a workspace, and describe the outcome. To add a model you paste a base URL, an API key, and a model id—no account with OpenPilot is required. The settings example shows a model definition with a name, a baseUrl such as https://api.openai.com/v1, an apiKey, and a modelId. You can use cloud APIs or local OpenAI-compatible servers, with named examples including OpenAI (api.openai.com), OpenRouter (openrouter.ai), local options like Ollama and LM Studio running on localhost:11434, or your own custom gateway base URL. Then you open a workspace folder, which is where the agent receives filesystem and shell access, and finally you describe the outcome you want—build, fix, research, or automate—and review the tool trail as the agent works. OpenPilot also tracks token usage, showing session and lifetime views in the app, which helps you keep an eye on consumption against your own keys. The practical benefits follow from that design. Because there is no OpenPilot account or vendor login, there is one less credential and one less dependency in your toolchain. Because you supply a custom base URL and API key per model, you can move between providers without rewriting how you work, and you can stay portable across the models you already pay for. The token usage views give visibility into what your sessions cost. The agent is a local Electron app, so it runs on your machine, and its MIT license means the source is open—the project is on GitHub for anyone who wants to inspect it. Together these choices add up to ownership: you keep your keys, your models, and your machine. In practice, OpenPilot fits workflows where an agent needs to touch a real codebase. Scaffolding a project is the clearest case: ask for a full project and watch the file tree fill in, then refine with follow-ups. Running the development loop is another: the agent installs dependencies, starts servers, and runs tests, streaming output back into the chat so you can react to failures. Researching outside the repository is a third: when docs, APIs, or errors live elsewhere, the agent searches and fetches pages and returns a grounded, cited answer. Automating repetitive workspace tasks is a fourth, since the agent has both filesystem and shell access in the folder you opened. And when you need more, MCP servers let you extend the agent with the systems you already run, such as databases, browsers, and internal APIs. Each of these plays out inside the folder you chose, with you reviewing the tool trail and approving sensitive actions. OpenPilot is aimed at people who want the agent without the platform tax—developers and builders who refuse vendor lock-in, and who are comfortable supplying their own model endpoint and API key. The download section notes that the native Windows app is available now: a 64-bit installer and a portable executable, requiring Windows 10 or later (x64). macOS builds for Apple silicon and Intel are listed as coming soon. The Product Hunt listing describes the product as a free, MIT-licensed desktop AI agent, with Windows available now and macOS in early beta. Downloads link to the project's GitHub releases, and the site offers a getting started guide, FAQ, and changelog for further detail. OpenPilot's core proposition is straightforward: an open-source desktop AI agent that does real work in your workspace—creating and editing files, running terminal commands, searching the live web, and extending through MCP—while running on a model you choose and control. Own the harness, bring the model, and keep your keys, your models, and your machine.
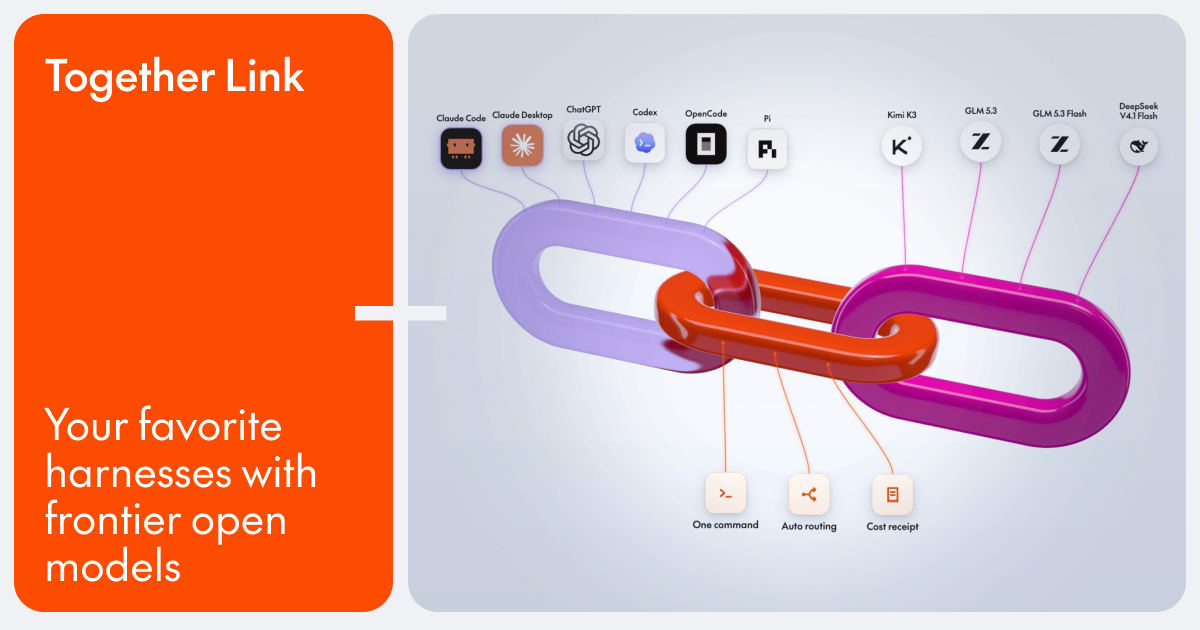
Together Link is a free, open-source tool from Together AI that connects the coding agent you already use to open models running on Together AI. Instead of switching editors, terminals, or chat apps, you keep the harness you already know — Claude Code, Claude Desktop, Codex in the ChatGPT app, ChatGPT Desktop, OpenCode, or Pi — and point it at open models such as Kimi K3, GLM 5.3, MiniMax M3, and DeepSeek V4.1 Flash. It is aimed at developers and teams who want to run their everyday coding work on affordable open models while keeping their existing login, settings, history, and habits exactly where they are. Together Link is currently in beta. Coding agents have become the place where a lot of development work actually happens, and most of that work runs on closed frontier APIs priced per token. Together Link starts from a simple observation on its own site: open models cost a fraction of closed frontier APIs per token, so moving a team's everyday coding work onto them cuts the bill by more than half. At the same time, open models such as GLM 5.3, Kimi K3, DeepSeek V4.1 Flash, and MiniMax M3 are described as handling real coding work at frontier level, and because they ship with open weights they are fully in your control. Together Link exists to make that swap practical without asking anyone to leave the tool they already use. Auto Router is the default in Together Link, and it is the setting that decides which model handles a task. When you set the model to Auto, the router reads the first task in each session and weighs it on the way through: quick work goes to a low-cost model such as GLM 5.3, while harder problems are sent to a more capable one. If you use an Anthropic API key in Claude Code or Claude Desktop, the router routes between Opus 5.5 and GLM 5.3. The site frames the trade-off in three phrases: per-session routing, lower cost, and frontier when needed. You are never locked into the router, either — you can also pick a model yourself, right from your agent's model menu. Getting started is deliberately minimal and is described as one paste, six agents, and no config edits. You install it in one quick command, then run Together Link in your terminal to launch your agent. The site lists six supported harnesses: Claude Code, Claude Desktop, ChatGPT Desktop, Codex, OpenCode, and Pi. OpenCode support requires version 2 or later, and Pi support requires version 0.80.8 or later. Each harness launches with its own command, such as togetherlink claude. Existing configuration files are left alone rather than rewritten. Together Link prints a receipt for every session. Every proxied session prints its token totals and dollar totals when you leave, so the cost of a piece of work is visible the moment it finishes. A usage report shows the last seven days of spend, and the togetherlink usage command shows your running total. You can also switch back anytime: profiles are reversible, your config is untouched, and a single command takes you back to your own setup. The site states that Together Link cuts coding agent spend by 50-80% compared with running every session on Opus 5.5. Under the hood, the approach differs slightly by harness, but the destination is the same open model lineup. For Claude Code, the gateway translates Claude Code's traffic to Together, you stay signed in, and the session prints its cost on exit. For Claude Desktop, one command installs a reversible profile and reopens the app with the Together lineup in its model menu for Chat, Cowork, and Code alike. ChatGPT Desktop opens on a separate Together Link profile and is turned off with togetherlink chatgpt off. For Codex, one command adds Together as a provider in the Codex CLI on its own profile, switched off with togetherlink codex off. OpenCode already supports Together, so one command adds your key and the router so every open model lands in its model list. For Pi, one command registers Together in Pi's model list so you can cycle between open models mid-session without leaving the terminal. Terminal agents get settings that last only for that session, while Claude Desktop and ChatGPT Desktop use their own profiles that switch back with one command. Longer answers live in the docs, which your agent can read on its own. The benefits come down to three stated reasons to use it. First, you keep the harness you already know: Claude Code, Claude Desktop, Codex in the ChatGPT app, OpenCode, and Pi, with your login, settings, history, and habits staying exactly where they are. Second, you cut agent spend — open models cost a fraction of closed frontier APIs per token, and moving your team's everyday coding work onto them cuts the bill by more than half. Third, you get frontier quality on models you control, because open weights keep those models fully in your hands. Alongside those, automatic routing means the cheap model handles the easy work and the capable model is reserved for hard problems, while the per-session receipt and seven-day usage report make the spending visible rather than surprising. Concrete workflows follow the harnesses listed on the site. A developer writing everyday code in Claude Code can point the gateway at Together, stay signed in, and see the session cost printed on exit. A Claude Desktop user can install a reversible profile and use the Together lineup in the model menu for Chat, Cowork, and Code. A Codex CLI user can add Together as a provider on its own profile while keeping sandbox and approval settings. An OpenCode user can add a key and the router so open models land in the model list beside other providers. A Pi user can register Together in the model list and cycle between open models mid-session without leaving the terminal. A team can watch the usage report to see the last seven days of spend as it moves everyday coding work onto open models and cuts its coding agent bill by 50-80% compared with running every session on Opus 5.5. Getting started requires a Together AI API key, macOS or Linux, and a supported coding agent. Installation runs with curl -fsSL https://link.together.ai/install | bash, and togetherlink configure adds your key. Together Link itself is a free, open-source tool; you pay only for model usage at Together AI's per-token rates. Published model pricing includes Kimi K3 at $3.00 in and $15.00 out, GLM 5.3 at $1.40 in and $4.40 out, MiniMax M3 at $0.30 in and $1.20 out, and DeepSeek V4.1 Flash at $0.30 in and $1.20 out. Switching between models or back to your original setup is a command away, so nothing about the arrangement is permanent. Together Link's core promise is simple: pair your favorite coding agent with affordable open models, keep the harness, login, settings, and history you already rely on, and let automatic routing, per-session receipts, and usage reporting keep costs transparent and down.
Clippo is a developer tool for Windows that turns software development into a visual command room. Instead of juggling separate terminal windows, you work on an infinite visual canvas where you assemble a team of AI agents, delegate tasks to them, and watch code progress in real time. The product describes itself as a visual orchestration canvas in which you are positioned as the tech lead and your AI agents work together in parallel. Clippo is built for developers who already use AI coding agents and command-line AI tools and who want a single place to organise, monitor, and review their work. Everything is arranged on the canvas with full freedom to lay out your workspace however you like, so the structure of the screen can reflect the structure of your project. Software development with AI agents often turns into a struggle with dozens of lost terminal tabs. Developers move between windows, copy and paste the same briefings over and over, and lose track of which agent is working on what. Context disappears between sessions, which means re-prompting and burning tokens. Clippo exists to address that specific problem: it brings visibility and organisation to an increasingly parallel, agent-driven workflow. Rather than forcing you to remember what each terminal was doing, the canvas shows everyone working side by side on a single screen, so you know instantly who is coding and who is done without window switching. The product frames itself as replacing the wrestling with terminals with a visual command room that you arrange and control. The core capability of Clippo is running your AI dev team in parallel. You can assign agents to different fronts of a project: one building the backend API, another writing test suites, and another refactoring the frontend. Because the agents are placed on a single canvas, you can see them all working side by side and immediately tell who is coding and who has finished. Clippo works alongside the AI tools you already use every day. The listed compatible tools include Claude Code, OpenAI Codex, Gemini CLI, OpenCode, Aider, and Copilot CLI, as well as local engines such as Ollama and LM Studio. WSL and Docker are supported out of the box. That means Clippo is not a replacement for your chosen agent or model; it is an orchestration layer that organises the tools you already trust while keeping them under one visual roof. Clippo keeps agents aligned with a structured project binder that lives right on the canvas. The binder has three parts. Project holds the overall architecture, stack guidelines, and team conventions. Plan provides a step-by-step implementation roadmap that you can review before execution begins. Walkthrough is an executive delivery report containing diff summaries and verification checklists. The binder is not merely documentation sitting off to the side: you connect a cable from any note to a terminal, and the agent absorbs that context immediately, with no re-prompting needed. This turns your project conventions and plans into live context that every connected agent can read, reducing the risk of agents drifting away from the agreed approach and removing the repetitive briefing loop that usually accompanies multi-agent work. Clippo includes two tools that sit directly on the canvas. ClipSurf is an embedded browser that provides web browsing and eyes for any agent. It is available to both you and your agents, and it lets terminal agents and CLI models that have no built-in web access browse documentation, research solutions online, and test the local web app they just built, live in front of you. Clippo IDE is a visual code editor built into the canvas. With it you can browse project files, review agent-generated code with syntax highlighting, inspect Git diffs, and make quick edits before committing with a single keystroke. Together these tools keep browsing, inspection, and review inside the same visual workspace instead of scattering them across separate applications, and they let you stay in full control of your repository. Persistent memory with local AI is one of Clippo's most distinctive capabilities. Agents no longer lose context between sessions, because Clippo keeps a local memory that learns your project over time. It stores architectural decisions, solved pitfalls, and coding standards. A lightweight local model retrieves relevant memories on demand. Because retrieval is local and selective, this cuts token usage and keeps context across sessions. In practice this means that decisions you made once, such as a convention, a workaround, or a lesson learned, remain available to future agent sessions rather than being re-explained each time. The memory layer is the mechanism behind the stated token savings, and it is also part of why Clippo can describe itself as private: your files, notes, and prompts never leave your PC. The product's overall approach is visual and local. Everything happens on an infinite canvas where you arrange notes, terminals, IDEs, and browsers as nodes, then connect them with cables so that connected agents absorb the relevant context immediately. Because Clippo works alongside existing CLIs and local engines, you choose which agents and models run and how they are arranged. Privacy is central to the design: the content states zero account creation, zero login, and zero tracking, and that your files, notes, and prompts never leave your PC. Clippo also positions itself as lightweight and fast, explicitly contrasting itself with bloated web wrappers that eat up RAM. It opens fast, stays light, and leaves CPU and memory free for compiling and development, a meaningful detail when the same machine is running multiple coding agents at once. Taken together, these capabilities produce a set of stated outcomes. You gain visibility, because instead of lost terminal tabs you see parallel agents on one screen and know who is coding and who is done. You gain alignment, because the project binder and cable-connected notes feed context to agents without repeated briefing. You gain efficiency, because persistent local memory keeps context across sessions and cuts token usage. You gain control, because Clippo IDE lets you inspect agent-generated code, review Git diffs, and edit before committing. And you gain privacy and performance, with no accounts, no logins, and no tracking, in a lightweight application that leaves resources free for compiling. The overall promise is that you step up as tech lead of your own AI engineering team. Several concrete scenarios follow directly from the description. In a multi-front build, you assign one agent to build the backend API, another to write test suites, and a third to refactor the frontend, watching all three side by side on the canvas. In a planning workflow, you write architecture and conventions as Project notes, connect them to the relevant terminals so each agent absorbs the context, and let the Plan roadmap be reviewed before execution. When an agent needs information it cannot reach on its own, ClipSurf lets it browse docs or research solutions online, and it can test the local web app it just built in front of you. Before committing, you open Clippo IDE to review agent-generated code with syntax highlighting and inspect Git diffs. Across sessions, memory retrieval restores architectural decisions and solved pitfalls so returning to a project does not mean starting from zero. Clippo is aimed at developers who work with AI coding agents and command-line AI tools and who want to orchestrate them rather than manage a pile of terminals. It runs on Windows 11, version 22H2 or higher, x64, and is distributed through the Microsoft Store, where it is developed by Thiago Grião. Compatible tools listed in the description include Claude Code, OpenAI Codex, Gemini CLI, OpenCode, Aider, Copilot CLI, and local engines such as Ollama and LM Studio; WSL and Docker are supported out of the box. Pricing follows a free start: the free plan includes a complete workspace with unlimited terminals, notes, Clippo IDEs, ClipSurfs, and Spaces inside it. To work across multiple projects at once, the Clippo Pro add-on unlocks unlimited workspaces through a one-time purchase from the Microsoft Store. The store listing notes that Clippo offers in-app purchases. Clippo's primary value proposition is organisational and visual: it turns an increasingly parallel, agent-driven development workflow into something you can see, arrange, and steer. By placing parallel agents, project context, an embedded browser, a code viewer, and persistent local memory on a single infinite canvas, it removes the tab-chasing and repeated briefing that slow agent-assisted development down. It does so without taking over your choice of AI tools, since it works alongside the CLIs and local engines you already use, and without sending your work to the cloud, with no account, no login, and no tracking. For developers on Windows who want to act as tech lead of their own AI engineering team, Clippo's promise is a command room where the whole team, human and artificial, is on one screen.
Claude Haiku 5.5 is Anthropic's fastest, cheapest, and most capable small model, announced on October 7, 2026. It is designed for high-volume, cost-sensitive tasks and reliably handles quick, repetitive workloads such as summaries, compactions, database queries, and classification requests. The model also pairs well with Anthropic's larger models, Opus 5.5 and Sonnet 5.5, acting as a subagent on coding work. Because it is Anthropic's fastest model to date, it is positioned for speed-sensitive workloads including live customer support and browser use, giving developers a small model they can run often rather than sparingly. The launch addresses a practical problem in production AI: many of the requests that dominate real traffic are short, repetitive, and narrow, yet teams have historically paid frontier-model prices to serve them. Anthropic notes that prompts up to 100,000 tokens make up around 90% of requests to the previous Haiku model, which means the bulk of day-to-day workloads are the kind that do not need a large model. Claude Haiku 5.5 is priced far lower than Haiku 4.5: on average, it now costs around 75% less to run. By footnote, it is priced 90% lower than Haiku 4.5 for requests up to 100,000 tokens and 50% lower for requests over 100,000 tokens. That calculation also accounts for the model's updated tokenizer, similar to those of Sonnet 5.5 and Opus 5.5, which uses slightly more tokens per task. Claude Haiku 5.5 brings substantial benchmark gains over Haiku 4.5 across knowledge work, computer use, reasoning, agentic coding, and visual reasoning. On GDPval-AA v2.1, a knowledge-work evaluation, it scores 1,620 versus 735 for Haiku 4.5, 1,437 for GPT-6 Luna, and 1,840 for Sonnet 5.5. On AA-Briefcase v1.1 it scores 1,578 against 614 for Haiku 4.5, 1,336 for GPT-6 Luna, and 1,824 for Sonnet 5.5. On the OSWorld 2.1 computer-use benchmark (offline subset) it reaches 72.4% versus 15.7% for Haiku 4.5, 48.9% for GPT-6 Luna, and 83.9% for Sonnet 5.5. On Humanity's Last Exam, a multidisciplinary reasoning test, it scores 45.9% without tools and 57.4% with tools, compared with 10.2% and 18.7% for Haiku 4.5 and 56.9% and 64.5% for Sonnet 5.5. On Terminal-Bench 4.0 agentic coding it scores 39.2% versus 0.0% for Haiku 4.5 and 70.6% for Sonnet 5.5, and on FrontierCode 1.1 (Main) it reaches 46.4%, while Chartography visual reasoning lands at 46.4% without tools versus 6.4% for Haiku 4.5. Full evaluation details are documented in the Haiku 5.5 System Card. Haiku 5.5 is the first Haiku-class model to come with an adjustable effort setting. As with Anthropic's other models, users can decide whether to optimize for cost or intelligence by choosing an effort level, with options charted across Low, Med, High, Xhigh, and Max. Anthropic publishes accuracy-versus-cost charts for three benchmarks at each setting: OSWorld 2.1 for computer use, GDPval-AA for knowledge work, and Humanity's Last Exam for multidisciplinary reasoning. OSWorld 2.1 measures how well agents can operate a real computer to finish long, multi-step tasks; GDPval-AA v2.1 evaluates agents on real-world professional work across 44 occupations; and Humanity's Last Exam tests expert-level academic knowledge and reasoning. This effort setting lets teams tune the trade-off between per-attempt cost and task accuracy without switching models or rewriting their workloads. Anthropic reports that Claude Haiku 5.5 shows major improvements across almost all of its alignment evaluations relative to Haiku 4.5, with far fewer instances of misaligned behavior and a lower willingness to cooperate with misuse; a dedicated system card describes the evaluation process and results in more detail. The model's cybersecurity safeguards are more restrictive than Haiku 4.5's but somewhat less restrictive than those applied to other recent models. In cybersecurity, they permit a wider range of defensive tasks than the safeguards for Sonnet 5.5 but still block penetration testing and other techniques more likely to be used by attackers. Its biology safeguards are the same as those for Sonnet 5, Sonnet 5.5, and Opus 5: they allow research biology questions but restrict access to requests judged likely to cause harm. Organizations working on wider-ranging biology and cyber activities can apply to the Life Sciences Verification Program and the Cyber Verification Program. The model's distinct approach is to combine a small footprint with a configurable effort dial and a clear role as a cost-efficient companion to larger Claude models. Anthropic explicitly frames Haiku 5.5 as best suited to more narrowly scoped tasks that might otherwise have been cost-prohibitive with previous versions of Claude, such as compaction, summarization, or subagent work, while Sonnet 5.5 and Opus 5.5 remain better choices for complex agentic coding tasks like those measured by Terminal-Bench 4.0. In practice this means a larger model can lead a task while Haiku 5.5 subagents handle the high-volume supporting steps. Anthropic also improved the value of its wider model range at the same time: Sonnet 5.5's cache reads were halved to $0.10 per million tokens, reducing the cost of Sonnet 5.5 on most agentic tasks by around 20%, and new monthly API credits were introduced for Max and Team subscribers. For users, the headline benefits are lower cost and lower latency at scale. The pricing table shows Haiku 5.5 at $0.01 per million tokens for cache reads on prompts up to 100,000 tokens and $0.05 over that, $0.125/$0.625 for cache writes, $0.10/$0.50 for input tokens, and $0.50/$2.50 for output tokens, against Haiku 4.5's $0.10, $1.25, $1.00, and $5.00. Early customer testing reported results consistent with the performance and cost improvements shown in the benchmarks. Asana measured over a 30% reduction in latency for task completions and up to 2.5x faster inference per agent turn. Box saw Haiku 5.5 score 11 points higher than Haiku 4.5 at about half the latency. The combination makes high-volume work affordable enough to run often rather than selectively. Anthropic and its early customers describe concrete workflows. AlphaSense's Ask in Document feature runs about 8 million calls a week in production answering very specific questions on top of one or a few documents; across 400 queries, Haiku 5.5 scored 0.84 versus 0.76 for Haiku 4.5. Box plans to use it on analytical work that runs at scale, from cost reports to financial summaries and weekly recurring reviews, across large volumes of enterprise content. HubSpot tests models on CRM tasks such as reporting on deals using simulated portals; Haiku 5.5 scored 92.8% averaged over three runs, the best result on that suite, and on a CRM audit task identifying stale but ambiguous records it was fastest to complete the task with the highest hit rate and the lowest false positive rate. Rogo uses it for quick lookups, subagents, and summaries, for example a Haiku 5.5 subagent pulling a segment revenue line from a 10-K while a bigger model builds the deck. Cognition offers Haiku 5.5 as a sidekick in Devin Fusion, holding a top-tier FrontierCode score of 66.2 while cutting cost and latency, available today in the Devin CLI with Opus 5.5 as the lead. Asana deployed it for AI Teammates use cases such as triaging bugs, setting up projects, and searching large portfolios to surface high-risk or overdue work. Claude Haiku 5.5 is available now on all platforms, including Amazon Web Services, Google Cloud, and Microsoft Azure, and developers on the Claude Platform can get started with the identifier claude-haiku-5-5; Anthropic provides a migration guide for details. For developers, Anthropic updated its Claude Python and TypeScript SDKs to add support for computer use and browser use in beta, noting that Haiku 5.5 is especially well-suited to these tasks given its combination of speed, capability, and price. Alongside the launch, Anthropic rolled out a new monthly API credit to Max and Team subscribers for use on the Claude Platform: Max 5x users receive $100 in credits per month, Max 20x users receive $200, and Team subscribers receive up to $500 pooled across their users. Credits can be used on any Claude model and are designed to let users experiment with building tools, apps, and agents that call the API. Claude Haiku 5.5's value proposition is straightforward: it is the cheapest, fastest, and most capable small model Anthropic has released, aimed squarely at high-volume, cost-sensitive work. With large benchmark gains over Haiku 4.5, an adjustable effort setting for tuning cost against intelligence, substantially lower token pricing, and availability across major cloud platforms, it gives teams a model they can run frequently for summarization, classification, lookups, subagents, customer support, and browser and computer use, while reserving larger Claude models for the most complex tasks.
ParakeetAI is a real-time AI interview assistant that gives you the right answer while you are still talking. According to the website, it is built for interviews, sales calls, client meetings, or any conversation where freezing up isn't an option. Rather than being only a preparation tool, ParakeetAI works both before and during the conversation: you rehearse ahead of time and then, on the day, it listens to the real interview and drafts your answers live. The product is presented as the "#1 Real-Time AI Interview Assistant" and the "#1 AI Interview Assistant on SimilarWeb," and the site says it is trusted by 1.5M+ people with a 4.86 rating from 340K+ reviews. Its stated purpose is to take you from "what will they ask?" to "I nailed it." The problem ParakeetAI addresses is the familiar moment when your mind goes blank during an important conversation—what the website calls freezing up. That moment is costly in interviews, sales calls, and client meetings, where the answer matters in real time and there is no chance to redo it. Traditional interview preparation is difficult because candidates do not know exactly what will be asked, and even solid preparation can fall apart under pressure. ParakeetAI positions itself as both a rehearsal partner and a live safety net, combining practice tools with in-conversation assistance so that a shaky moment does not become a lost opportunity. Two of the preparation features are the Question Bank and Mock Interviews. The Question Bank lets you browse the questions real candidates were asked, organized company by company and ranked by how often they come up, so you can spend your time on the questions most likely to surface rather than guessing. Mock Interviews take that further by letting you practice out loud against an AI interviewer that asks questions, listens, and follows up on your answers. Afterwards, you can read the transcript back to see how you actually responded. The first mock interview is free, which lowers the barrier to trying the rehearsal workflow. ParakeetAI also bundles a Resume Maker and a Headshots tool. The Resume Maker builds a resume tailored to the role you are chasing, so that when you reach the call the story you tell starts from the right foundation. Headshots turn one photo into studio-quality headshots for LinkedIn and your resume, keeping the same face while giving you a pick of look. Together these two features round out the preparation side of the product: not just what you say, but the materials that represent you before and around the conversation. For technical calls, the site describes Full Coding Support: ParakeetAI listens for coding questions and reads code shared on your screen, then talks the approach through with you while the call is still going. Under the hood, the platform uses a state-of-the-art transcription model for blazing-fast speech recognition, described as a highly accurate model at recent breaking speed. Its AI answers are generated by choosing between the best LLMs available—OpenAI, Claude, and Gemini are named on the page—in order to provide the most accurate responses. The live interface shows a listening timer, an "Auto Answer" toggle, and Clear and Answer controls. A defining part of ParakeetAI's approach is privacy and undetectability. The website promises "real-time answers without distraction or judgment—completely undetectable, completely yours," and then lists five specific invisibility features. It is invisible on screen share, so you can share your screen while ParakeetAI stays hidden from others. It is invisible in the Dock, with no icon or activity indicator. It is invisible in Activity Monitor, with no visible process name or icon. It is invisible to tab switching, so platforms cannot detect that you moved away. And it offers cursor undetectability, so your cursor stays unchanged when hovering, clicking, or adjusting settings. The site states that these are checked on supported platforms. ParakeetAI lists eight platforms where its invisibility has been verified: Zoom, Microsoft Teams, Google Meet, Webex, Lark (Feishu), Amazon Chime, CoderPad, and HackerRank. Each is marked "Verified," and the page notes that the checks were done recently—"Checked 49 days ago"—with an invitation to open a platform and watch the test yourself. These are the environments where interviews, sales calls, and meetings commonly happen, so the verification is meant to reassure users that the assistant remains hidden in the tools they already use rather than only in lab conditions. Overall, ParakeetAI's approach is to run alongside your conversation, not instead of it. It listens, transcribes quickly, and drafts answers while the call is still happening, and it is designed to stay out of sight so it does not intrude on the moment or reveal itself to other participants. The workflow spans the whole arc of an opportunity: build your materials with the Resume Maker and Headshots, study the Question Bank, rehearse in Mock Interviews and review transcripts, then enter the real conversation with live assistance and coding support. Sessions are managed from a dashboard where you can create sessions, see mode, duration, credits used, and state, and save or view transcripts afterward. The stated benefits center on confidence and accuracy. The core promise is getting the right answer while you are still talking, which is aimed at eliminating the freeze-up that derails high-stakes conversations. Testimonials quoted on the page describe it as a "confidence boost," a "game changer," and "like having the ultimate backup when your brain decides to lag." Reviewers also highlight super-fast transcriptions, spot-on AI answers, and a pay-as-you-go model rather than a subscription. Read together, these point to outcomes such as calmer delivery, better-prepared answers, and more polished application materials. Use cases described in the content include job interviews—including technical interviews with coding questions and screen-shared code—plus sales calls and client meetings. The dashboard illustrates sessions set up for roles such as Software Developer, Systems Architect, Machine Learning Engineer, Backend Engineer, Full Stack Developer, DevOps Engineer, Payments Engineer, GPU Systems Engineer, Product Designer, and Site Reliability Engineer, across companies including Anthropic, Microsoft, Apple, OpenAI, Google, Meta, Sumo Logic, Stripe, NVIDIA, Airbnb, and Datadog. Sessions can run in "Interview" or "Regular" mode, with recorded durations, credits used, save-transcript options, and states such as Live, Ready to Start, and Ended. The site says ParakeetAI is used by 1.5M+ people, carries a 4.86 rating from 340K+ reviews, and was named the #1 AI Interview Assistant on SimilarWeb. Its tech stack includes leading LLMs—OpenAI, Claude, and Gemini—alongside a state-of-the-art transcription model. It appears to be available on the web, on mobile (shown "running on mobile"), and as a desktop app, since the interface includes an "Open Desktop App" option. Pricing described in the content includes a Free Plan that lets you "start a 10 min free session or buy credits for full-length calls," and the first mock interview is free; a reviewer notes it is "not a subscription; just pay as you go." A limited-time offer advertises code PH50 for 50% off. In short, ParakeetAI pairs real-time, undetectable AI assistance with a full set of interview preparation tools—a company-ranked Question Bank, AI Mock Interviews, a Resume Maker, and Headshots—so job seekers and professionals can walk into interviews, sales calls, and client meetings with answers ready and confidence intact.
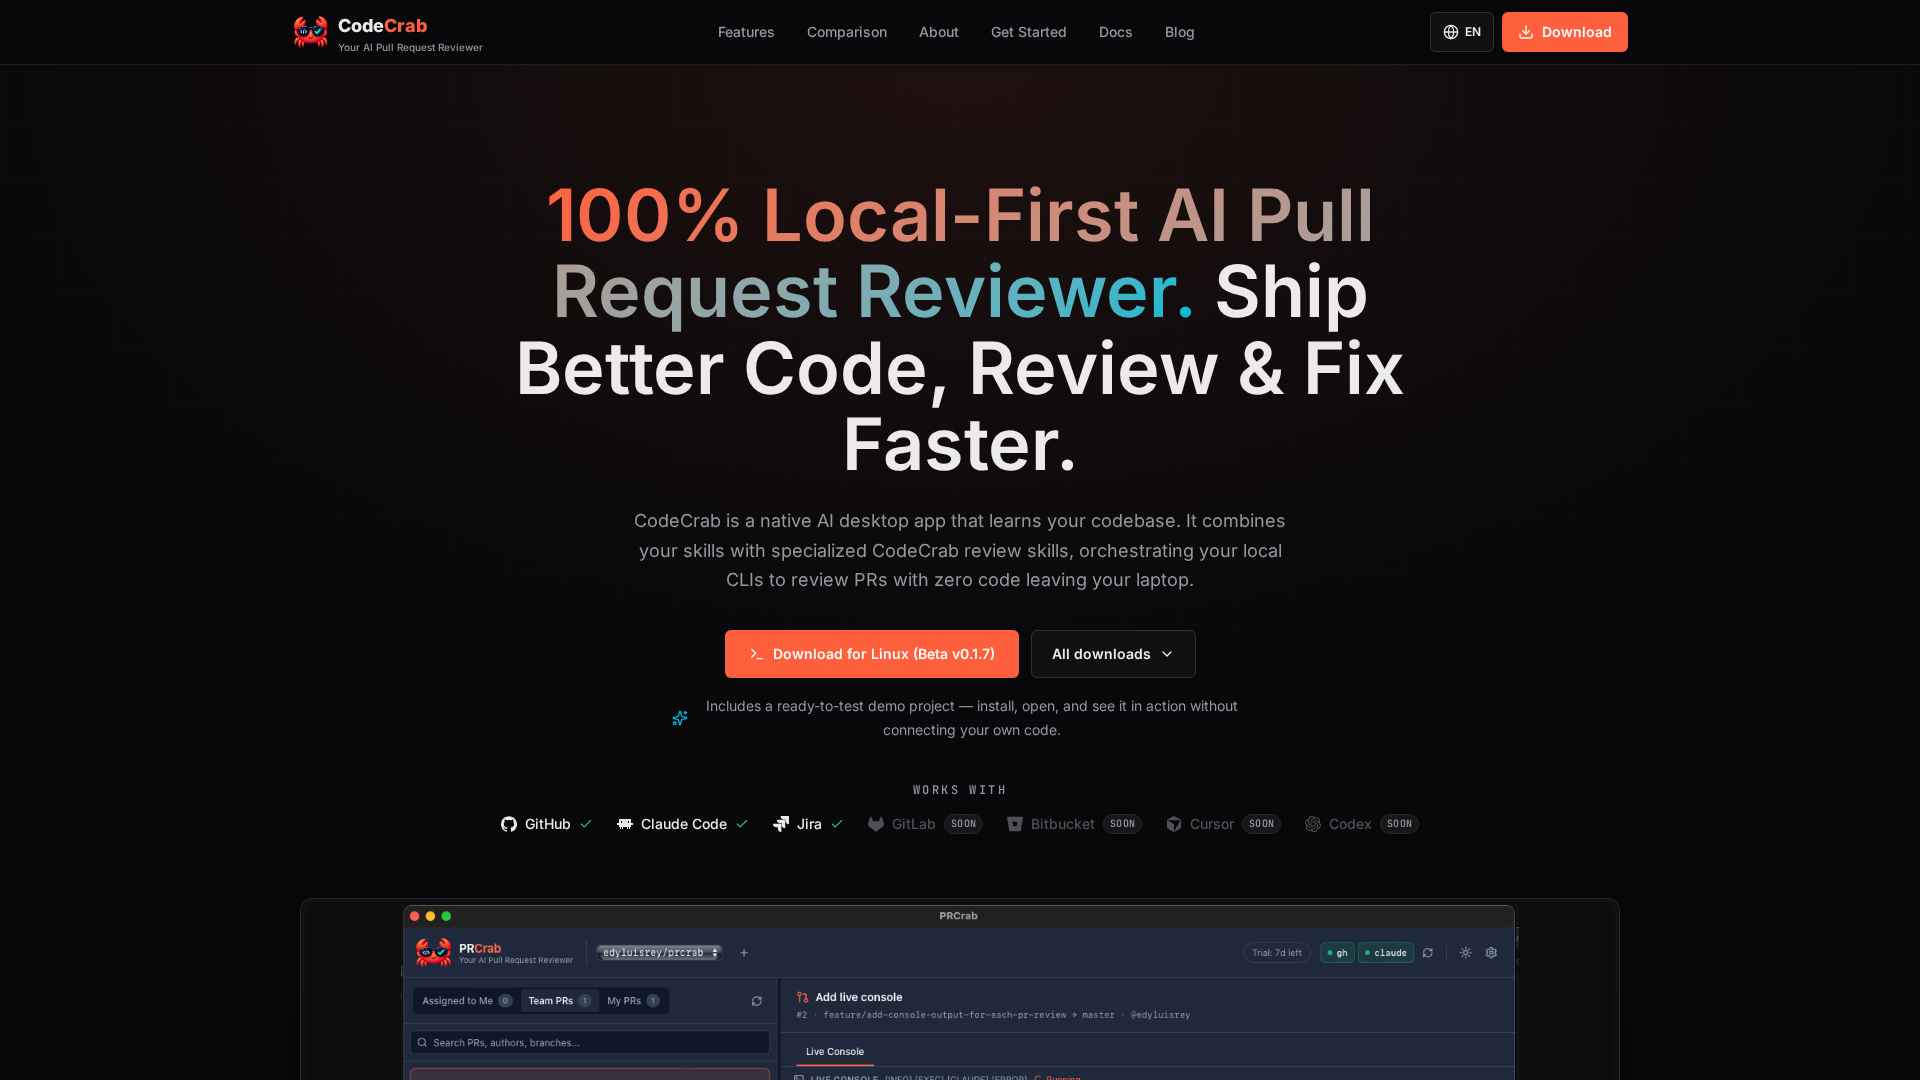
CodeCrab is a native, local-first AI desktop application that reviews pull requests in seconds by orchestrating the CLIs already installed on your machine. It is built for software engineers who review code daily and want to move faster without sending a single line of their source code to a cloud service. The app learns your codebase, combining the skills you already use with specialized CodeCrab review skills, and applies that understanding across three main moments in the development workflow: reviewing a teammate's pull request, responding to feedback on your own pull request, and reviewing local changes before a pull request even exists. Everything runs client-side on your laptop, and the product is currently available as a free public beta for Linux. The problem CodeCrab addresses is the shift in the engineering bottleneck. As AI toolsets generate code at unprecedented speeds, the author of the product — a software engineer with more than 14 years of experience, including years building systems at Google and Pinterest — observed that the primary constraint moved from writing code to reviewing pull requests efficiently. Deep review is hard: reviewers must hold full repository context in mind, evaluate diffs, and catch logic bugs, risky patterns and regressions before approving. Cloud-based review bots add a second concern: to review your code, they require your source to be uploaded and processed on vendor cloud servers. CodeCrab was built initially as a personal tool to perform deep, Staff-level code reviews fast, without uploading sensitive private code to third-party servers. When you open a pull request from a colleague, CodeCrab walks through the diff with you and maps AI observations directly onto the changed lines, so you can catch bugs, risky patterns and regressions before hitting "Approve". The review is not limited to the diff itself: CodeCrab reviews against your entire local repository, including types and the test suite, so its observations account for full codebase context rather than isolated changed lines. Because the review is 100% local-first, it can detect logic bugs and regressions without uploading a single line to the cloud. The live review interface shows a file tree, a diff viewer and inline AI observations, and features clear changed-file tracking with inline observation badges for clean multi-file diff inspection and precision navigation. When a teammate leaves an observation on your own pull request, CodeCrab runs a deep investigation for you. It digs through the code around every comment, connects that code with your project's context, and helps you understand — as precisely as possible — what the observation really means and what the correct solution looks like. The investigation is deep and read-only, covering every reviewer observation on the diff, so nothing changes on your branch while you are still reasoning about the feedback. From there, CodeCrab can propose an assisted fix on your local branch, and that fix is verified against your own test suite before it is applied. The result is a workflow that turns review comments into the right solution rather than a guess. CodeCrab also reviews your local changes before a pull request exists. While you are still working locally, you can run a read-only review of your in-progress changes; CodeCrab detects errors early, investigates every finding as deeply as needed, and helps you apply the right fix while the context is still fresh. Because this happens before anyone sees the diff, the pull request you eventually open ships cleaner, higher-quality code. The pre-push review keeps the same privacy posture as everything else in the app: your local changes are analyzed locally, so you get early feedback without exposing unfinished work to a cloud service. The product describes this as catching bugs before the pull request even exists. CodeCrab is designed to plug into your existing workflow rather than replace it. Connect any repository and CodeCrab learns its rules and patterns, building a per-repo review profile that powers specialized review agents and custom skills. That means reviews are tuned to your codebase, and your own local skills can be reused, combined with CodeCrab's skills, and extended as far as you need. The app integrates with GitHub, Claude Code, Jira and GitLab today, with Bitbucket, Cursor and Codex listed as coming soon. Under the hood, CodeCrab orchestrates your local CLIs: it uses your own GitHub CLI login (gh) rather than requiring org-wide OAuth admin permissions, and it works with your local Claude Code and Cursor setups instead of locking you to a vendor's fixed model wrappers. A Live Execution Console displays real-time stdout and stderr, so the execution pipeline is transparent rather than an opaque black box. Privacy is the product's core promise. CodeCrab uses a 100% on-device architecture with zero-code uploads: your source code never leaves your laptop or passes through external cloud databases, and the product is described as compliance-ready for strict corporate environments where no code may be sent to third-party AI clouds. Control follows from that architecture: CodeCrab is read-only by default and never commits, pushes, or posts public GitHub comments without your explicit permission. When it does propose changes, it runs your native test suite — cargo test, pytest, npm test — before applying them, and it offers 1-click local fixes in the form of verified code patches ready to apply directly to your local branch. The app is a native desktop application with instant, lightweight performance, minimal RAM consumption and instant startup. Economically, it reuses what you already pay for: it connects directly to the tools and subscriptions you already own, such as Claude Code and Cursor, and it gives you full model and cost control so you can choose which AI models to run and control exactly how much you spend on code reviews. These capabilities map onto concrete moments in a day-to-day engineering workflow. In a typical review cycle, a developer opens a colleague's pull request in CodeCrab, walks the diff with inline AI observations mapped to the changed lines, and reaches an approval decision with full repository context rather than a diff-only view. On the other side of the same workflow, a developer whose pull request has received reviewer comments uses CodeCrab to investigate each observation deeply in read-only mode and then apply an assisted fix on the local branch, verified against the test suite. Between those two moments, the pre-push review covers local, uncommitted work so errors are found before the pull request exists. Teams working in strict corporate environments use the same app because no code is uploaded anywhere. And for anyone evaluating the product, the bundled demo project lets you install, open and see it in action without connecting your own code. CodeCrab is a native desktop application, currently distributed as a free public beta, with a Linux download available at Beta v0.1.7 (amd64 AppImage) and additional downloads listed on the site. It is the product of an engineer named Edy, who has more than 14 years of experience, including years building systems at Google and Pinterest, and who describes CodeCrab as initially a personal tool that is now being actively refined during public beta based on real engineering workflows. The product integrates with GitHub, Claude Code, Jira and GitLab today, with Bitbucket, Cursor and Codex listed as coming soon. Its stated points of integration include your local Claude Code and Cursor setups, your local custom skills, the GitHub CLI (gh) for authentication, and native test runners such as cargo test, pytest and npm test. CodeCrab's value proposition is narrow and clear: it brings deep, fast, local AI pull request review to a desktop app that never uploads your code. By orchestrating the local CLIs and subscriptions you already own, mapping observations onto your diffs, investigating reviewer feedback deeply, and verifying fixes against your own tests, it accelerates review without asking you to trade away privacy or control. For engineers and teams who care where their source code ends up, CodeCrab offers the same kind of review acceleration associated with cloud bots, delivered from a 100% client-side architecture.
Reviu is a native desktop app for reviewing the code your coding agents write. It is built for developers who run agentic coding tools such as Claude Code, Codex, or Gemini and want a dedicated place to inspect what those agents produced before it lands on a branch. Rather than treating an agent run as a disposable chat, Reviu turns each task into a durable session with its own conversation, branch, terminal, checkpoints, file edits, and review queue. From that session you watch the agent work, review every diff, send line comments back, and then finish the branch with real Git - staging, rebasing, committing, and pushing without leaving the app. Reviu sums this up by calling itself the review app for code your agent writes. Since the first launch, Reviu was rebuilt from a Git client with an agent panel into a review workspace for coding agents. The gap it targets sits between agent output and a clean commit: an agent can produce a large diff quickly, but a human still has to read it, decide what to keep, and turn those decisions into a tidy branch. Reviu states the premise directly - agent work only matters when it becomes a clean commit. The app is therefore built around the loop that starts before the commit: the agent works in a durable session, you review the diff, send fixes back from inline comments, then finish with hunk staging, interactive rebase, conflicts, history, and push in the same application. Reviu also positions itself next to existing Git tooling rather than replacing it, inviting users to keep the Git tools they already like and add the missing agent review layer. Reviu manages sessions like real work. Each task becomes a durable session rather than a disposable chat, carrying its own conversation, branch, terminal, checkpoints, file edits, and review queue, and you can switch between sessions without stopping running agents. Parallel worktrees let you run multiple agents at once without letting one task dirty another checkout - the product shows a main checkout alongside separate agent worktrees for tasks such as discount work and tax rounding. Attention states make the status of each session visible, showing what is running, waiting, failed, or ready for review. Readable agent activity keeps commands, reads, edits, permissions, and failures grouped as reviewable events, so an edit of forty-two added and eight removed lines in a source file, or a test command run, shows up as an event you can inspect rather than as an opaque log line. Diff review is the core of the app. You inspect the diff and leave line comments on local changes, including file, line, and side context, then batch those comments and send them back to the agent. The content illustrates this with a review queue on a feature branch where three comments are selected: a request to apply flat discounts before percentage discounts, a fix for discount order, a new rounding test, and a rename for an unclear helper. Once the comments are sent, the agent can act on them directly. Reviews happen against an isolated worktree so parallel agent tasks stay out of your main checkout. Reviu also describes the ability to checkpoint or undo turns, giving turn-level control over what the agent changed. Underneath the review layer is real Git. You shape the diff by staging the hunks you trust, unstaging others for another pass, and restoring the rest. You clean the branch before the pull request exists by squashing, fixup, dropping, and reordering commits. You recover from messy states by resolving conflicts, continuing rebases, stashing work, cherry-picking, and undoing mistakes. Every surface in the app follows the checkout, so changes, history, terminal, and review stay in sync with whatever branch is active. Git actions are reachable from the command palette in the same keyboard-first flow as the rest of the app: commit, amend commit, push, force push with lease, interactive rebase, and pop stash. The result is staged hunks, rewritten history, and a branch you can push with confidence. Reviu Pro adds GitHub. The paid tier is for developers whose local agent work ends in a GitHub pull request review and merge. A pull request dock brings your branch, agent session, working tree, review threads, checks, and merge button into one window, so you can use GitHub without turning every review into a browser tab hunt. An inbox surfaces events such as a requested change, a CI run finishing, or a reply in a file. When checks have passed and the review is approved, the dock shows that the merge is ready and lets you create a merge commit. The PR follows your branch: check out a branch and Reviu finds its pull request, or helps create one from the header. You can review GitHub diffs locally by opening PR files in the editor, commenting inline, replying to threads, and submitting a full review. Merging works like GitHub would, with squash, merge, or rebase using GitHub's generated title, message, bullets, and trailers. A browser extension adds an Open in Reviu button to GitHub pull requests, opening the branch locally ready for diff review, files, and terminal; it is available for Firefox and Chrome. Reviu's approach is local by default. It launches the agent CLI you already installed and signed into, so agents run as local processes on your machine with your existing subscription and no API key to paste. Your code and the agent process stay on your machine; Reviu does not run agents in the cloud and does not meter your agent usage. It drives any agent from the official Agent Client Protocol registry, naming Claude Code, Codex, Gemini, Copilot, Cline, and about twenty others. The app itself is fully native, built with Rust and GPUI, a Rust-based GPU-accelerated UI framework - no Electron and no webview. No account is required for agent sessions or local Git features; signing in is only needed for the GitHub integration in Reviu Pro. For users, the benefit is a single place where agent output becomes a reviewed, clean branch. The review queue turns scattered comments into batched instructions the agent can act on, isolated worktrees keep parallel agent tasks from interfering with each other, and attention states make it obvious which sessions need you now. Because Git stays close to the diff, review decisions become staged hunks, rewritten history, and a pushable branch rather than a manual cleanup exercise after the fact. On Pro, the pull request dock collapses branch, threads, checks, and merge into one window, reducing context switching between the local workflow and GitHub. Concrete workflows described in the content include running several agents in parallel on separate tasks - for example discount work, tax rounding, and cart property tests - each in its own worktree, and switching between those sessions while they continue running. Another is reviewing an agent's diff on a feature branch, leaving line comments with file and side context, and sending a batch back to the agent so it can correct the order of discount calculations or add a rounding test. A third is finishing a branch before any pull request exists: staging trusted hunks, reordering or squashing commits, resolving conflicts, and pushing. Pro workflows include finding a branch's pull request from the header, reviewing and commenting on PR files locally, submitting a review, watching checks and notifications in the inbox, and merging with squash, merge, or rebase. The browser extension supports starting in GitHub and finishing the local review in Reviu. Reviu is aimed at developers who use coding agents on their own machines and want to review that work with real Git tooling. It integrates with agents from the Agent Client Protocol registry, with GitHub on Pro, and with Firefox and Chrome through the Open in Reviu extension. It runs as a native desktop app on macOS for Apple Silicon and Intel, on Windows for ARM64 and x64, and on Linux through a terminal install command. Pricing is straightforward: the local agent review tier is free at $0 and covers agent sessions with ACP registry agents, parallel worktrees and durable session state, diff review with comments sent back to the agent, and local Git including staging, rebase, conflicts, and terminal. Pro is $9 per month or $79 per year, which the site lists as a 27% saving, with a 14-day free trial and cancel anytime; it adds the pull request dock with checks and merge, GitHub review comments and submit review, and inbox notifications and the browser extension. Mobile access and remote over SSH to servers and VPS are listed as planned rather than available today. Reviu occupies the space between an agent writing code and a branch being merged. It keeps the review loop - durable sessions, isolated worktrees, inline comments sent back to the agent - free on the desktop, and adds GitHub pull requests, checks, merge, and notifications as a Pro layer, all built on real Git and a native Rust and GPUI app rather than a webview.